Xiaomi MiMoOfficial
823.8K/mo
Xiaomi's multimodal model family for reasoning, vision and voice
AI AgentEditorial score: 4.4Contact for Pricing35% direct

Contact for Pricing
Compare AI products across 459 workflows using traffic estimates, features, and alternatives.
“Vision models”·944 results
Start overXiaomi's multimodal model family for reasoning, vision and voice
MiniMax's open-weight model for turning prompts into images

One subscription for 100+ leading AI models across text, image, video and audio
One subscription for 100+ leading AI models across text, image, video and audio

The AI lab behind some of the most striking text-to-image and video models
The AI lab behind some of the most striking text-to-image and video models

Open AI research for everyone — datasets, models and tools, free for all

One API for 1,500+ production-ready generative media models
AI creative agents for text-to-video, image-to-video, and visual production
AI creative agents for text-to-video, image-to-video, and visual production
Free AI dog breed identifier that matches your dog's photo against 120 breeds in seconds
Free AI dog breed identifier that matches your dog's photo against 120 breeds in seconds

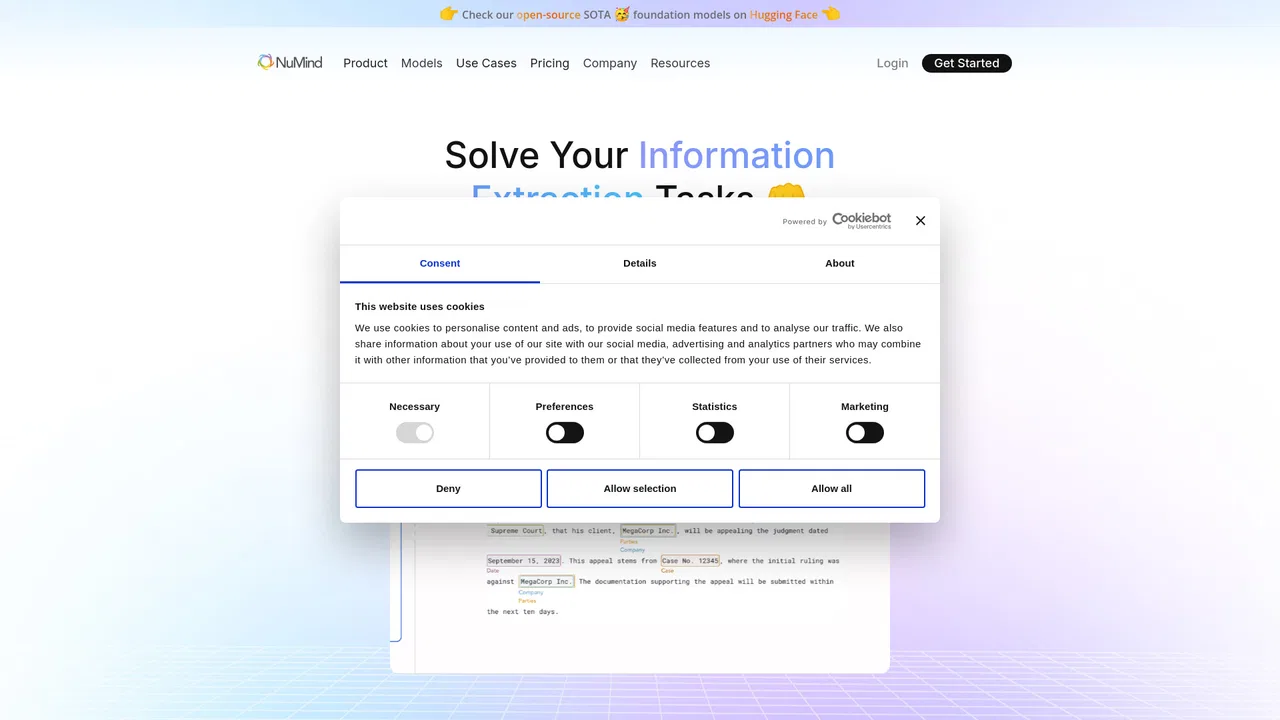
Frontier VLMs for document extraction, structured JSON and OCR

Google DeepMind's #1 frontier AI model (Gemini Carbon 4) for long-horizon agentic coding, cybersecurity defense, and 1M-token multimodal reasoning.
Google DeepMind's #1 frontier AI model (Gemini Carbon 4) for long-horizon agentic coding, cybersecurity defense, and 1M-token multimodal reasoning.
One workspace for 50+ AI image, video, and audio models
One workspace for 50+ AI image, video, and audio models
Train custom image classification and object detection models with your own labeled images
Train custom image classification and object detection models with your own labeled images

Human-validated training data and evaluation services for frontier AI models

AI-native cloud for building and scaling enterprise AI
Open generative models for image, video, audio, and 3D
Open generative models for image, video, audio, and 3D

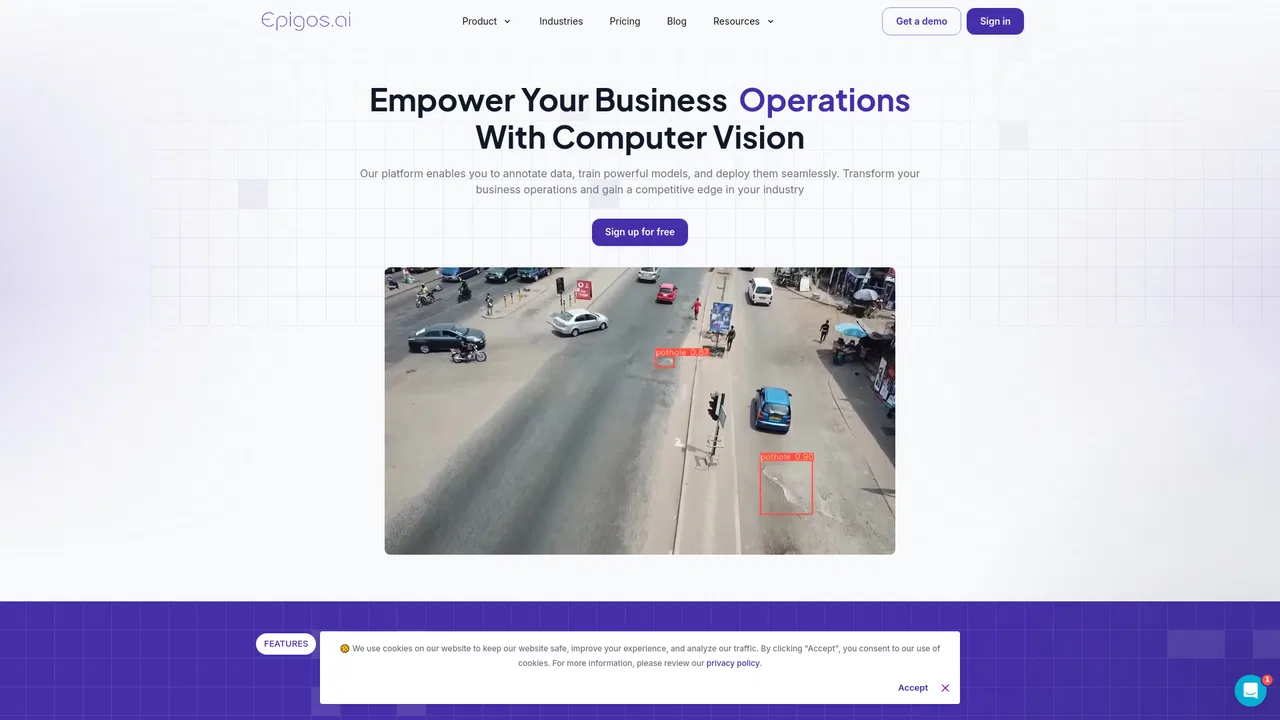
End-to-end computer vision platform for annotating, training and deploying custom models
End-to-end computer vision platform for annotating, training and deploying custom models
Performance models for fast, affordable image and video generation

Google's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
Google's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
One OpenAI-compatible API for 500+ image, video, audio, and LLM models
One OpenAI-compatible API for 500+ image, video, audio, and LLM models
Go from an idea to a live computer-vision app, agentically
Go from an idea to a live computer-vision app, agentically

Open-source generative AI for AR glasses developers and makers
Open-source generative AI for AR glasses developers and makers
Run local AI for text, images and speech on your own machine

The all-in-one computer vision platform for labeling, training and deploying vision AI
The all-in-one computer vision platform for labeling, training and deploying vision AI

Enterprise AI infrastructure where software and expert humans work together
Enterprise AI infrastructure where software and expert humans work together