01
DeepSeekOfficial
372.8M/mo
SpecialistHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
Large Language Models (LLMs)Editorial score: 4.8Freemium+4.3%
 #1
API2D records 214 monthly visits with -91.3% month-over-month growth and Paid pricing. Groq records 3,987,936 monthly visits with +10% growth and Paid pricing.
Use top AI models like electricity — register, top up, paste your key

Ultra-fast AI inference on the LPU and LPX platform
| +362.74K (+10%) |
| Primary Market & Share | 🇹🇼 Taiwan (100%) | 🇮🇳 India (19.3%) |
|---|
| Direct Visits / mo | 86 | 1.7M |
|---|
| User Rating | 3.8 | 4.7 |
|---|
| Supported Platforms | Website | Website |
|---|
Use top AI models like electricity — register, top up, paste your key
One base URL and key work with virtually any app, SDK or self-hosted chat client that supports a custom API address.
Route requests to OpenAI models, Claude, Stability diffusion, Azure TTS and vector database services from a single account.
Consumption is metered in points with a published multiplier, so you pay for what you use rather than a flat subscription.
Identical request bodies return cached answers for free for 24 hours, and a header can disable caching when freshness matters.
Ultra-fast AI inference on the LPU and LPX platform
Custom accelerators designed specifically for inference rather than training, tuned for very low latency.
Hosted access to popular open models including Llama, Mixtral, Gemma, and Whisper speech models.
An API broadly compatible with common OpenAI-style request formats for quick integration.
Automatic speech recognition with Whisper plus text-to-speech capabilities for voice applications.
SpecialistHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
#1
SpecialistProprietary frontier models with powerful reasoning and multimodal features, but lacking open-weight model hosting and custom inference speeds.
 #2

SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
 #3
Unified API gateway aggregating hundreds of models across providers, but acting as a router rather than direct hardware host.

Robust cloud platform for open-source model inference, offering extensive fine-tuning support but slightly slower raw speeds.
Free / Open-sourceOne OpenAI-compatible gateway for adaptive LLM routing, guardrails, and spend control

Wafer-scale hardware cloud delivering ultra-fast token generation speeds comparable to Groq, but supporting a more specialized model catalog.
High-throughput serverless inference for open models, featuring excellent speed and fine-tuning capabilities with broad API compatibility.

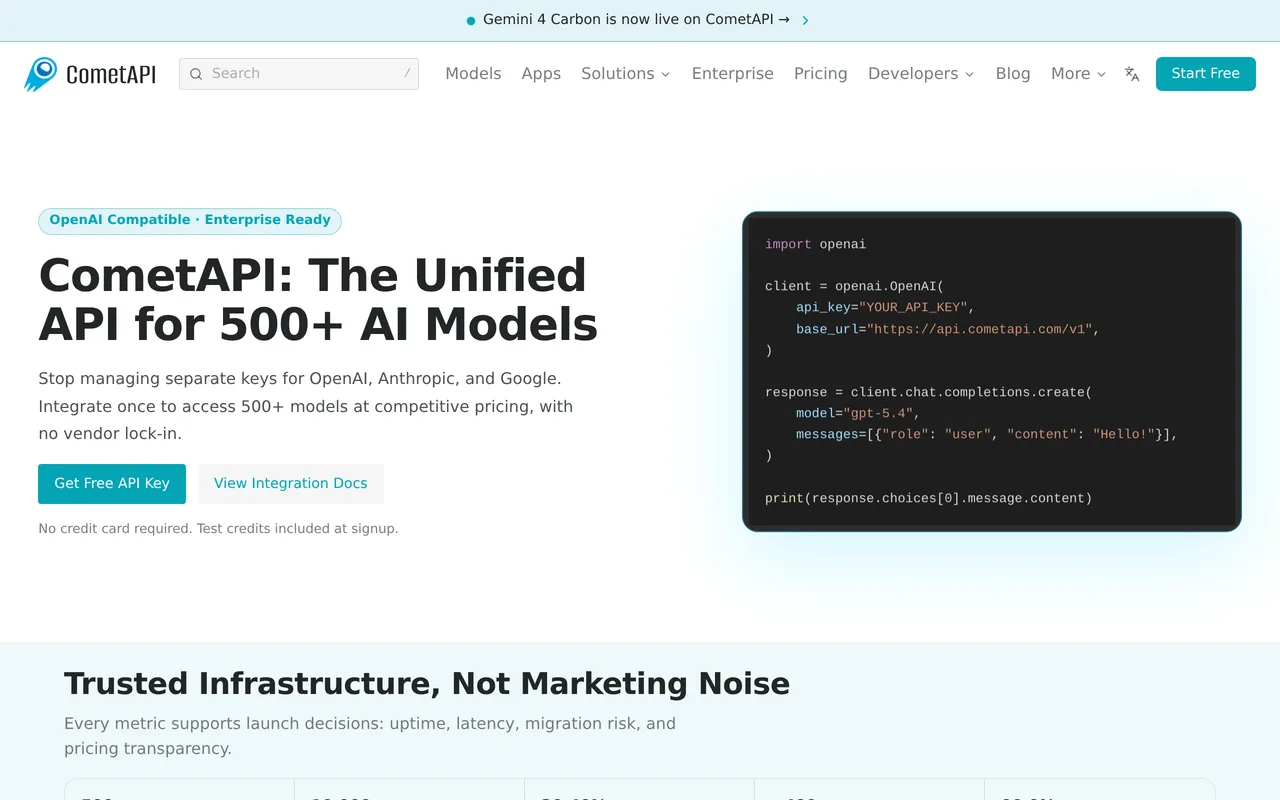
Free / Open-sourceOne OpenAI-compatible API key for 500+ AI models

Free / Open-sourceOne open-source AI gateway for 100+ LLM providers


Low-cost serverless inference cloud hosting hundreds of open-weight models, but lacking specialized custom hardware accelerators like LPUs.

Free / Open-sourceOne API for LLM, image, video, and audio models in production
SpecialistHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
SpecialistProprietary frontier models with powerful reasoning and multimodal features, but lacking open-weight model hosting and custom inference speeds.
SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
Unified API gateway aggregating hundreds of models across providers, but acting as a router rather than direct hardware host.
Robust cloud platform for open-source model inference, offering extensive fine-tuning support but slightly slower raw speeds.
Free / Open-sourceOne OpenAI-compatible gateway for adaptive LLM routing, guardrails, and spend control
Wafer-scale hardware cloud delivering ultra-fast token generation speeds comparable to Groq, but supporting a more specialized model catalog.
Free / Open-sourceOne OpenAI-compatible API key for 500+ AI models
Free / Open-sourceOne API for LLM, image, video, and audio models in production