01
Google AI StudioOfficial
112.6M/mo
SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
AI Developer ToolsEditorial score: 4.8Freemium+2%
EvoLink AI Model API records 312,573 monthly visits with -27% month-over-month growth and Free Trial, Paid, Contact for Pricing pricing. Runware records 402,862 monthly visits with +27.1% growth and Paid pricing.
One API for LLM, image, video, and audio models in production

One API for 400K+ AI models, plus serverless and reserved GPUs on modular data centers
| Dimension / Metric | | |
|---|---|---|
| Official Domain | evolink.ai | runware.ai |
| Pricing Model | Free Trial, Paid, Contact for Pricing | Paid |
| Monthly Visits | 312.57K (312,573) | 402.86K (402,862) |
| MoM Traffic Delta |
|---|
| -115.33K (-27%) |
| +85.78K (+27.1%) |
| Primary Market & Share | 🇨🇳 China (10.9%) | 🇺🇸 United States (27.3%) |
|---|
| Direct Visits / mo | 112.42K | 189.8K |
|---|
| User Rating | 4.3 | 4.5 |
|---|
| Supported Platforms | Website | Website |
|---|
One API for LLM, image, video, and audio models in production
Access hundreds of models across text, image, video, and audio through one API key and one base URL.
Routes each request to the fastest, cheapest, or most reliable provider and automatically retries elsewhere during outages.
Works with OpenAI, Anthropic, and Google SDK formats so most existing code runs after changing the base URL and key.
See cost per token, image, or video second before calling so you can compare models on real numbers.
One API for 400K+ AI models, plus serverless and reserved GPUs on modular data centers
Image, video, audio, LLM and 3D tasks all POST to a single endpoint as an array, so mixed-modality batches can travel in one request with shared auth and billing.
Browse hosted, partner and community models through one addressing scheme, control parameters such as stacked LoRAs and swapped VAEs on open models, and add your own uploads.
Bring your own container and weights to serverless GPUs billed by the second that scale to zero when idle, or commit to reserved capacity and bare-metal clusters for a lower per-hour rate.
Purpose-built modular data centers plus an orchestration layer that keeps weights preloaded across regions and routes requests to pods that already hold the model in memory.
SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
SpecialistOne API key for hundreds of AI models from every major provider
SpecialistCloud ComfyUI platform to run workflows and build AI apps
 #3

Offers a similar developer-first cloud for ultra-fast generative media inference, but with distinct pricing tiers.

SpecialistStronger focus on open-source LLM hosting and dedicated clusters, but less tailored for instant image generation.

Provides comparable serverless model deployment and fine-tuning, but features a broader general-purpose ML ecosystem.
Delivers unified access to generative media models, but lacks Runware's specialized focus on raw inference speed.

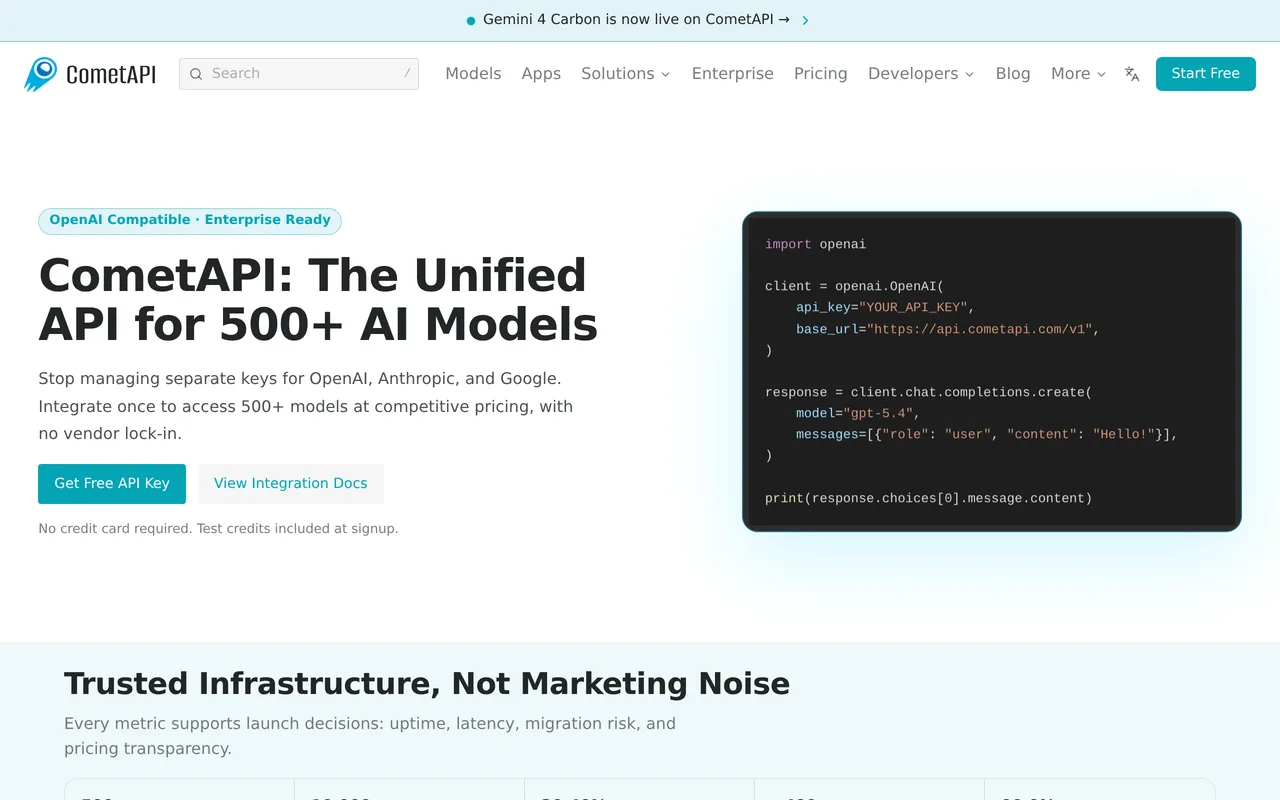
Provides access to 500+ models via OpenAI-compatible endpoints, but lacks advanced multi-provider failover controls.

Excels at low-cost open-weight model inference, but offers less specialized tooling for complex image generation pipelines.
Consolidates generative media models effectively under single endpoints, but lacks the extensive text model variety of OpenRouter.
Diverse support for 3D, voice, and video models through a unified API, though documentation can be sparse.
Focuses heavily on image generation and Stable Diffusion APIs, but offers slightly different serverless GPU pricing.

SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
Offers a similar developer-first cloud for ultra-fast generative media inference, but with distinct pricing tiers.
SpecialistStronger focus on open-source LLM hosting and dedicated clusters, but less tailored for instant image generation.
Provides comparable serverless model deployment and fine-tuning, but features a broader general-purpose ML ecosystem.
Delivers unified access to generative media models, but lacks Runware's specialized focus on raw inference speed.
Provides access to 500+ models via OpenAI-compatible endpoints, but lacks advanced multi-provider failover controls.