01
DeepSeekOfficial
372.8M/mo
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
Large Language Models (LLMs)Editorial score: 4.8Freemium+4.3%
 #1
Flaq AI records 328,715 monthly visits with +127.9% month-over-month growth and Paid pricing. Runware records 402,862 monthly visits with +27.1% growth and Paid pricing.
One API key for the world's leading image, video and language models

One API for 400K+ AI models, plus serverless and reserved GPUs on modular data centers
| Dimension / Metric | | |
|---|---|---|
| Official Domain | flaq.ai | runware.ai |
| Pricing Model | Paid | Paid |
| Monthly Visits | 328.72K (328,715) | 402.86K (402,862) |
| MoM Traffic Delta |
| +184.48K (+127.9%) |
| +85.78K (+27.1%) |
| Primary Market & Share | 🇺🇸 United States (38.5%) | 🇺🇸 United States (27.3%) |
|---|
| Direct Visits / mo | 134.26K | 189.8K |
|---|
| User Rating | 4.1 | 4.5 |
|---|
| Supported Platforms | Website | Website |
|---|
One API key for the world's leading image, video and language models
Image, video, 3D, voice and LLM models sit behind a single API key and a single billing balance, so you integrate once and swap models by changing a model name.
A model market lists entry prices, unit types and active discounts across providers, making cost comparison between models straightforward.
A web playground for image, video and editing workflows lets you write a prompt, pick resolution or aspect ratio and see output before you write any integration code.
Documentation ships copy-and-paste JavaScript, Python and cURL recipes that show how to submit a task and poll until the result succeeds or fails.
One API for 400K+ AI models, plus serverless and reserved GPUs on modular data centers
Image, video, audio, LLM and 3D tasks all POST to a single endpoint as an array, so mixed-modality batches can travel in one request with shared auth and billing.
Browse hosted, partner and community models through one addressing scheme, control parameters such as stacked LoRAs and swapped VAEs on open models, and add your own uploads.
Bring your own container and weights to serverless GPUs billed by the second that scale to zero when idle, or commit to reserved capacity and bare-metal clusters for a lower per-hour rate.
Purpose-built modular data centers plus an orchestration layer that keeps weights preloaded across regions and routes requests to pods that already hold the model in memory.
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
#1
SpecialistEnterprise developer platform and API for deploying GPT-6 Astra, Sol, Luna, and realtime multimodal agents.
 #2

SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
 #3
SpecialistOne API key for hundreds of AI models from every major provider
SpecialistCloud ComfyUI platform to run workflows and build AI apps

Offers a similar developer-first cloud for ultra-fast generative media inference, but with distinct pricing tiers.
One API key for video, image, music, and chat models
SpecialistMultimodal creative AI agents for video, image and 3D generation

SpecialistStronger focus on open-source LLM hosting and dedicated clusters, but less tailored for instant image generation.

Provides comparable serverless model deployment and fine-tuning, but features a broader general-purpose ML ecosystem.
Delivers unified access to generative media models, but lacks Runware's specialized focus on raw inference speed.

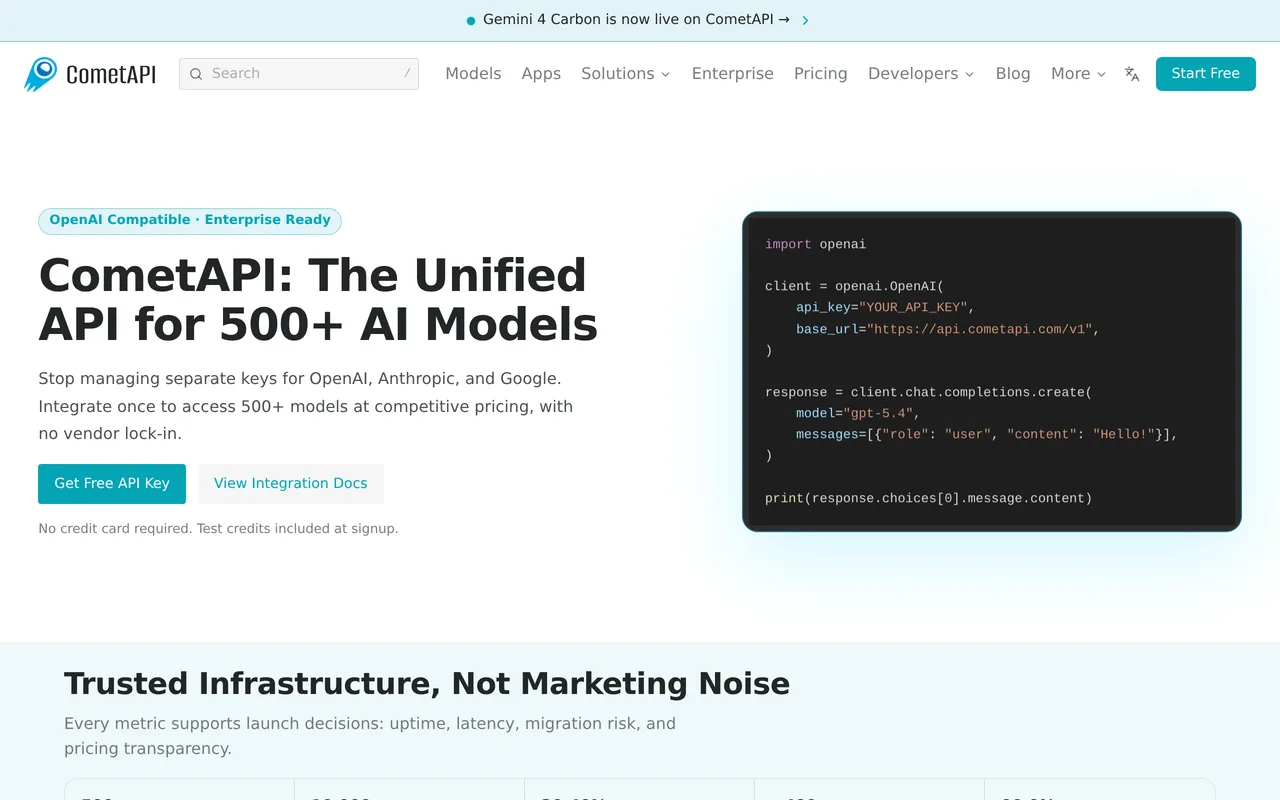
One OpenAI-compatible API key for 500+ AI models
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
SpecialistEnterprise developer platform and API for deploying GPT-6 Astra, Sol, Luna, and realtime multimodal agents.
SpecialistGoogle's rapid prototyping IDE and developer API workbench for building multimodal applications with Gemini models.
Offers a similar developer-first cloud for ultra-fast generative media inference, but with distinct pricing tiers.
SpecialistStronger focus on open-source LLM hosting and dedicated clusters, but less tailored for instant image generation.
Provides comparable serverless model deployment and fine-tuning, but features a broader general-purpose ML ecosystem.
Delivers unified access to generative media models, but lacks Runware's specialized focus on raw inference speed.
One OpenAI-compatible API key for 500+ AI models