33.227/Monat
Ein multimodales Data Warehouse, das Video, Audio und Dokumente in abfragbare Zeilen verwandelt
AI APIRedaktionswert: 4.4Freemium, Preise auf Anfrage34% direkt
Vergleiche KI-Produkte für 459 Workflows anhand von Traffic-Schätzungen, Funktionen und Alternativen.
“Vector Database” · Bildanalyse·11 Ergebnisse
Neu startenEin multimodales Data Warehouse, das Video, Audio und Dokumente in abfragbare Zeilen verwandelt

Eine Suchbasis aus Embeddings, Rerankern und Reader-APIs

Voxel51 is the data platform for physical AI, built on the open-source FiftyOne library. It helps computer vision and robotics teams search, visualize, curate, annotate, and evaluate multimodal datasets — images, video, 3D scenes, and sensor streams — so they can find where models fail and fix the data behind them.
Voxel51 is the data platform for physical AI, built on the open-source FiftyOne library. It helps computer vision and robotics teams search, visualize, curate, annotate, and evaluate multimodal datasets — images, video, 3D scenes, and sensor streams — so they can find where models fail and fix the data behind them.
PDFs, Screenshots und Videos als bearbeitbare PowerPoint-Folien neu aufbauen
PDFs, Screenshots und Videos als bearbeitbare PowerPoint-Folien neu aufbauen

LocalMode UI is an open-source shadcn registry of copy-owned, composable AI interface components plus installable blocks that run real models directly in the browser. It ships 100+ React components and 36 blocks covering chat, RAG knowledge bases, vision, audio, photo editing, agents and privacy tooling, all designed to be local-first by default and cloud-compatible when you want it.
LocalMode UI is an open-source shadcn registry of copy-owned, composable AI interface components plus installable blocks that run real models directly in the browser. It ships 100+ React components and 36 blocks covering chat, RAG knowledge bases, vision, audio, photo editing, agents and privacy tooling, all designed to be local-first by default and cloud-compatible when you want it.
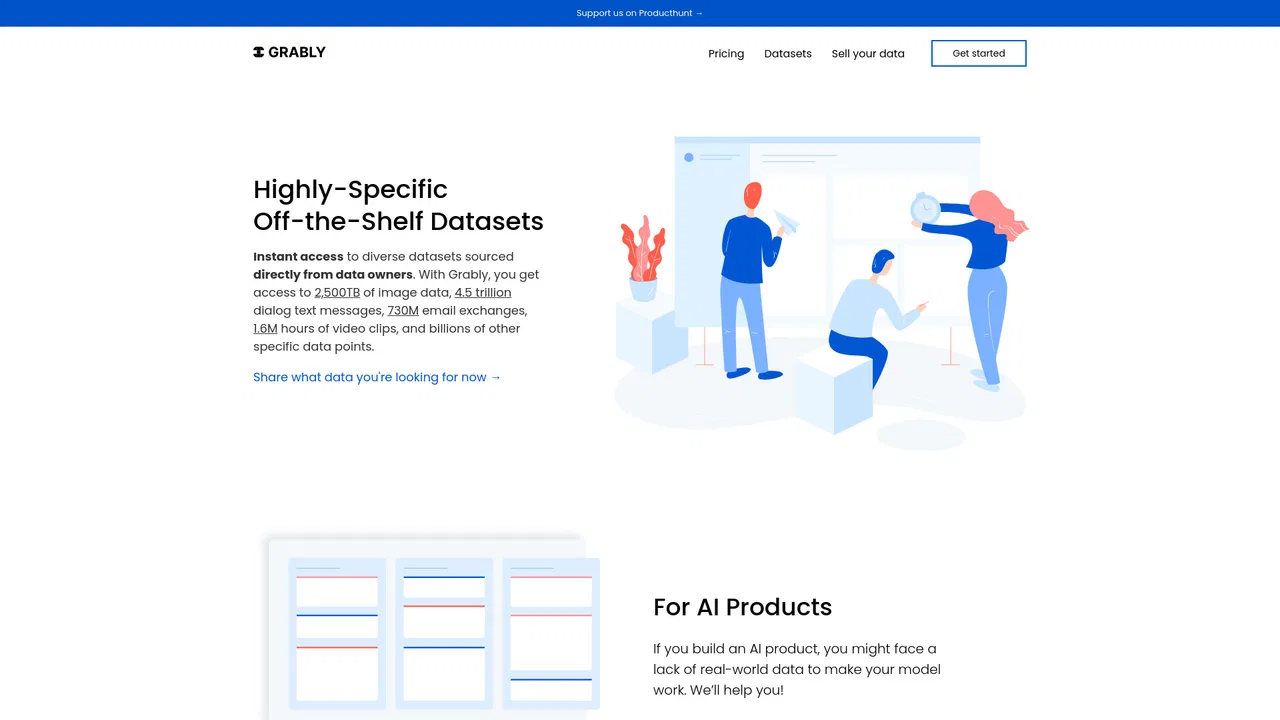
Multimodale Mensch-Interaktionsdatensätze für das KI-Modelltraining
Multimodale Mensch-Interaktionsdatensätze für das KI-Modelltraining
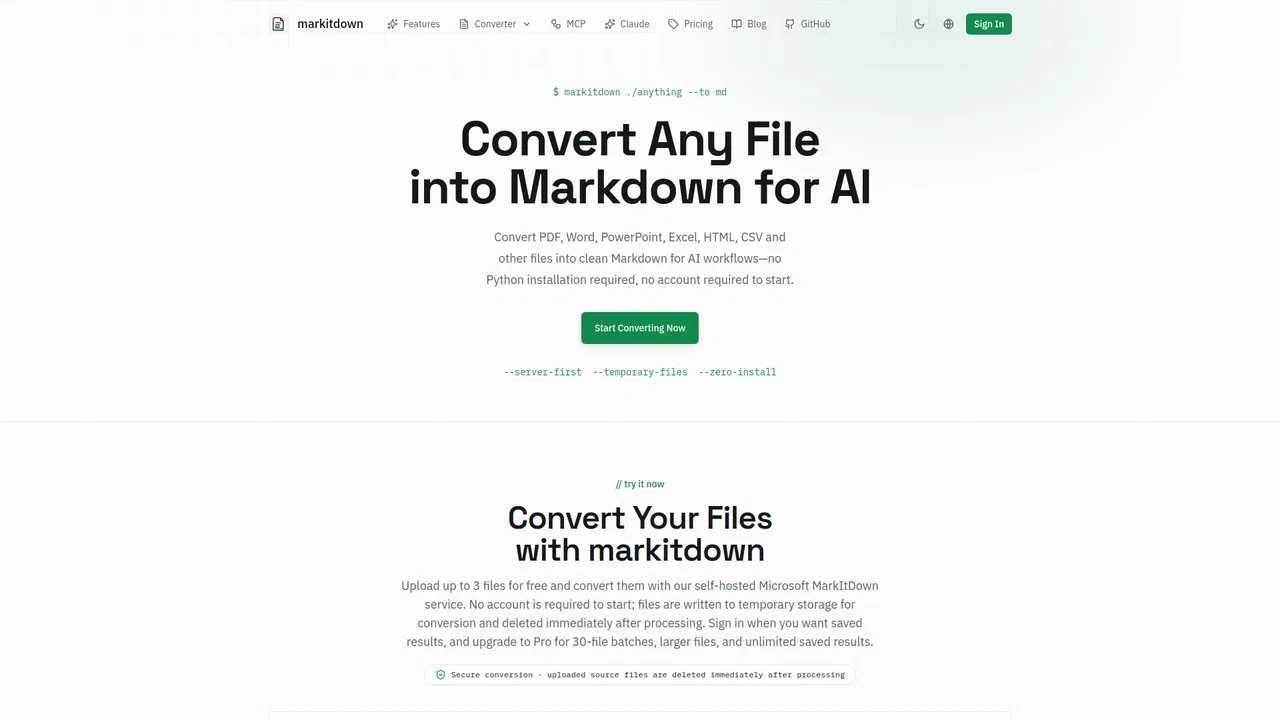
PDFs, Office-Dateien und Bilder in sauberes Markdown für KI-Workflows umwandeln
PDFs, Office-Dateien und Bilder in sauberes Markdown für KI-Workflows umwandeln
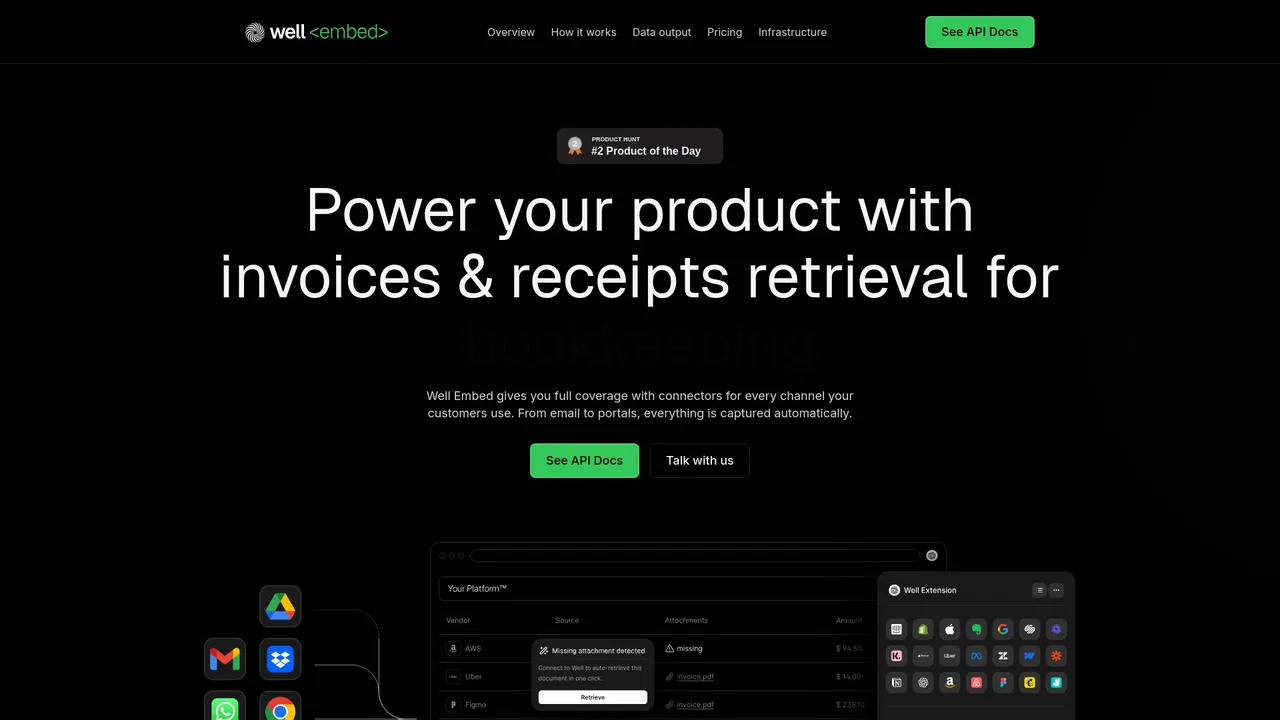
KI-native Infrastruktur, die Rechnungen und Belege in MCP-fähige Finanzdaten verwandelt
KI-native Infrastruktur, die Rechnungen und Belege in MCP-fähige Finanzdaten verwandelt

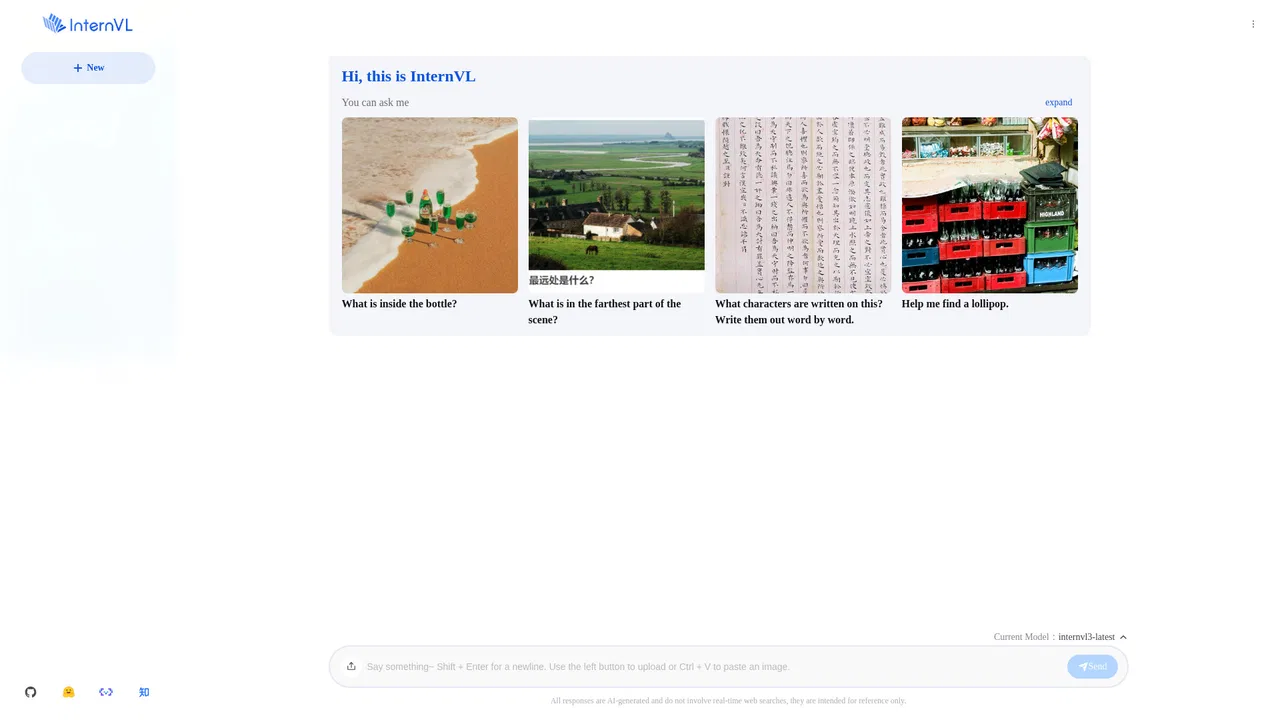
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.

Vom gescannten Schnittmuster zur schneidfertigen, farbgruppierten SVG
Vom gescannten Schnittmuster zur schneidfertigen, farbgruppierten SVG

Persistentes Gedächtnis und fundiertes Wissen für KI-Agenten als native MCP-Tools
Persistentes Gedächtnis und fundiertes Wissen für KI-Agenten als native MCP-Tools