01
4712.8万/月
ダイナミックなカメラワークとシネマティックなキャラクターアニメーションに最適化されていますが、ユーザーインターフェースのワークフローが異なります。
AI Video Generator編集部スコア:4.4フリーミアム、無料トライアル+16.2%

4712.8万/月+16.2%
ダイナミックなカメラワークとシネマティックなキャラクターアニメーションに最適化されていますが、ユーザーインターフェースのワークフローが異なります。
フリーミアム、無料トライアル
Layerpath は月間 42,635 訪問、前月比成長率 -8.9%、料金体系フリーミアムを記録しています。Vidu は月間 4,009,012 訪問、成長率 +18.7%、料金体系フリーミアム、有料を記録しています。
スクリーンショットや録画からクリックできる製品ツアー・ガイド・動画を作成
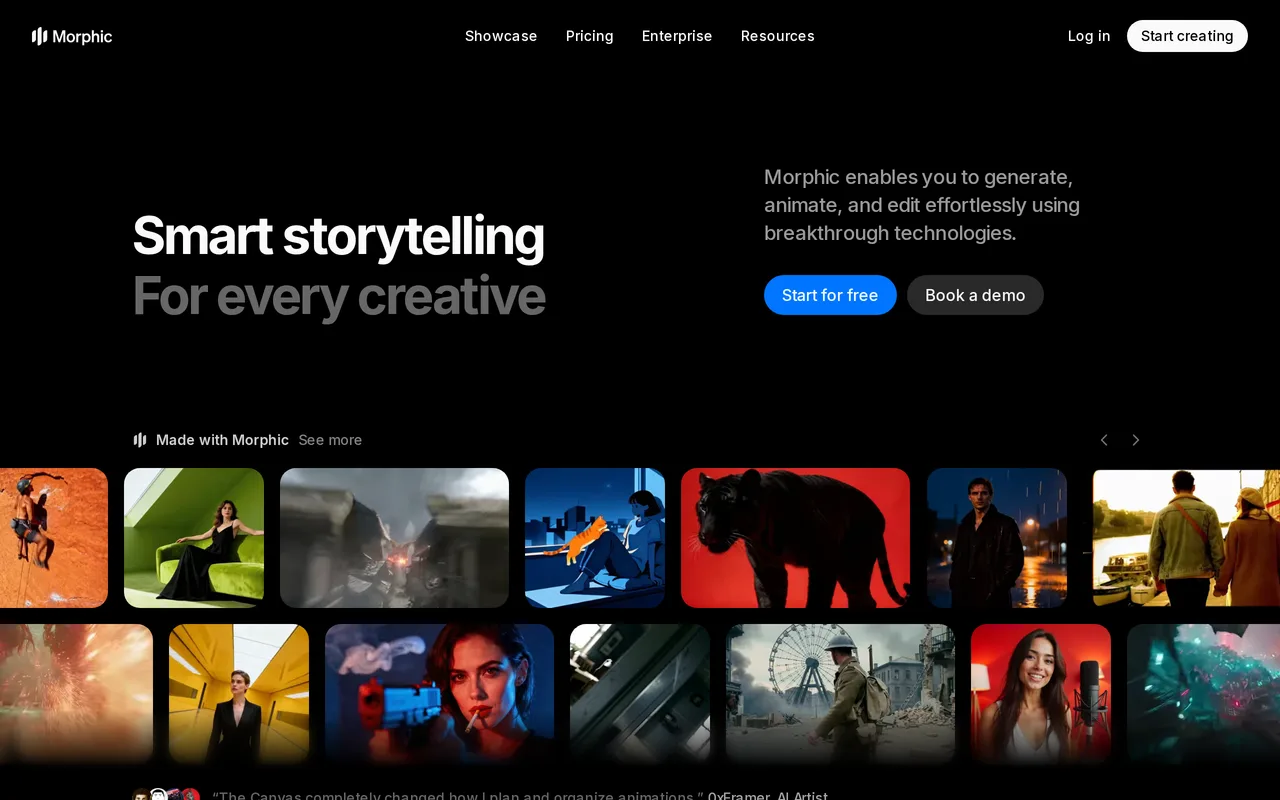
Vidu is a multimodal generative video platform from ShengShu Technology. It turns text prompts, still images, and reference footage into short cinematic clips, with tools for subject-consistent characters, anime styles, and sound-effect generation.
| 項目 / 指標 | | |
|---|---|---|
| 公式ドメイン | layerpath.com | vidu.com |
| 料金モデル | フリーミアム | フリーミアム、有料 |
| 月間訪問数 | 4.26万 (42,635) | 400.9万 (4,009,012) |
| 前月比トラフィック増減 | -4160 (-8.9%) | +63.27万 (+18.7%) |
| 主要市場とシェア | 🇺🇸 アメリカ合衆国 (20.5%) | 🇺🇸 アメリカ合衆国 (17.5%) |
| 月間ダイレクト訪問数 | 1.74万 | 188.31万 |
| ユーザー評価 | 4.5 | 4.5 |
| 対応プラットフォーム | ウェブサイト | ウェブサイト |
スクリーンショットや録画からクリックできる製品ツアー・ガイド・動画を作成
Slack、ChatGPT、Claude のいずれか、または任意の MCP アシスタントから依頼し、あとから質問形式で各ステップを変更できます。
スクリーンショット、既存の画面録画、Loom リンクから始めると、Agent がステップと注釈を書き出します。
同じワークフローをインタラクティブツアー、ステップガイド、ナレーション付き動画として公開できます。
ステップの書き換え、注釈の調整、ノイズ除去、34 言語・100 以上の音声での多言語ナレーション生成。
Vidu is a multimodal generative video platform from ShengShu Technology. It turns text prompts, still images, and reference footage into short cinematic clips, with tools for subject-consistent characters, anime styles, and sound-effect generation.
Type a written prompt and Vidu builds a coherent short video, including camera moves, pacing, and lighting described in the text.
Upload a still image or illustration and animate it into motion while preserving the original art style and subjects.
Feed in reference images or clips so the same face, outfit, product, or character stays recognizable across every shot and scene.
Purpose-built handling of anime and 2D styles, from expressive facial close-ups to era-specific illustration looks.
ダイナミックなカメラワークとシネマティックなキャラクターアニメーションに最適化されていますが、ユーザーインターフェースのワークフローが異なります。
ダイナミックなカメラワークとシネマティックなキャラクターアニメーションに最適化されていますが、ユーザーインターフェースのワークフローが異なります。
特化型Provides industry-leading voice synthesis and sound effects to add professional audio to generated videos.
特化型Provides industry-leading voice synthesis and sound effects to add professional audio to generated videos.

高度なモーションコントロールを備えた業界標準のシネマティック動画生成ですが、ネイティブなアニメ風スタイルの重視度はやや低めです。
特化型Combines generative AI video clips with traditional multi-track timeline editing for marketing workflows.
特化型Combines generative AI video clips with traditional multi-track timeline editing for marketing workflows.
特化型複数の主要なAI動画モデルを1つのダッシュボードに集約し、単一プラットフォームのツールよりも幅広いモデルの選択肢を提供します。
特化型複数の主要なAI動画モデルを1つのダッシュボードに集約し、単一プラットフォームのツールよりも幅広いモデルの選択肢を提供します。
特化型Specializes in video generation with precise lip sync and multilingual narration, but less general cinematic focus.
特化型Specializes in video generation with precise lip sync and multilingual narration, but less general cinematic focus.
テキストと画像からダイナミックなシネマティック動画クリップを生成しますが、Vidu特有の複数参照キャラクターの一貫性は備えていません。
生成された動画における優れた視覚的リアリズムと物理シミュレーションを備えていますが、レンダリングの待ち時間が長くなる場合があります。

特化型Excels at video-to-animation restyling and face swapping, whereas Vidu focuses primarily on text and image generation.

Transforms text and reference images into cinematic video clips with intuitive creative controls.
Transforms text and reference images into cinematic video clips with intuitive creative controls.

MiniMaxの基盤モデルを搭載し、テキストと参照画像から非常に表現力豊かなシネマティックな動きを実現します。

Builds multi-scene narrative videos with consistent characters, matching Vidu's storytelling use case closely.
Builds multi-scene narrative videos with consistent characters, matching Vidu's storytelling use case closely.