読み込み中…
掲載製品 20,346 件·アクセス動向とツール探索
迷わず選べる。 次のプロジェクトに合う AI ツールを見つける。
459 種類のワークフローで、アクセス推計・機能・代替製品を比較できます。
459 種類のワークフローで、アクセス推計・機能・代替製品を比較できます。
“Java Code Explainer” · 画像認識・解析·27 件
最初から

リアルタイム画像・動画 API、エージェント型 DAM、クリエイティブ自動化を 1 つに


すべてのページでUIバグを検出するAIビジュアル・ファンクショナルテスト


あらゆる画像を詳細な説明・altテキスト・プロンプト・コードに変換
メール・PDF・各種ドキュメントを構造化JSONに変換するLLMベースのパーサー
メール・PDF・各種ドキュメントを構造化JSONに変換するLLMベースのパーサー
.NET アプリ内にプライベートな生成 AI・RAG・エージェントを直接組み込む

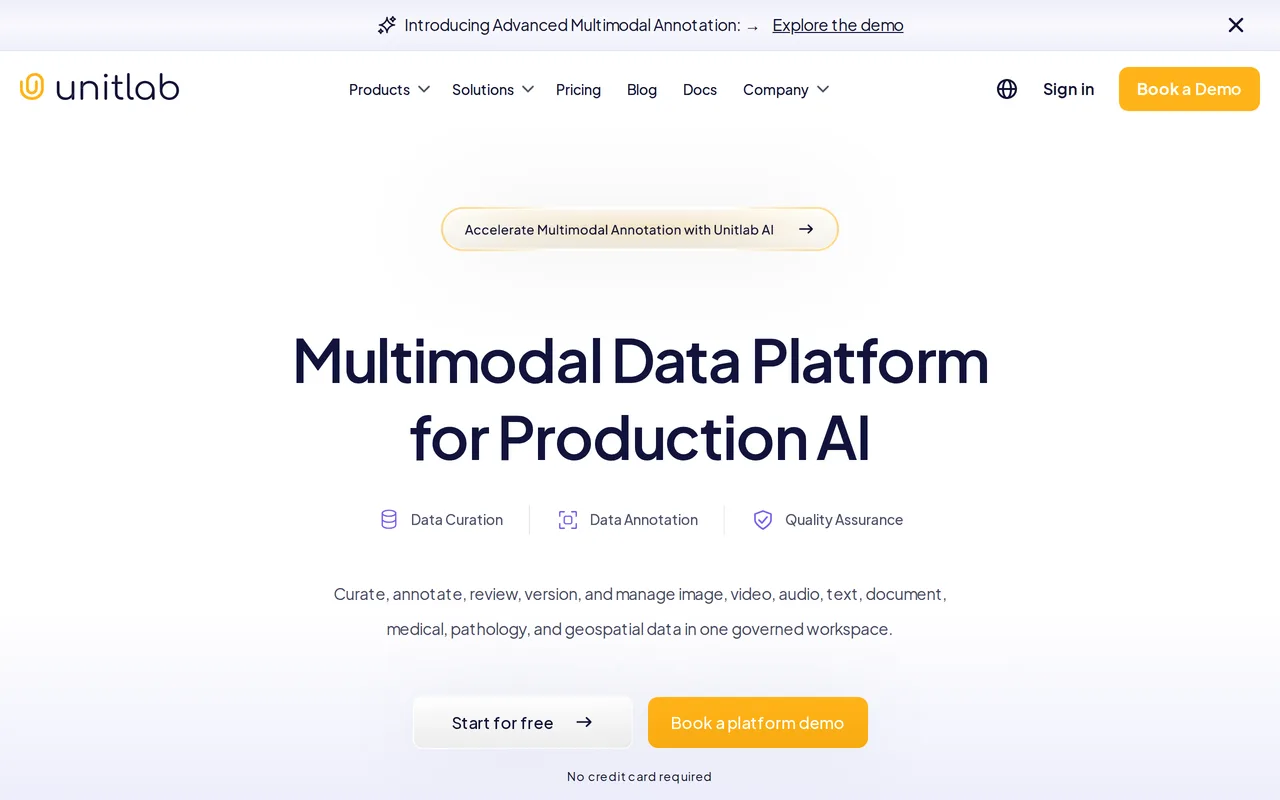
ガバナンスされた 1 つのワークスペースでマルチモーダルな学習データをキュレーション・アノテーション・品質管理
開発者向けのクラウド顔認識・ライブネス検出・属性分析API

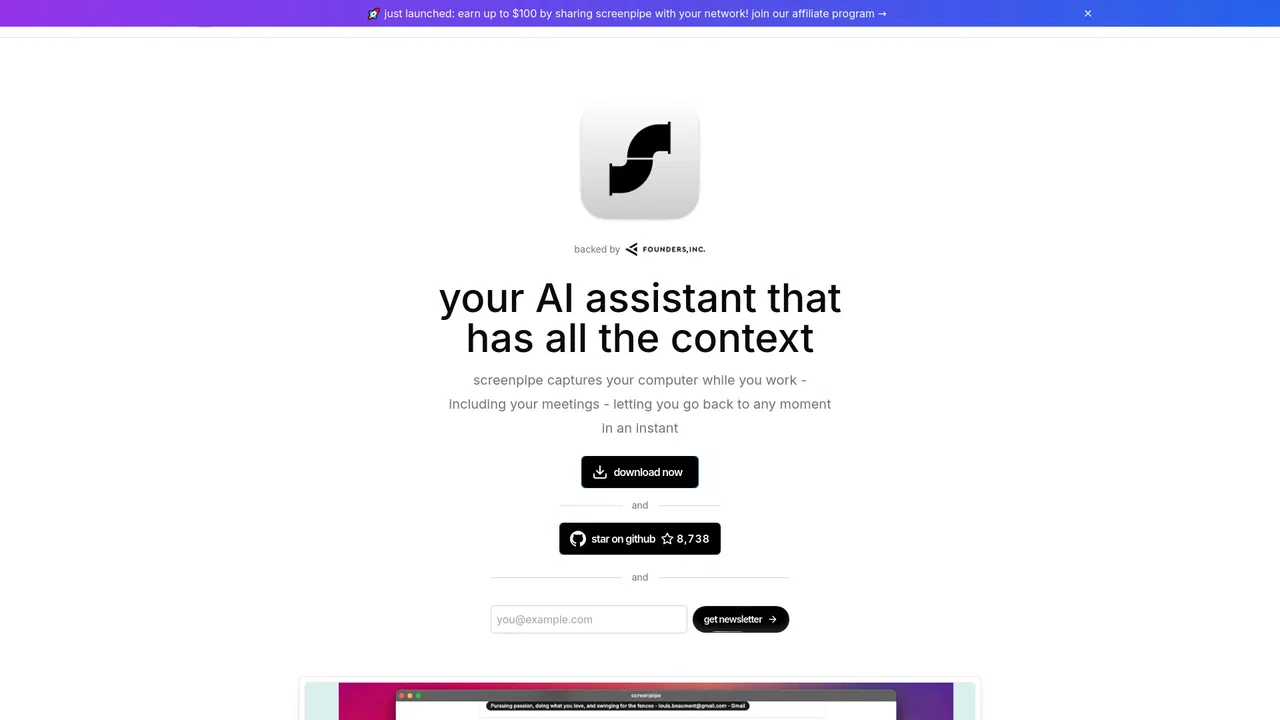
Screenpipe captures your screen and audio locally to build a searchable memory of your work, then exposes it to AI agents through a local API and MCP server. Ask what you were doing, recover that thing you saw earlier, or turn repeated work into documented workflows.
Screenpipe captures your screen and audio locally to build a searchable memory of your work, then exposes it to AI agents through a local API and MCP server. Ask what you were doing, recover that thing you saw earlier, or turn repeated work into documented workflows.

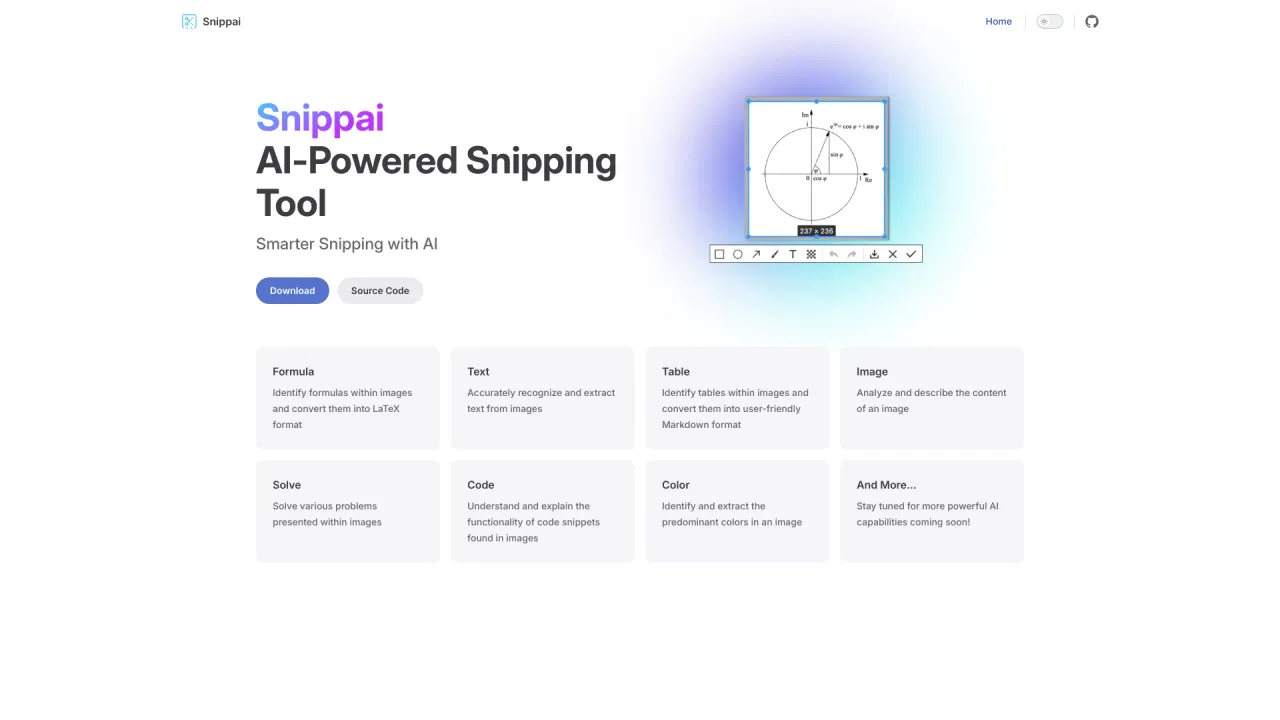
Snippai is an AI-enhanced screenshot and snipping tool that analyzes whatever you capture. Instead of just cropping an image, it can recognize text, convert formulas to LaTeX, turn tables into Markdown, explain code, describe images and pull out dominant colors.
Snippai is an AI-enhanced screenshot and snipping tool that analyzes whatever you capture. Instead of just cropping an image, it can recognize text, convert formulas to LaTeX, turn tables into Markdown, explain code, describe images and pull out dominant colors.
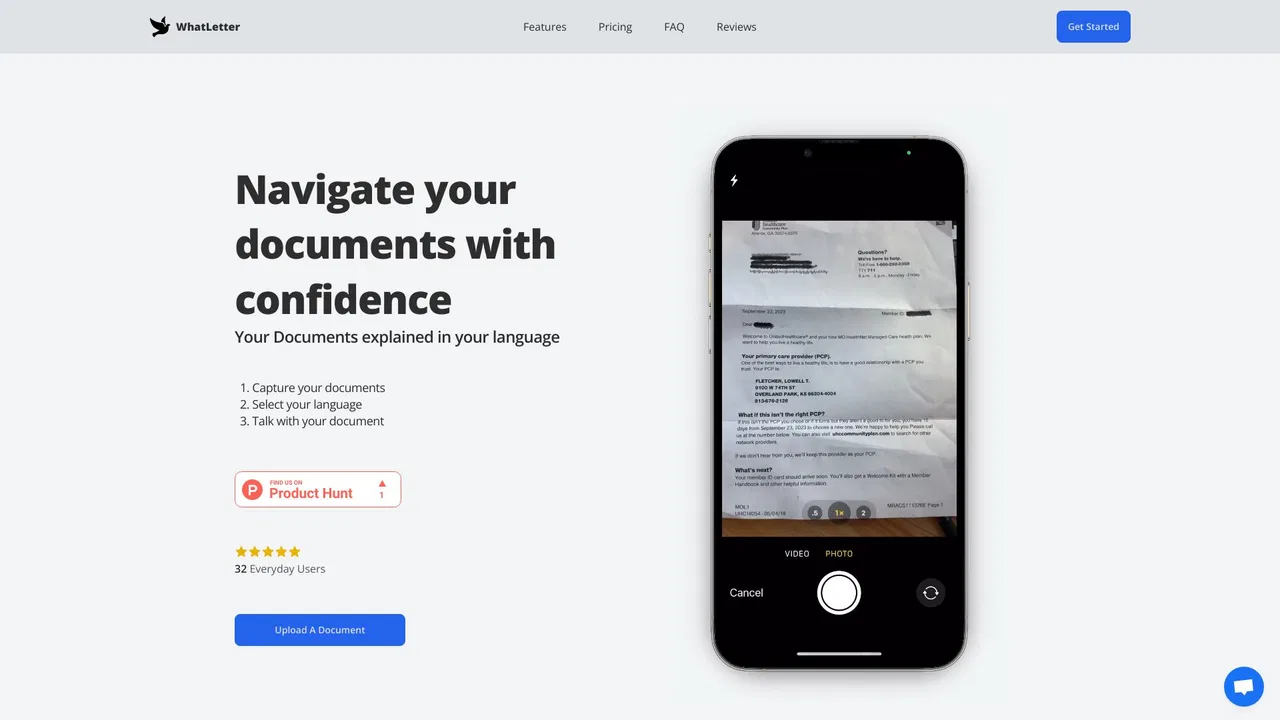
WhatLetter is an AI document assistant that lets you photograph a paper, translate it into your own language, and then chat about it in plain words until the details make sense. It was built for immigrant families and older readers who have to deal with medical records, bills, legal forms and official letters they cannot easily read.
WhatLetter is an AI document assistant that lets you photograph a paper, translate it into your own language, and then chat about it in plain words until the details make sense. It was built for immigrant families and older readers who have to deal with medical records, bills, legal forms and official letters they cannot easily read.
customvision.ai is the home of Microsoft's Custom Vision, a computer vision service that lets you train your own image classification and object detection models by uploading and labeling a handful of examples. You build the model in a browser-based interface, evaluate its accuracy with live metrics, and then consume it from your own applications through REST APIs or exported models.
customvision.ai is the home of Microsoft's Custom Vision, a computer vision service that lets you train your own image classification and object detection models by uploading and labeling a handful of examples. You build the model in a browser-based interface, evaluate its accuracy with live metrics, and then consume it from your own applications through REST APIs or exported models.

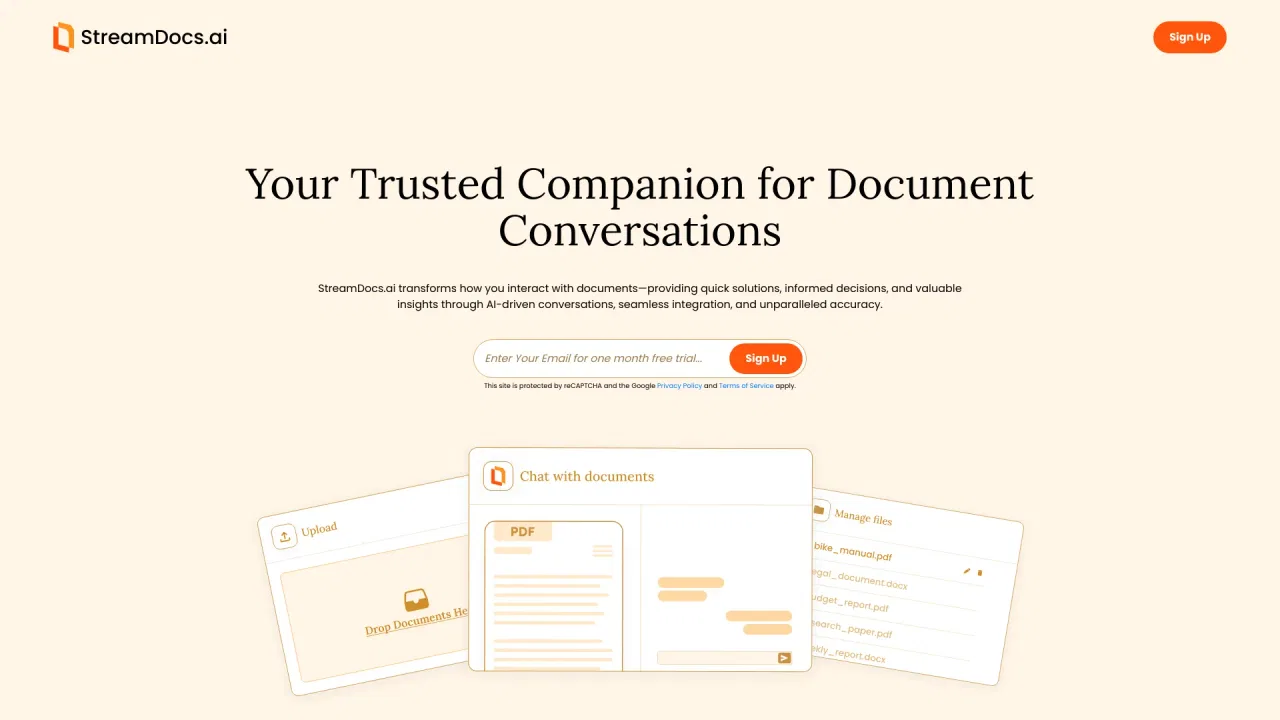
StreamDocs.ai now resolves to PDF.co, a low-code REST API from Artifex Software that automates PDF extraction, conversion, editing, generation and AI-powered invoice parsing across 3,000+ integrations.
StreamDocs.ai now resolves to PDF.co, a low-code REST API from Artifex Software that automates PDF extraction, conversion, editing, generation and AI-powered invoice parsing across 3,000+ integrations.

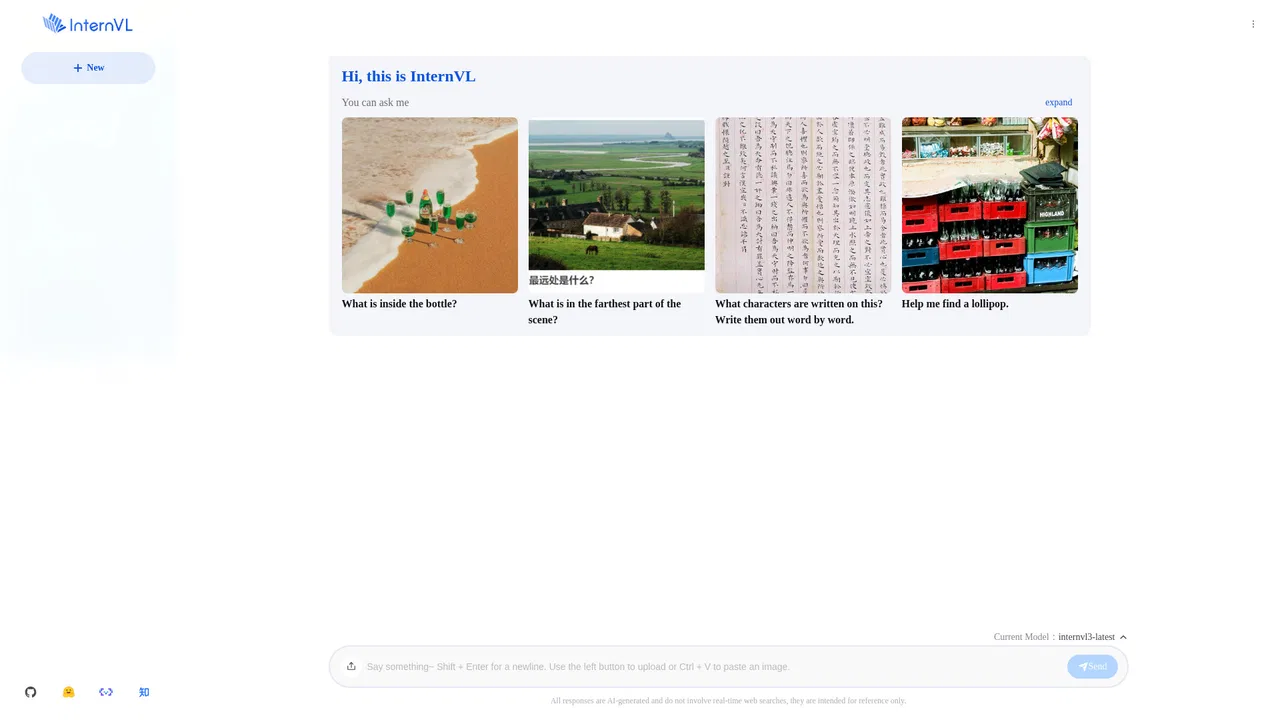
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.