로딩 중…
일대일 벤치마크
MyScale vs Shaped
MyScale는 월간 방문 19,350, 전월 대비 성장률 +21.3%, 가격 문의, 무료 가격 모델을 기록합니다. Shaped는 월간 방문 11,871, 성장률 -39.2%, 가격 문의 가격 모델을 기록합니다.
프로덕션 GenAI 애플리케이션을 위한 SQL 네이티브 벡터 데이터베이스
월간 방문 수
1.94만
전월 대비 상승 속도
+21.3%
최대 시장
🇺🇸 미국
MyScale는 월간 방문 19,350, 전월 대비 성장률 +21.3%, 가격 문의, 무료 가격 모델을 기록합니다. Shaped는 월간 방문 11,871, 성장률 -39.2%, 가격 문의 가격 모델을 기록합니다.
프로덕션 GenAI 애플리케이션을 위한 SQL 네이티브 벡터 데이터베이스
| 항목 / 지표 |  | |
|---|---|---|
| 공식 도메인 | myscale.com | shaped.ai |
| 가격 모델 | 가격 문의, 무료 | 가격 문의 |
| 월간 방문 수 | 1.94만 (19,350) | 1.19만 (11,871) |
| 전월 대비 트래픽 변화량 | +3.4천 (+21.3%) | -7.65천 (-39.2%) |
| 주요 시장 및 점유율 | 🇺🇸 미국 (33.2%) | 🇺🇸 미국 (36.4%) |
| 월 직접 방문 수 | 7.73천 | 4.73천 |
| 사용자 평점 | 4.6 | 4.8 |
| 지원 플랫폼 | 웹사이트 | 웹사이트 |
프로덕션 GenAI 애플리케이션을 위한 SQL 네이티브 벡터 데이터베이스
일반 SQL 문법으로 벡터 검색, 텍스트 검색, 필터 검색, 복잡한 SQL-벡터 조인 쿼리를 실행하며 인덱스는 ALTER TABLE 문 하나로 생성합니다.
전용 인덱스 엔진으로, 전용 벡터 데이터베이스 대비 약 3배 속도와 비용 절감을 표방하며 데이터 수집과 인덱스 구축도 최적화했습니다.
벡터 유사도를 BM25 전문 검색, 메타데이터 필터와 결합해 RAG 파이프라인의 검색 품질과 그라운딩을 높입니다.
인기 언어, 프레임워크, LLM 도구와의 통합을 갖춘 완전 관리형 제품이며 AI 앱을 위한 관측성도 포함합니다.
피드백 루프를 갖춘 관련성 엔진
SQL과 유사한 단일 쿼리로 시맨틱 검색, 키워드 검색, 행동 모델 전반의 검색·필터·스코어링·재정렬을 실행합니다.
시맨틱 검색과 키워드 검색을 결합하고 각 사용자의 예상 클릭률과 참여도로 결과를 재정렬합니다.
ML 모델이 실시간 상호작용 신호로 재학습하여 트래픽이 늘수록 랭킹 품질이 자동으로 향상됩니다.
Snowflake, Kafka, BigQuery, Shopify 등 데이터 웨어하우스, 분석 도구, 이벤트 파이프라인에서 ETL 없이 데이터를 수집합니다.
Scale is an enterprise AI company that supplies the data, evaluation and deployment layers behind production AI. Its Data Engine sources and labels training data for frontier models, its evaluation work benchmarks model capability, and its platform teams help enterprises and governments move AI systems from pilot into real operations.
Scale is an enterprise AI company that supplies the data, evaluation and deployment layers behind production AI. Its Data Engine sources and labels training data for frontier models, its evaluation work benchmarks model capability, and its platform teams help enterprises and governments move AI systems from pilot into real operations.
특화 강점Pinecone is a managed vector database and AI knowledge platform for building retrieval-augmented generation (RAG), semantic search, and agent memory. It stores vector embeddings at scale, makes writes searchable within seconds with no index tuning, and keeps p99 latency steady as data grows. Pinecone powers products for more than 10,000 customers and over a million developers worldwide.
특화 강점Pinecone is a managed vector database and AI knowledge platform for building retrieval-augmented generation (RAG), semantic search, and agent memory. It stores vector embeddings at scale, makes writes searchable within seconds with no index tuning, and keeps p99 latency steady as data grows. Pinecone powers products for more than 10,000 customers and over a million developers worldwide.

Zilliz is the company behind Milvus, the open-source vector database, and offers Zilliz Cloud — a fully managed vector database service built for large-scale AI retrieval, RAG, and similarity search workloads.
무료 / 오픈소스Qdrant is an open-source vector search engine and database, written in Rust, for high-performance similarity search in AI applications.

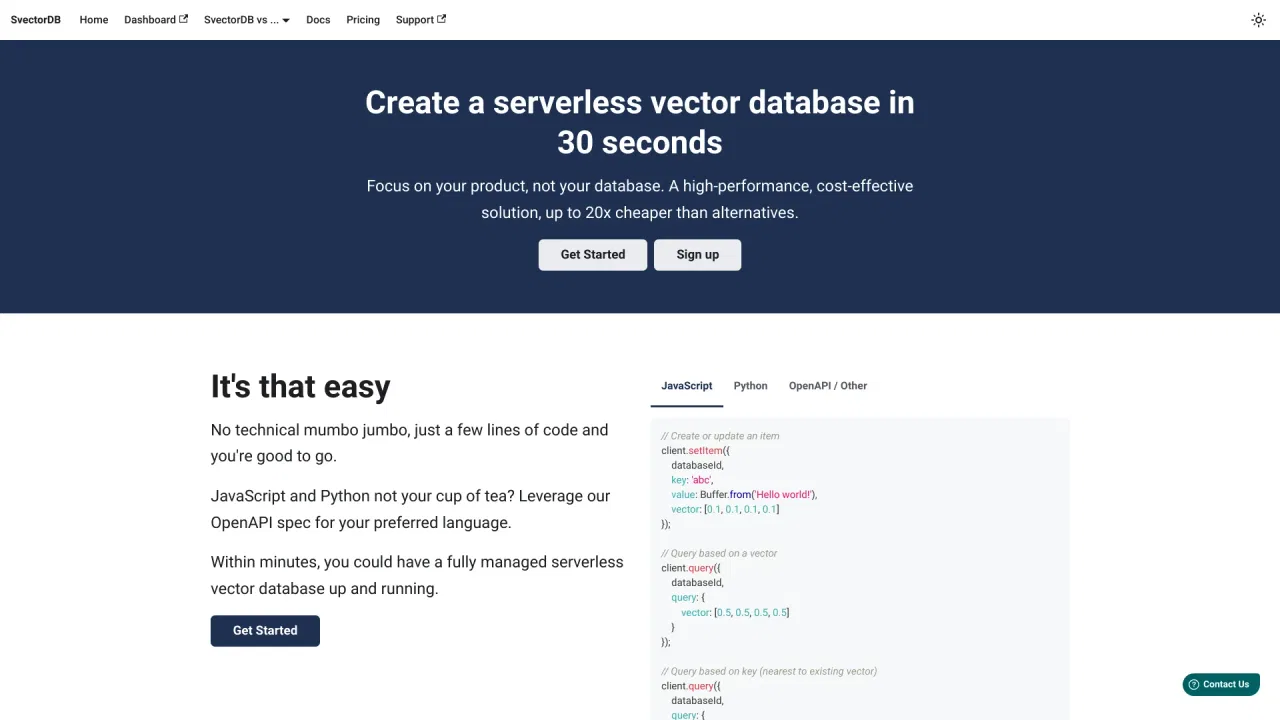
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.