로딩 중…
등록된 제품 20,346개·트래픽 동향과 도구 탐색
헤매지 말고, 다음 프로젝트에 맞는 AI 도구를 찾으세요.
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Python Implementation” · 코딩 및 소프트웨어 개발·결과 53개
처음으로통합 문서 안에서 Excel 수식, VBA, Python을 자동으로 작성·실행·검증하는 AI 에이전트
통합 문서 안에서 Excel 수식, VBA, Python을 자동으로 작성·실행·검증하는 AI 에이전트
Abyss turns a Python project into a shareable, pay-per-run web tool. You upload your scripts, describe the inputs, and Abyss wraps them in a Widget with a form, a public link, and a price per run — while your API keys stay on your side.
실시간 기술 면접을 위한 탐지되지 않는 AI 어시스턴트
코딩 에이전트를 위한 지능형 모델 라우팅
reCAPTCHA와 Cloudflare 등을 0.7초 이내에 해결
탐지되지 않는 면접·회의용 AI 코파일럿

AI SDK Agents is a resource hub of full-stack patterns and components for building AI applications with the Vercel AI SDK. It collects practical examples for tool calling, streaming responses, multi-step workflows, and agent orchestration using React, Next.js, and TypeScript.
AI SDK Agents is a resource hub of full-stack patterns and components for building AI applications with the Vercel AI SDK. It collects practical examples for tool calling, streaming responses, multi-step workflows, and agent orchestration using React, Next.js, and TypeScript.
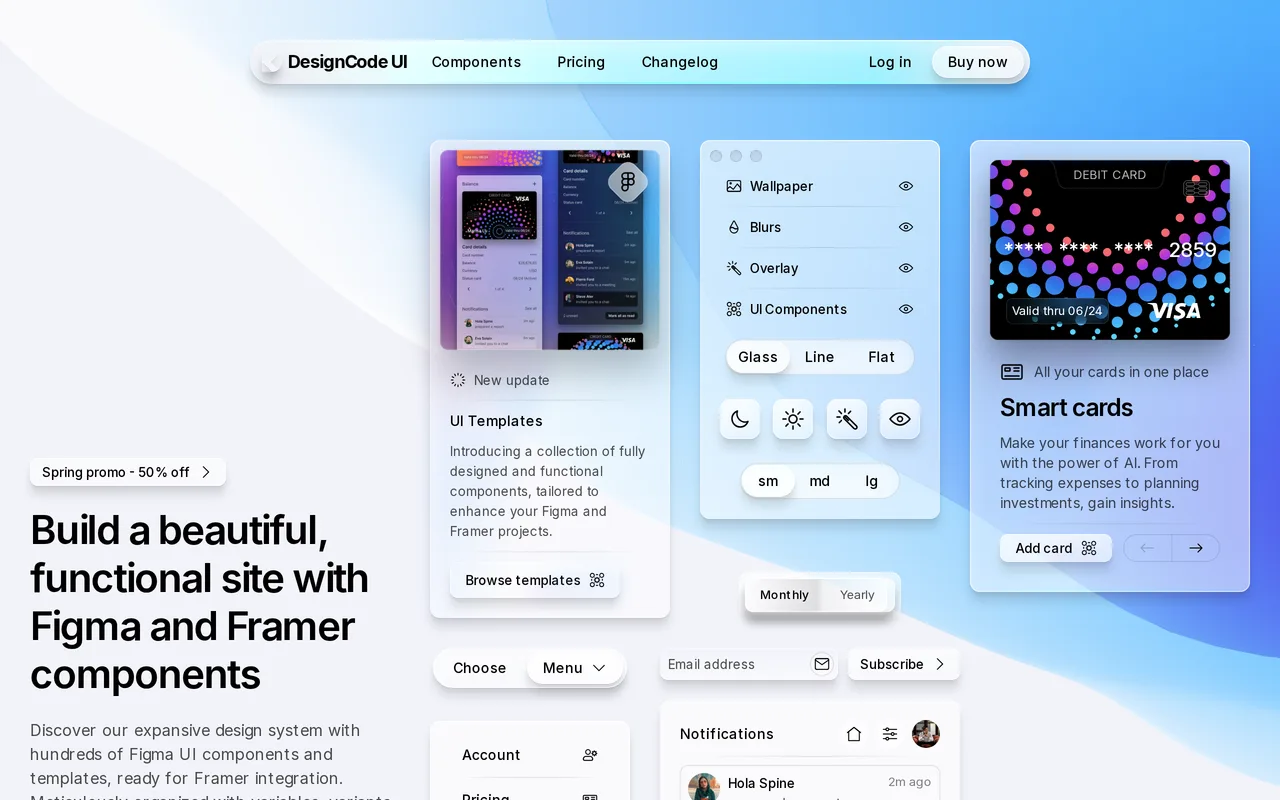
변수·배리언트·적응형 레이아웃을 갖춘 대규모 Figma 및 Framer UI 컴포넌트 라이브러리
변수·배리언트·적응형 레이아웃을 갖춘 대규모 Figma 및 Framer UI 컴포넌트 라이브러리
UltiHash is high-throughput, S3-compatible object storage engineered for AI workloads. It accelerates inference, training and RAG pipelines, cuts storage costs with binary-level deduplication, and deploys either as a managed serverless service or self-hosted on Kubernetes.
UltiHash is high-throughput, S3-compatible object storage engineered for AI workloads. It accelerates inference, training and RAG pipelines, cuts storage costs with binary-level deduplication, and deploys either as a managed serverless service or self-hosted on Kubernetes.
Startups.RIP is a research library of 2,200+ startup stories — including many Y Combinator companies — that documents what each one built, how it ended, and how you could rebuild it today. Free accounts browse research reports and build plans; Pro adds implementation-ready technical specs and a CLI that imports the research into coding agents like Claude and Codex.
Startups.RIP is a research library of 2,200+ startup stories — including many Y Combinator companies — that documents what each one built, how it ended, and how you could rebuild it today. Free accounts browse research reports and build plans; Pro adds implementation-ready technical specs and a CLI that imports the research into coding agents like Claude and Codex.

텍스트를 코드로 바꾸는 AI 코딩 어시스턴트
규제 업무 워크플로를 끝까지 완수하는 AI 실행 플랫폼
VS Code와 클라우드에서 함께 쓰는 AI 코딩 에이전트

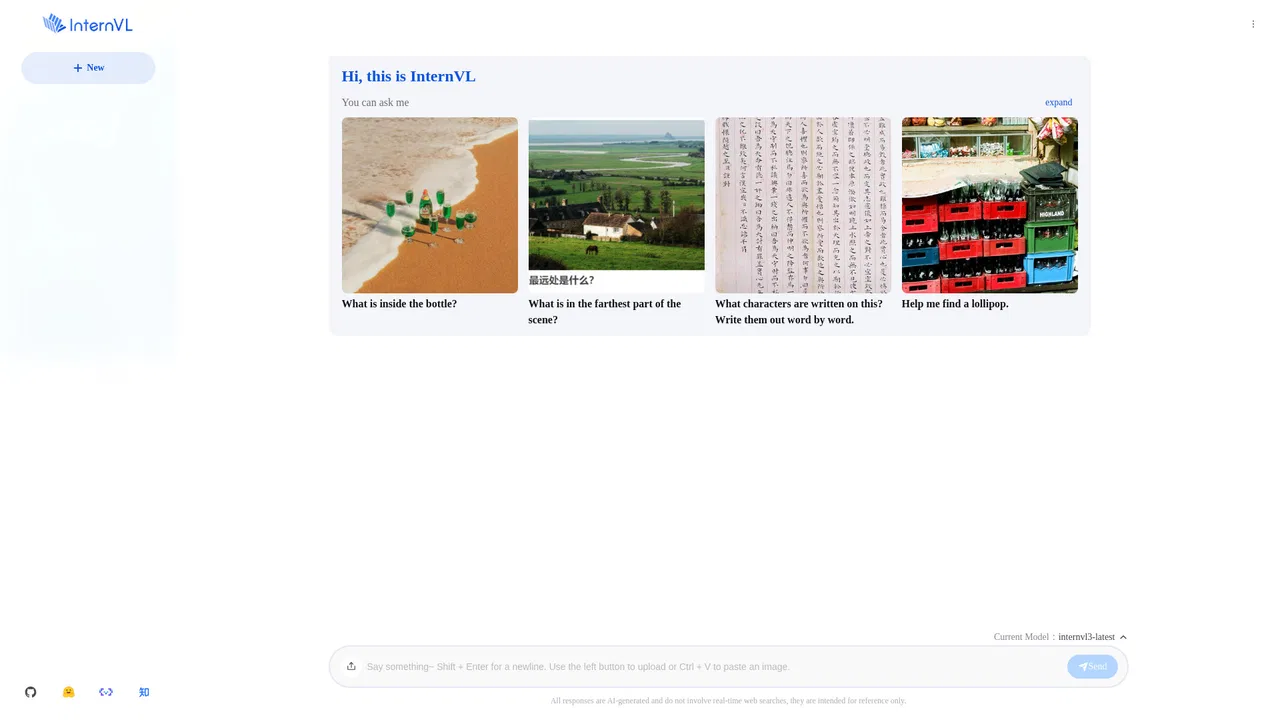
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
Tempo is an AI software factory and collaborative IDE for product teams. It turns customer feedback, issues and product requirements into reviewed pull requests, with AI agents handling the implementation while your team approves the key decisions.

코딩 에이전트에 올바른 컨텍스트를 빠르게 전달하는 MCP 코드 검색
코딩 에이전트에 올바른 컨텍스트를 빠르게 전달하는 MCP 코드 검색

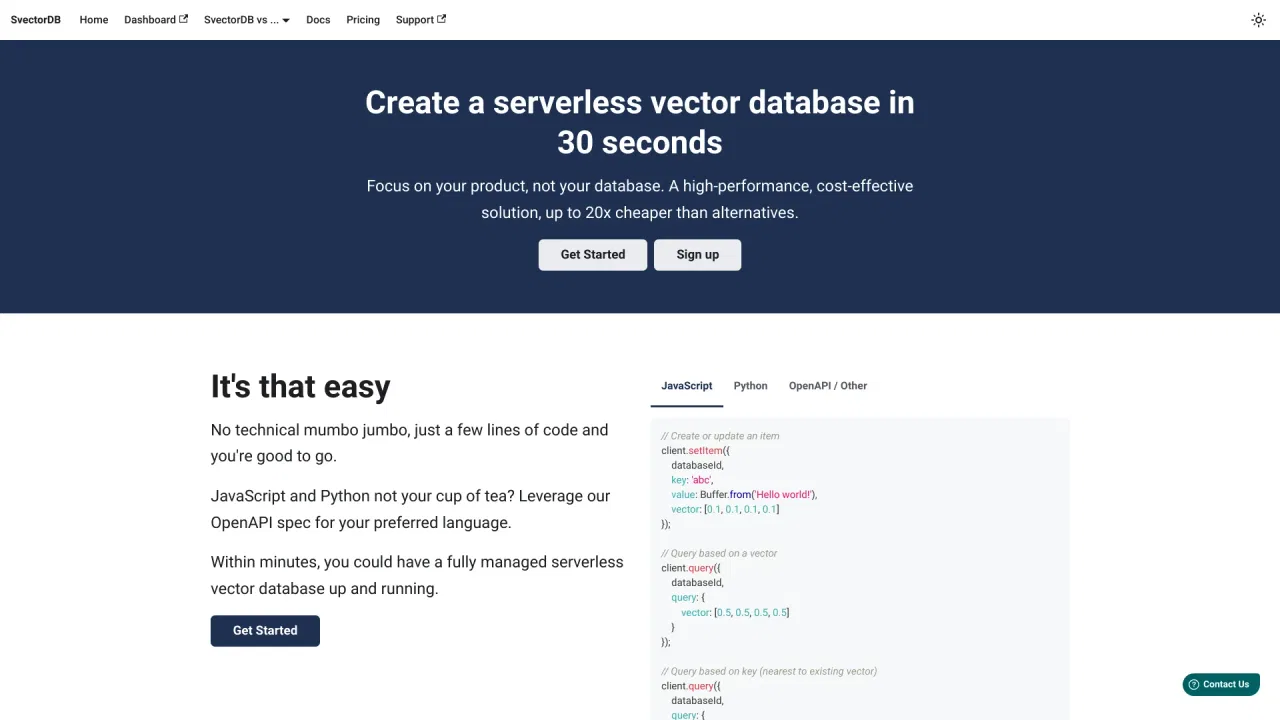
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.

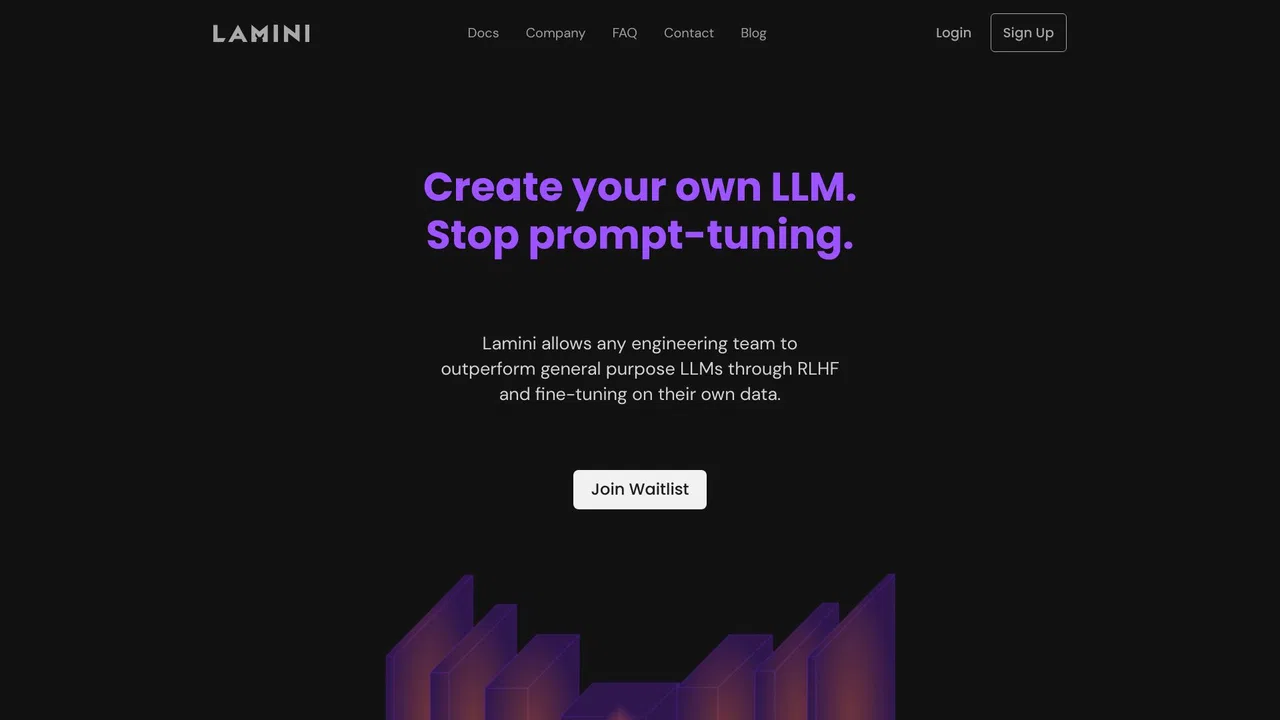
Lamini is an enterprise LLM platform for building, fine-tuning, controlling and deploying custom large language models. It targets teams that need their own accurate, private models rather than a generic API: you bring your data, fine-tune open models on the platform, and serve them with tuned runtimes designed to reduce hallucinations. It covers use cases like text-to-SQL, classification, RAG and function calling, and is known for running workloads on AMD GPUs.
Lamini is an enterprise LLM platform for building, fine-tuning, controlling and deploying custom large language models. It targets teams that need their own accurate, private models rather than a generic API: you bring your data, fine-tune open models on the platform, and serve them with tuned runtimes designed to reduce hallucinations. It covers use cases like text-to-SQL, classification, RAG and function calling, and is known for running workloads on AMD GPUs.