PNG·JPG·BMP 이미지를 확대 가능한 SVG·EPS·DXF 벡터로 변환
AI 벡터 그래픽에디터 평점: 4.3무료 체험, 유료직접 유입 29%

PNG·JPG·BMP 이미지를 확대 가능한 SVG·EPS·DXF 벡터로 변환
무료 체험, 유료
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Image” · 코딩 및 소프트웨어 개발·결과 321개
처음으로PNG·JPG·BMP 이미지를 확대 가능한 SVG·EPS·DXF 벡터로 변환
PNG·JPG·BMP 이미지를 확대 가능한 SVG·EPS·DXF 벡터로 변환

실시간 이미지·동영상 API, 에이전트 DAM, 크리에이티브 자동화를 한곳에
판단 근거까지 보여주는 AI 이미지·딥페이크 포렌식 도구
500개 이상의 이미지·비디오·오디오·LLM 모델을 하나의 OpenAI 호환 API로

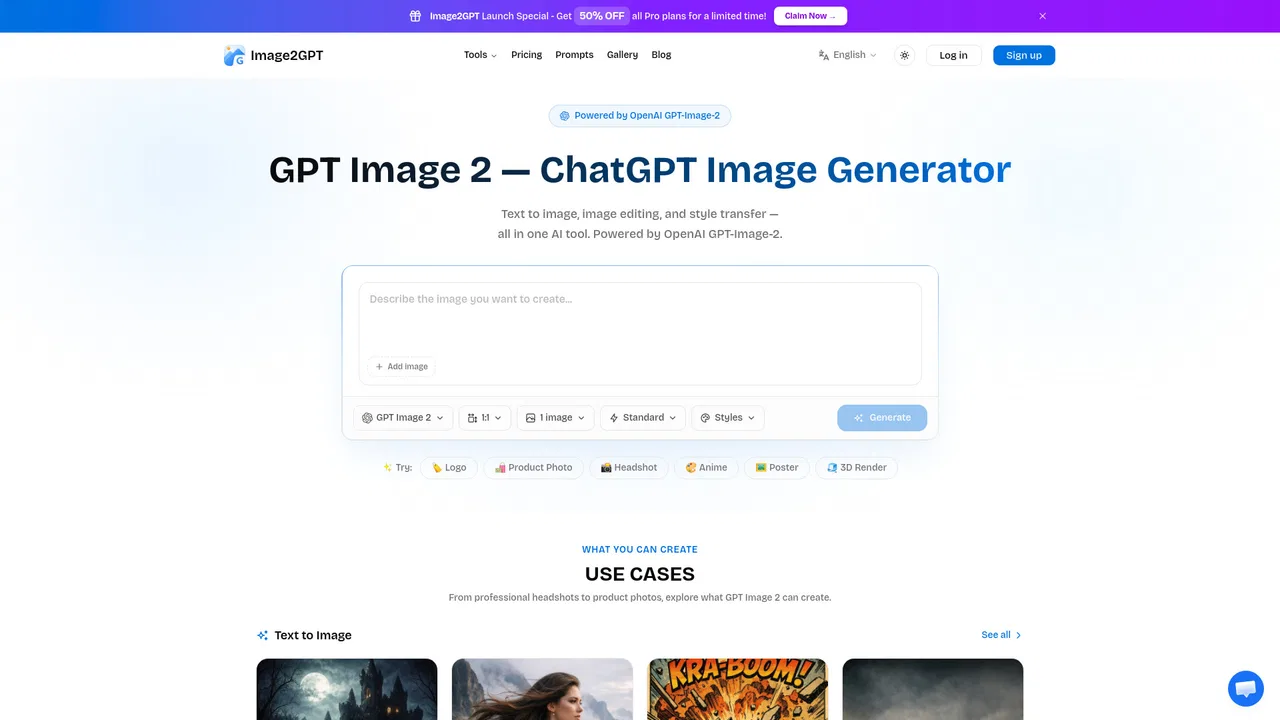
GPT Image 2 is a free-to-try online AI image generator and photo editor that produces 4K images with high text-rendering accuracy, plus background removal, smart inpainting, and multi-style output in one browser tool.
GPT Image 2 is a free-to-try online AI image generator and photo editor that produces 4K images with high text-rendering accuracy, plus background removal, smart inpainting, and multi-style output in one browser tool.

GPT-6와 GPT-5.6으로 추론, 코딩, 심층 리서치를 수행하는 OpenAI의 대표 멀티모달 어시스턴트.

Flux1 AI is a browser-based AI image and video generator that runs Black Forest Labs' FLUX models alongside other leading image and video models, with no GPU or installation required.
Flux1 AI is a browser-based AI image and video generator that runs Black Forest Labs' FLUX models alongside other leading image and video models, with no GPU or installation required.

원본 그림은 그대로, 생일본 만화를 페이지 단위로 번역

reAPI hosts GPT Image 2.5 behind a single OpenAI-compatible image endpoint, so you can call OpenAI's image generation and editing model with the same API key you already use for every other model in the catalog. Text-to-image, reference edits, and masked inpainting run through one request lifecycle.
reAPI hosts GPT Image 2.5 behind a single OpenAI-compatible image endpoint, so you can call OpenAI's image generation and editing model with the same API key you already use for every other model in the catalog. Text-to-image, reference edits, and masked inpainting run through one request lifecycle.
FLUX.1 Schnell, Pro, Dev, Realism-LoRA 이미지 모델을 브라우저에서 바로 실행
FLUX.1 Schnell, Pro, Dev, Realism-LoRA 이미지 모델을 브라우저에서 바로 실행
MiniMax Image-01 is MiniMax's open-weight image generation model, available through the MiniMax API and MiniMax Design. It turns text prompts into high-resolution visuals and powers image workflows inside MiniMax's broader model family.
MiniMax Image-01 is MiniMax's open-weight image generation model, available through the MiniMax API and MiniMax Design. It turns text prompts into high-resolution visuals and powers image workflows inside MiniMax's broader model family.

GPT-6 Astra, Sol, Luna와 실시간 멀티모달 에이전트를 배포하기 위한 엔터프라이즈 개발자 플랫폼 및 API.
MAI Image 2 is an independent browser workspace for the MAI-Image-2 family of text-to-image models. It provides a prompt editor where you can generate photorealistic images, marketing stills, posters and simple infographics, plus reference pages covering benchmarks, features and model comparisons. It is a third-party platform and is not affiliated with or operated by the model's original developers.
MAI Image 2 is an independent browser workspace for the MAI-Image-2 family of text-to-image models. It provides a prompt editor where you can generate photorealistic images, marketing stills, posters and simple infographics, plus reference pages covering benchmarks, features and model comparisons. It is a third-party platform and is not affiliated with or operated by the model's original developers.
LLM, 이미지, 비디오, 오디오 모델을 하나의 API로 프로덕션에
LLM, 이미지, 비디오, 오디오 모델을 하나의 API로 프로덕션에

1,500개 이상의 실전용 생성 미디어 모델을 하나의 API로
RunningHub is a cloud platform for running ComfyUI workflows online, building AI apps, and generating images and videos with hosted models and APIs.
RunningHub is a cloud platform for running ComfyUI workflows online, building AI apps, and generating images and videos with hosted models and APIs.
Kie.ai's Nano Banana Pro API gives developers pay-as-you-go access to Google's Gemini 3 Pro Image model for 1K, 2K, and 4K image generation and editing with strong text rendering and character consistency.
Kie.ai's Nano Banana Pro API gives developers pay-as-you-go access to Google's Gemini 3 Pro Image model for 1K, 2K, and 4K image generation and editing with strong text rendering and character consistency.
지우고 싶은 곳을 칠하면 몇 초 만에 사라집니다

Vidu is a multimodal generative video platform from ShengShu Technology. It turns text prompts, still images, and reference footage into short cinematic clips, with tools for subject-consistent characters, anime styles, and sound-effect generation.
Vidu is a multimodal generative video platform from ShengShu Technology. It turns text prompts, still images, and reference footage into short cinematic clips, with tools for subject-consistent characters, anime styles, and sound-effect generation.