Caveman오픈소스
17.2만/월
복구 가능한 컨텍스트 압축과 스마트 모델 라우팅으로 AI 에이전트 토큰 비용 절감
AI 개발자 도구에디터 평점: 4.7무료+유료, 가격 문의직접 유입 37%
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Token optimization” · 코딩 및 소프트웨어 개발·결과 124개
처음으로복구 가능한 컨텍스트 압축과 스마트 모델 라우팅으로 AI 에이전트 토큰 비용 절감
DeepSeek-V4와 R1으로 구동되는, 극히 낮은 토큰 비용의 고효율 오픈웨이트·호스팅 추론 AI.
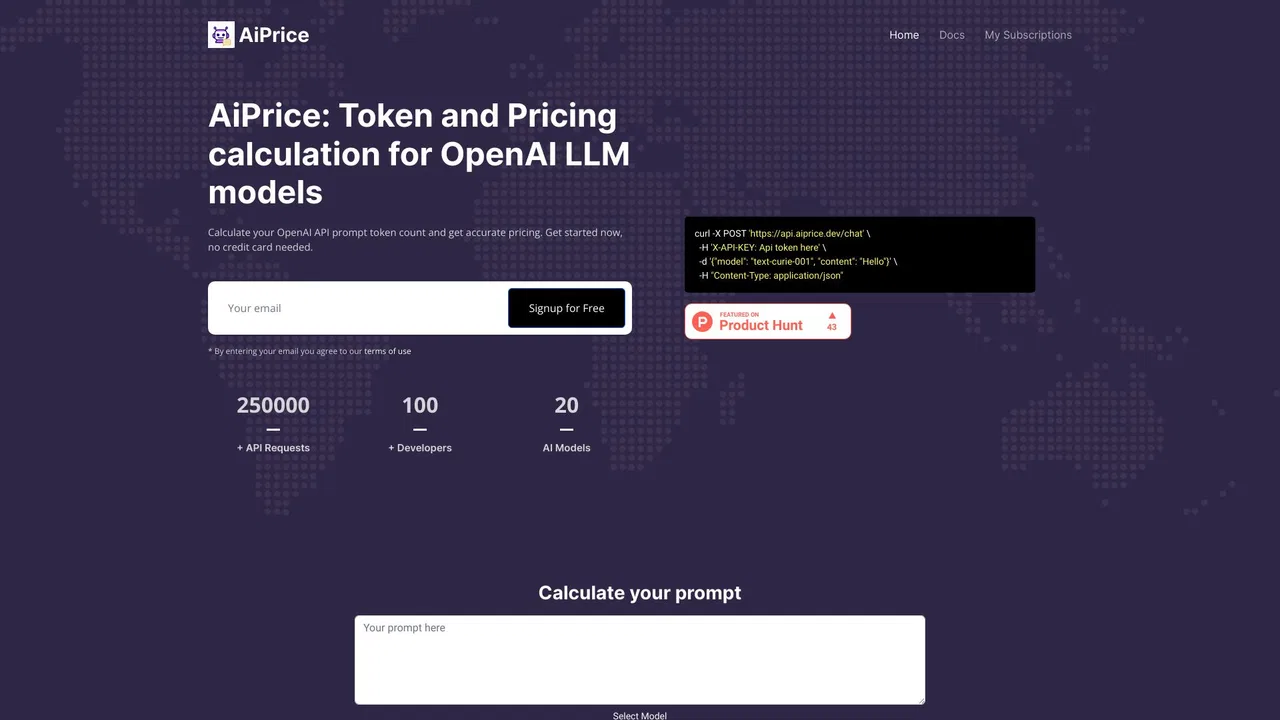
OpenAI 프롬프트가 몇 토큰을 쓰는지 정확히 확인하세요

GPT-6 Astra, Sol, Luna와 실시간 멀티모달 에이전트를 배포하기 위한 엔터프라이즈 개발자 플랫폼 및 API.

Gemini 모델로 멀티모달 애플리케이션을 구축하기 위한 Google의 신속한 프로토타이핑 IDE이자 개발자 API 워크벤치.
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.

실시간 이미지·동영상 API, 에이전트 DAM, 크리에이티브 자동화를 한곳에

알리바바 클라우드의 4세대 파운데이션 모델 패밀리 및 멀티모달 AI 어시스턴트 — Qwen 4 (Qwen4), Qwen4-Max, Qwen4-Plus, Qwen4-Flash, Qwen4-27B 및 Qwen 3.8-Flash-Next 아키텍처
알리바바 클라우드의 4세대 파운데이션 모델 패밀리 및 멀티모달 AI 어시스턴트 — Qwen 4 (Qwen4), Qwen4-Max, Qwen4-Plus, Qwen4-Flash, Qwen4-27B 및 Qwen 3.8-Flash-Next 아키텍처

당신의 코딩 취향을 학습하는 AI 코딩 에이전트

Honcho is an open-source memory layer for AI agents. It ingests messages, indexes them, and runs background reasoning so agents can recall who a user is, what happened before, and what to do next — across sessions, tools, and machines.

Google DeepMind의 세계 1위 사이버 보안 방어 및 장기 에이전틱 엔지니어링 프런티어 모델 — Gemini 4 Argon을 잇는 Gemini 4 Carbon (Gemini Carbon 4)
Google DeepMind의 세계 1위 사이버 보안 방어 및 장기 에이전틱 엔지니어링 프런티어 모델 — Gemini 4 Argon을 잇는 Gemini 4 Carbon (Gemini Carbon 4)

즈푸 AI의 GLM 대형 모델 개방 플랫폼, 멀티모달 API와 에이전트 개발을 한곳에서

reCAPTCHA와 Cloudflare 등을 0.7초 이내에 해결
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
나쁜 거래가 성사되기 전에 막는 토큰 보안 API
Unsloth is an open-source toolkit for running and training large language models locally. It provides faster, more memory-efficient fine-tuning, a local chat and agent environment with browser use, image and video generation, and an OpenAI-compatible API your existing tools can connect to.
Unsloth is an open-source toolkit for running and training large language models locally. It provides faster, more memory-efficient fine-tuning, a local chat and agent environment with browser use, image and video generation, and an OpenAI-compatible API your existing tools can connect to.