ImageKit공식
94.8만/월
실시간 이미지·동영상 API, 에이전트 DAM, 크리에이티브 자동화를 한곳에
AI API에디터 평점: 4.7무료+유료, 유료, 가격 문의직접 유입 48%
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Background task processing” · 이미지 분석 및 인식·결과 16개
처음으로실시간 이미지·동영상 API, 에이전트 DAM, 크리에이티브 자동화를 한곳에

Dewatermark AI is a browser-based watermark remover that uses AI inpainting and GAN models to strip text, logos, timestamps, signatures and emoji overlays from images and videos while rebuilding the pixels underneath. Unlike simple blur or crop tools, it reconstructs backgrounds so results look clean instead of smudged. Three removal models, a manual brush and batch processing cover everything from quick single-photo cleanups to bulk e-commerce catalogs.
Dewatermark AI is a browser-based watermark remover that uses AI inpainting and GAN models to strip text, logos, timestamps, signatures and emoji overlays from images and videos while rebuilding the pixels underneath. Unlike simple blur or crop tools, it reconstructs backgrounds so results look clean instead of smudged. Three removal models, a manual brush and batch processing cover everything from quick single-photo cleanups to bulk e-commerce catalogs.


프로세스를 설명하면 완전 자동화된 워크플로가 만들어집니다
AI 컬링·편집·리터칭으로 사진가의 시간을 되돌려줍니다


TheToolBus is a free online utility hub offering a large library of browser-based tools for PDF editing, image conversion, file conversion, calculators, text manipulation, and everyday productivity tasks. Almost everything runs without signup or watermarks.
TheToolBus is a free online utility hub offering a large library of browser-based tools for PDF editing, image conversion, file conversion, calculators, text manipulation, and everyday productivity tasks. Almost everything runs without signup or watermarks.
.NET 애플리케이션 안에 프라이빗 생성형 AI, RAG, 에이전트를 직접 내장

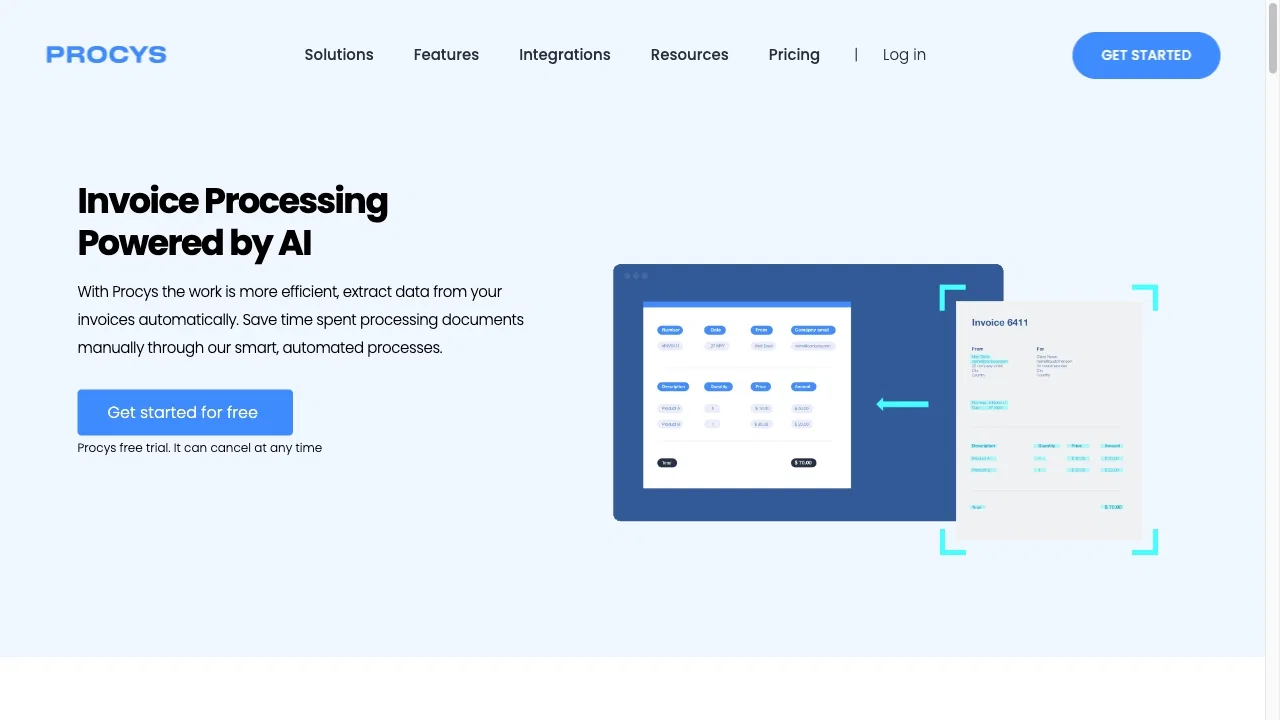
Procys is an AI document automation platform that extracts structured data from invoices, receipts, purchase orders and ID documents, and syncs the results into accounting and ERP systems.

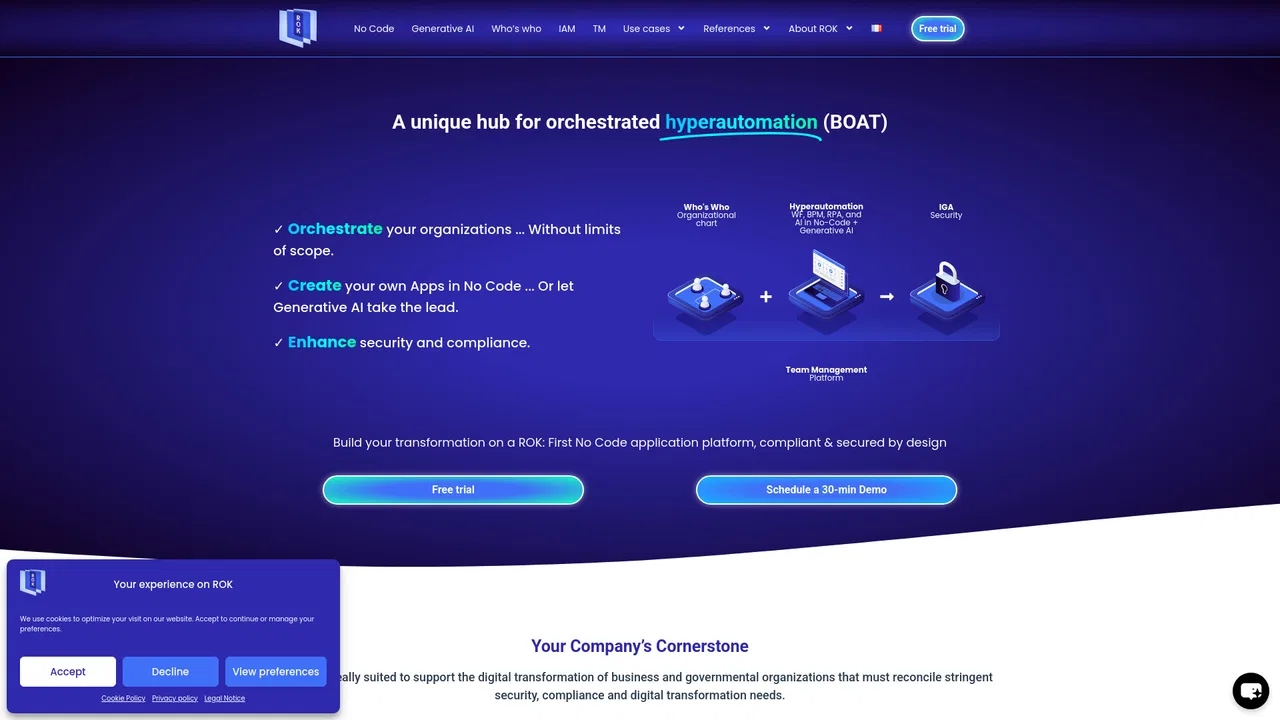
실제 조직도를 중심에 둔 조직 중심 하이퍼오토메이션 플랫폼

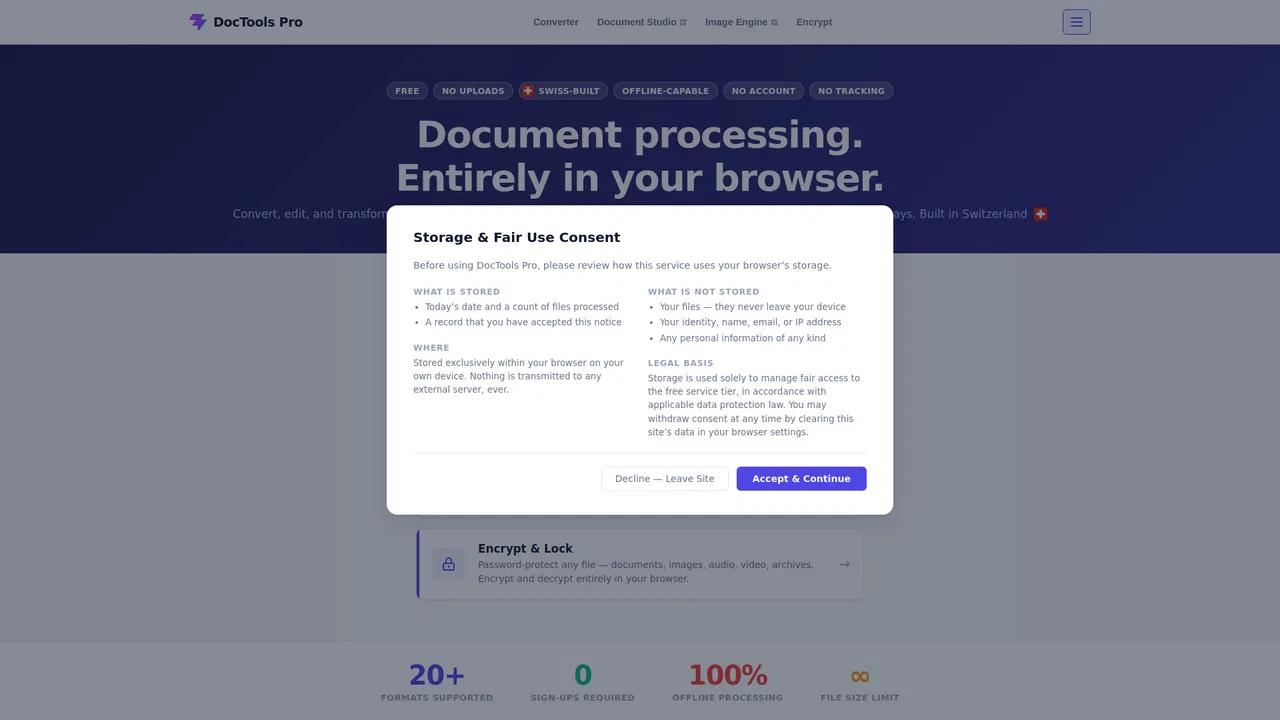
DocTools Pro is a free, browser-based toolkit for everyday document and image jobs: merging and splitting PDFs, converting between 20+ formats, compressing files, running OCR, removing image backgrounds and password-protecting anything. It is built in Switzerland and designed around local processing — files are handled in your browser's memory and never uploaded to a server, so there is no account, no file-size cap and nothing stored on the provider's side.
DocTools Pro is a free, browser-based toolkit for everyday document and image jobs: merging and splitting PDFs, converting between 20+ formats, compressing files, running OCR, removing image backgrounds and password-protecting anything. It is built in Switzerland and designed around local processing — files are handled in your browser's memory and never uploaded to a server, so there is no account, no file-size cap and nothing stored on the provider's side.

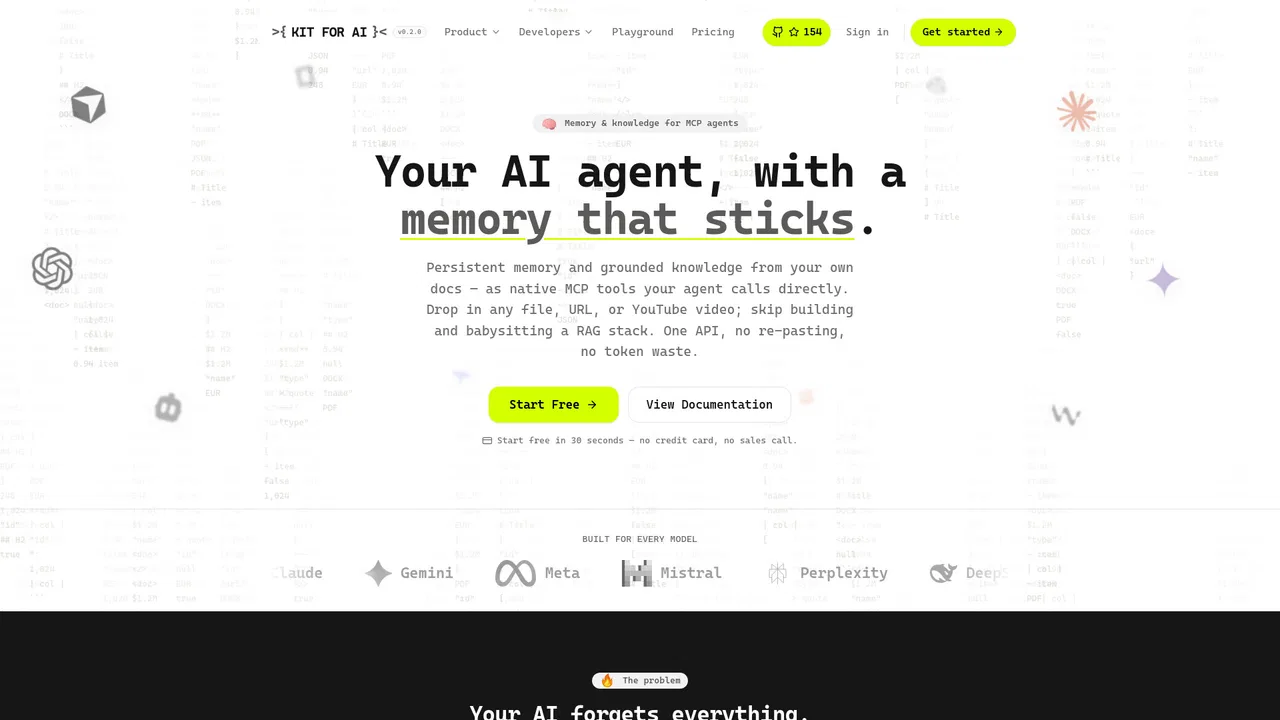
네이티브 MCP 도구로 AI 에이전트에 지속적 메모리와 근거 있는 지식을 제공
dodocs.ai is an AI accounting operations platform for CPA firms, bookkeepers and finance teams. Its Matchpoint agent layer captures invoices, receipts and bank statements from email, WhatsApp or mobile upload, extracts and codes the data with OCR, reconciles it against statements, chases missing documents automatically and publishes the result to QuickBooks Online, Xero or Zoho.
dodocs.ai is an AI accounting operations platform for CPA firms, bookkeepers and finance teams. Its Matchpoint agent layer captures invoices, receipts and bank statements from email, WhatsApp or mobile upload, extracts and codes the data with OCR, reconciles it against statements, chases missing documents automatically and publishes the result to QuickBooks Online, Xero or Zoho.

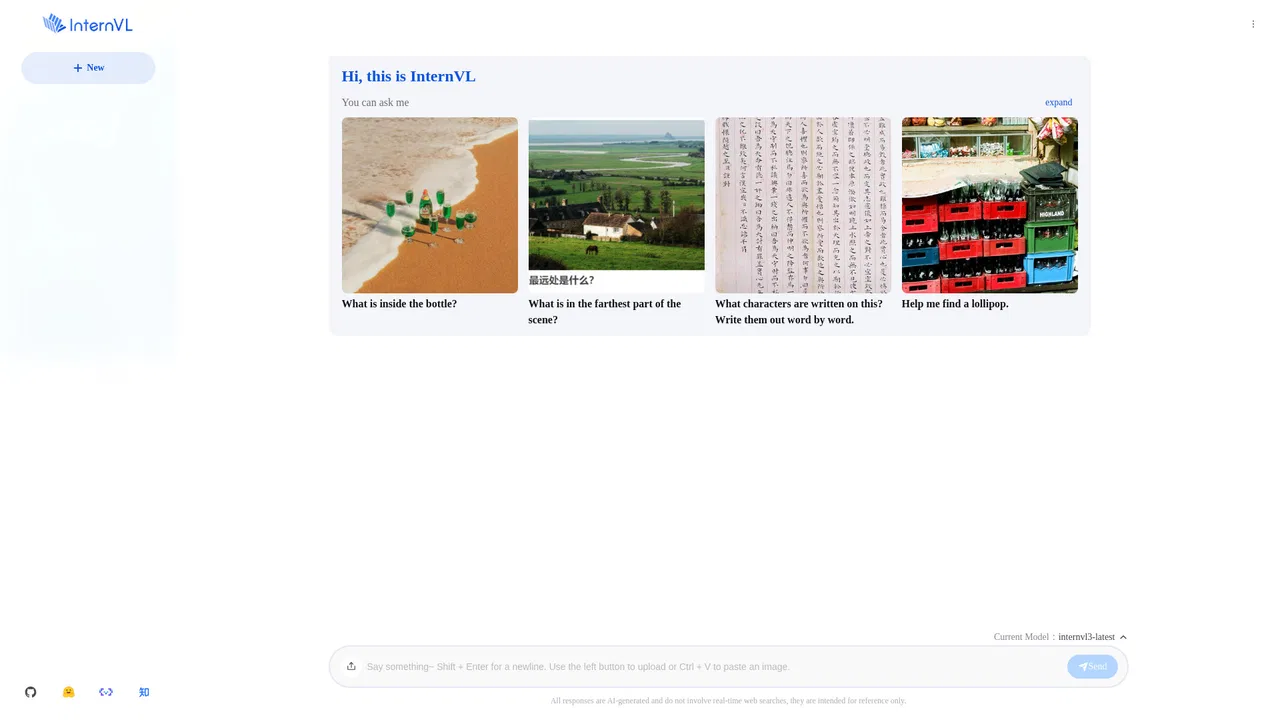
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.