DeepSeek공식
3.7억/월
DeepSeek-V4와 R1으로 구동되는, 극히 낮은 토큰 비용의 고효율 오픈웨이트·호스팅 추론 AI.
Large Language Models (LLMs)에디터 평점: 4.8무료+유료+4.3%

무료+유료
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Python Implementation” · 파운데이션 모델 및 인프라·결과 140개
처음으로DeepSeek-V4와 R1으로 구동되는, 극히 낮은 토큰 비용의 고효율 오픈웨이트·호스팅 추론 AI.

500개 이상의 이미지·비디오·오디오·LLM 모델을 하나의 OpenAI 호환 API로

Metaflow is Netflix's open-source Python framework for building, running, and operating real-world machine learning, AI, and data science workflows. It keeps your code in plain Python while handling dependency management, versioning, orchestration, and elastic cloud compute.
Metaflow is Netflix's open-source Python framework for building, running, and operating real-world machine learning, AI, and data science workflows. It keeps your code in plain Python while handling dependency management, versioning, orchestration, and elastic cloud compute.

자체 정책으로 통제하는 무제한 OpenAI 호환 LLM API
자체 정책으로 통제하는 무제한 OpenAI 호환 LLM API

하나의 API로 LLM과 멀티모달 모델을 빠르고 예측 가능한 비용으로 추론
하나의 API로 LLM과 멀티모달 모델을 빠르고 예측 가능한 비용으로 추론


500개 이상의 AI 모델과 1,000개 이상의 에이전트 도구를 하나의 API로
ChatGPT, Claude, Gemini 등 30개 이상의 AI 모델을 한 구독으로 나란히 비교
ChatGPT, Claude, Gemini 등 30개 이상의 AI 모델을 한 구독으로 나란히 비교
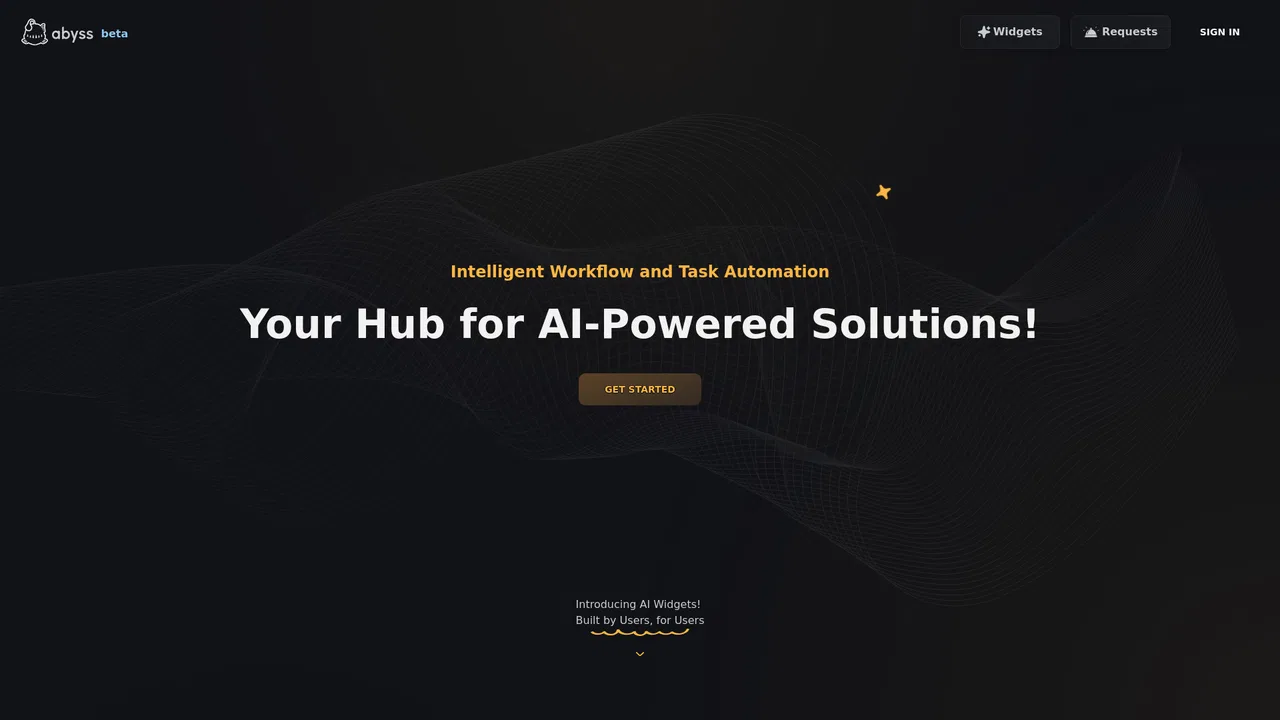
Abyss turns a Python project into a shareable, pay-per-run web tool. You upload your scripts, describe the inputs, and Abyss wraps them in a Widget with a form, a public link, and a price per run — while your API keys stay on your side.
코딩 에이전트를 위한 지능형 모델 라우팅

전문 AI 모델 호스팅, 최적화 엔드포인트, 온디맨드 GPU 인프라
Open Interpreter is an open-source coding agent that lets language models write and run code directly on your own machine, turning plain-English instructions into real files, charts, and automations.
Open Interpreter is an open-source coding agent that lets language models write and run code directly on your own machine, turning plain-English instructions into real files, charts, and automations.
OpenAI 오픈 웨이트 gpt-oss 모델을 체험하는 데모 환경


에이전트를 위한 빠른 오픈 모델 추론과 웜 캐시 라우팅
에이전트를 위한 빠른 오픈 모델 추론과 웜 캐시 라우팅
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.

지연 시간 기반 요금제의 고처리량 오픈 웨이트 추론
당신을 맞이할 호그와트 기숙사를 찾아보세요