158/mo
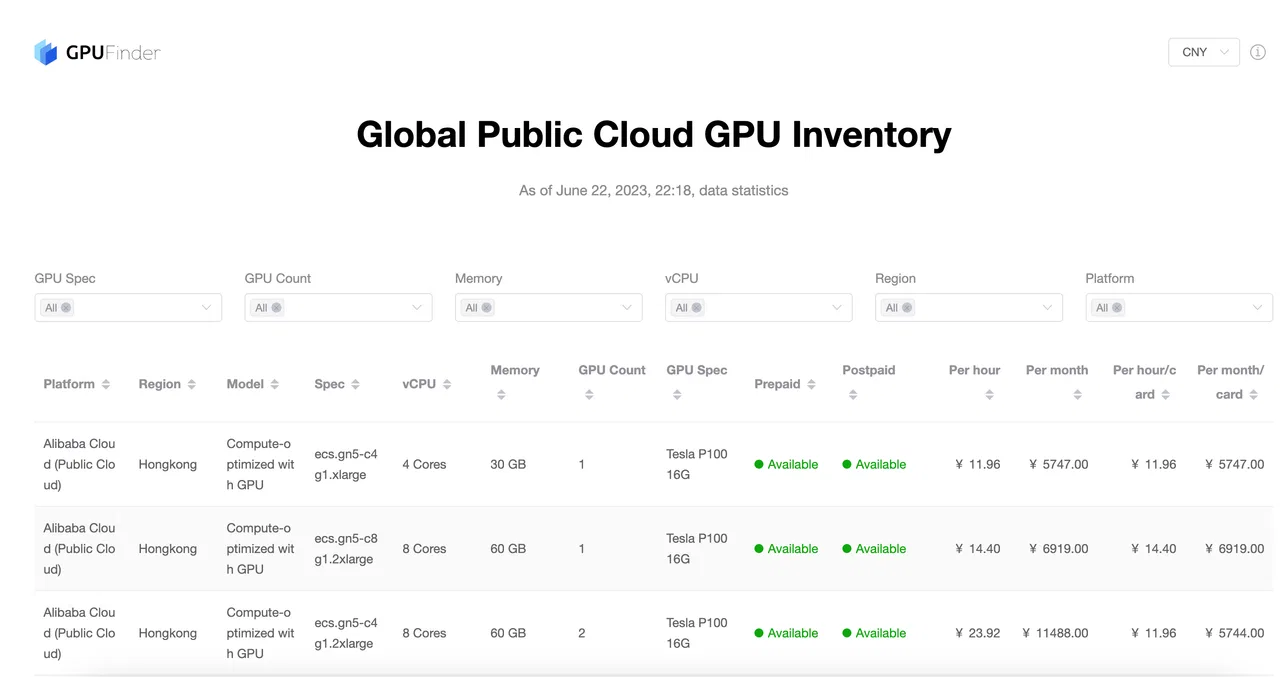
Compare public cloud GPU instance specs and prices in one table
OtherEditorial score: 3.6Free+187.3%
158/mo+187.3%
Compare public cloud GPU instance specs and prices in one table
Free
Compare AI products across 459 workflows using traffic estimates, features, and alternatives.
“GPU server”·136 results
Start overCompare public cloud GPU instance specs and prices in one table
Compare public cloud GPU instance specs and prices in one table
Your own dedicated GPU workspace for open-source AI art and video
Your own dedicated GPU workspace for open-source AI art and video
VRAM, throughput and GPU cost calculators plus courses for open-weight LLM deployment
VRAM, throughput and GPU cost calculators plus courses for open-weight LLM deployment

One API for 400K+ AI models, plus serverless and reserved GPUs on modular data centers

Cheap on-demand GPU and CPU pods, ready in one click
Cheap on-demand GPU and CPU pods, ready in one click

Check which local AI models your GPU or Mac can actually run
Check which local AI models your GPU or Mac can actually run

Private AI cloud for training and inference workloads
Private AI cloud for training and inference workloads
Create AI art without a GPU or an account
Create AI art without a GPU or an account

On-demand GPU cloud and enterprise AI infrastructure from the creators of PyTorch Lightning.
On-demand GPU cloud and enterprise AI infrastructure from the creators of PyTorch Lightning.

Specialized AI model hosting, optimized endpoints, and on-demand GPU infrastructure
Specialized AI model hosting, optimized endpoints, and on-demand GPU infrastructure
One OpenAI-compatible API for 500+ image, video, audio, and LLM models
One OpenAI-compatible API for 500+ image, video, audio, and LLM models
Shared GPU cluster for open models, billed at a flat rate instead of per token
Shared GPU cluster for open models, billed at a flat rate instead of per token

AI infrastructure and GPU cloud powered by the AITECH token
AI infrastructure and GPU cloud powered by the AITECH token
Build, run and scale AI, from open models to governed agents
Rent high-performance European GPUs by the hour for AI and HPC
Rent high-performance European GPUs by the hour for AI and HPC

Native macOS inference server that makes local LLMs instant for coding agents
Native macOS inference server that makes local LLMs instant for coding agents
An inference cloud built on alternative chips, delivering ultra-fast tokens through disaggregated prefill and decode.
An inference cloud built on alternative chips, delivering ultra-fast tokens through disaggregated prefill and decode.

Managed Ray platform for scaling AI workloads

Open models served fast, with warm-cache routing for agents
Open models served fast, with warm-cache routing for agents

Turn a single image into a downloadable 3D model in minutes, no GPU required.
Turn a single image into a downloadable 3D model in minutes, no GPU required.
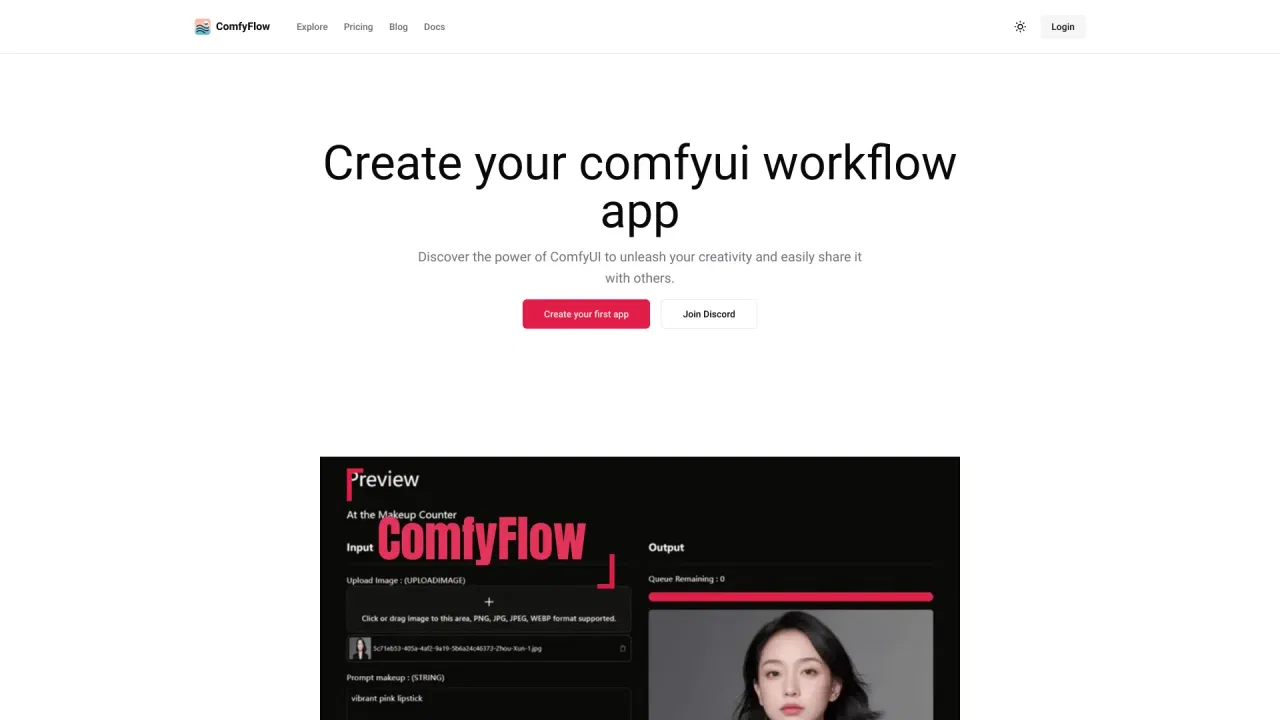
Turn ComfyUI workflows into shareable web apps in seconds
All the best AI tools, one platform, one license
All the best AI tools, one platform, one license
Stable Diffusion models on fast GPUs, served through a cheap, reliable API
Stable Diffusion models on fast GPUs, served through a cheap, reliable API

Cloud Linux VMs built for developers and their AI agents
Cloud Linux VMs built for developers and their AI agents