8.3K/mo
See exactly how many tokens your OpenAI prompt will use
AI Developer ToolsEditorial score: 4.3Free40% direct

8.3K/mo
See exactly how many tokens your OpenAI prompt will use
Free
Compare AI products across 459 workflows using traffic estimates, features, and alternatives.

“OpenAI token counter”·50 results
Start overSee exactly how many tokens your OpenAI prompt will use
See exactly how many tokens your OpenAI prompt will use

Enterprise developer platform and API for deploying GPT-6 Astra, Sol, Luna, and realtime multimodal agents.
Enterprise developer platform and API for deploying GPT-6 Astra, Sol, Luna, and realtime multimodal agents.
High-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
High-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
Estimate OpenAI prompt tokens and cost before you make the API call

The coding agent that learns your coding taste
The coding agent that learns your coding taste

Serverless, decentralized inference for open-source AI models
Open-source AI memory that reasons, not just stores
Meter, budget and route every LLM call so AI spend is controlled before it happens
Meter, budget and route every LLM call so AI spend is controlled before it happens

One verifiable API key for Claude, GPT, Kimi and Grok at a fraction of list price
Shared GPU cluster for open models, billed at a flat rate instead of per token
Shared GPU cluster for open models, billed at a flat rate instead of per token
Combine any files into one AI-ready bundle, right in your browser
Combine any files into one AI-ready bundle, right in your browser
An inference cloud built on alternative chips, delivering ultra-fast tokens through disaggregated prefill and decode.
An inference cloud built on alternative chips, delivering ultra-fast tokens through disaggregated prefill and decode.

Compare LLM API token prices across every major provider
Compare LLM API token prices across every major provider
Offline desktop AI voice studio with unlimited local generation
Offline desktop AI voice studio with unlimited local generation

High-throughput open-weight inference with latency-based pricing
High-throughput open-weight inference with latency-based pricing
Agent gateway that routes, compresses and observes your LLM token spend
Know what your coding agents built before you ship
Deploy a managed OpenClaw AI agent in 30 seconds
Count prompt tokens and price them across 300+ LLM models instantly
Count prompt tokens and price them across 300+ LLM models instantly
One API key for 40+ AI models with zero markup
Third-party API relay that puts Claude, GPT, Grok and more behind one balance and one Base URL
Third-party API relay that puts Claude, GPT, Grok and more behind one balance and one Base URL
Count tokens and estimate GPT prompt costs across models
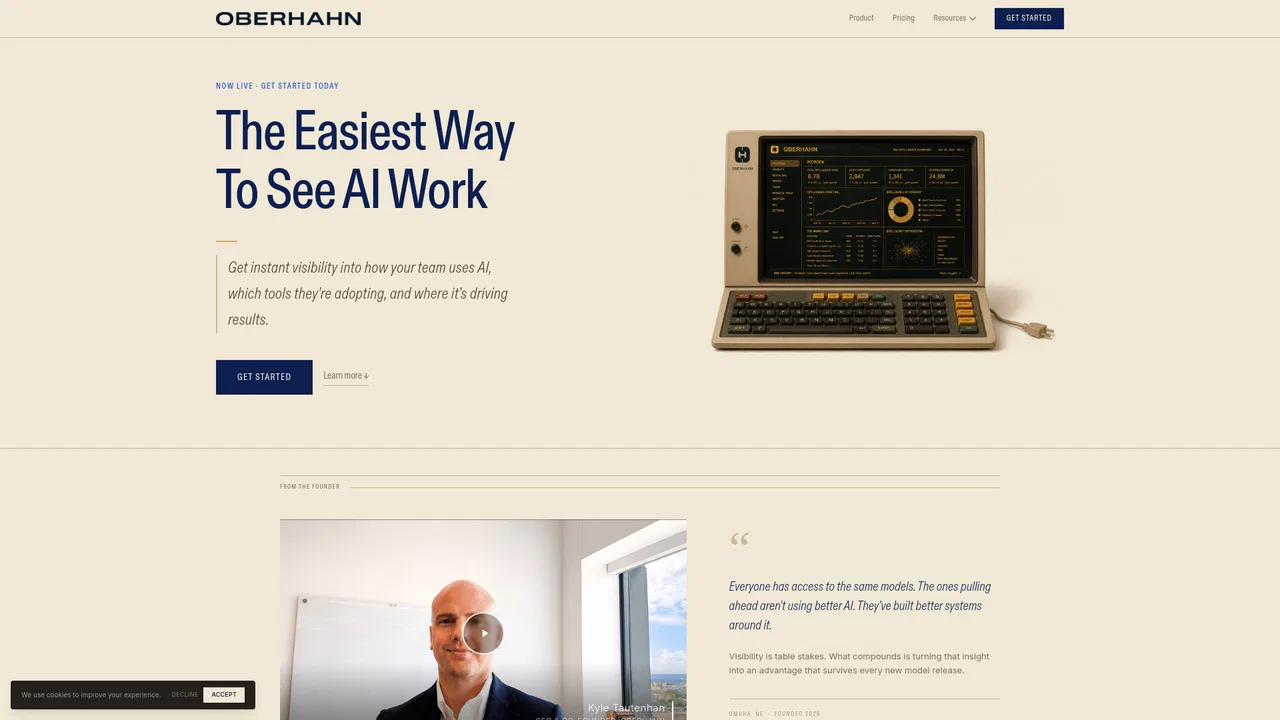
Know exactly what your AI spend bought.
Know exactly what your AI spend bought.
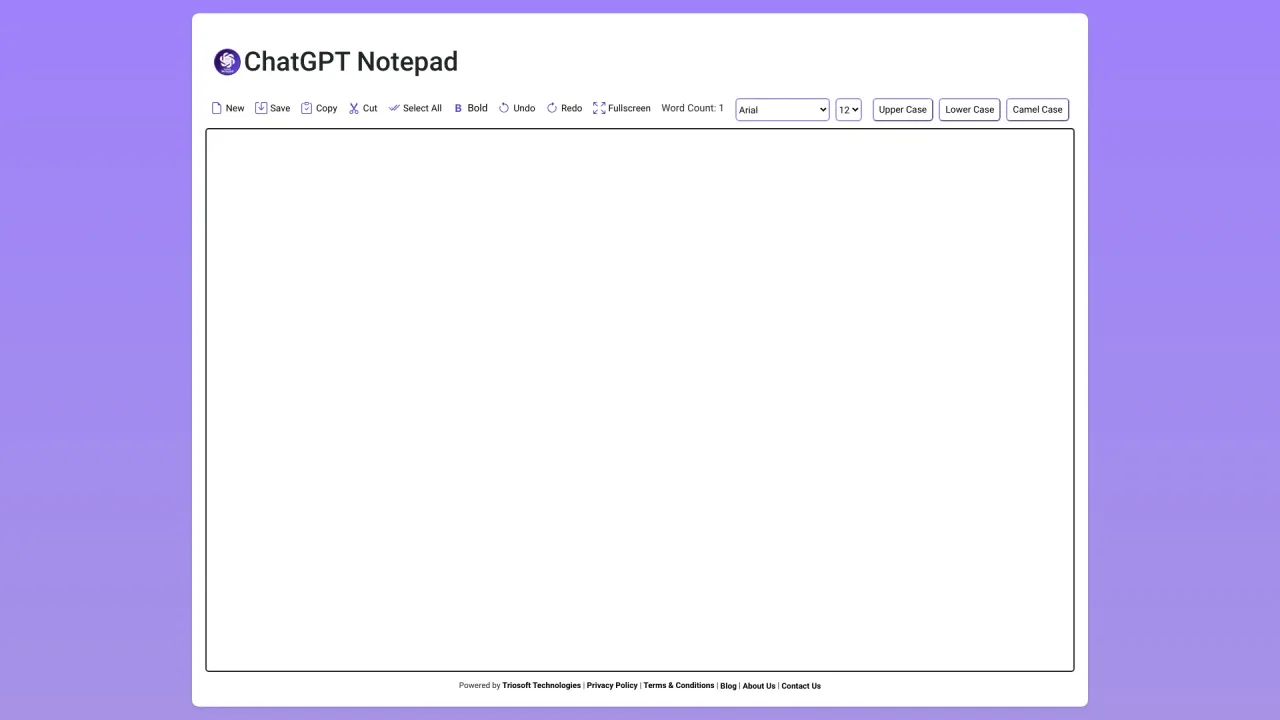
A distraction-free online notepad that cleans up text pasted from AI chatbots.
A distraction-free online notepad that cleans up text pasted from AI chatbots.