01
Apify公式
414.8万/月
豊富なマーケットプレイスを持つ堅牢なアクター型クラウドスクレイピングプラットフォームですが、企業向けプロキシインフラの直接制御は劣ります。
AI Web スクレイピング編集部スコア:4.6フリーミアム、料金は要問い合わせ+3.9%

フリーミアム、料金は要問い合わせ

機能と用途で選んだ、Bright Data の代替ツール 12 件。
| 順位 | ツールとキャッチコピー | 公式ドメイン | 月間訪問数 | 前月比成長率 |
|---|
| 料金モデル |
|---|
| 主要市場 |
|---|
| 評価 |
|---|
| 比較 |
|---|
| ● | Bright Data | brightdata.com | 80.28万 | -5.04万 (-5.9%) | 無料トライアル、有料 | アメリカ合衆国 | 4.6 | プロフィール |
| 1 | Apify | apify.com | 414.78万 | 15.68万 (+3.9%) | フリーミアム、料金は要問い合わせ | アメリカ合衆国 | 4.6 | 比較 |
| 2 | Firecrawl | firecrawl.dev | 182.82万 | -3.57万 (-1.9%) | フリーミアム、料金は要問い合わせ | アメリカ合衆国 | 4.7 | 比較 |
| 3 | Thor Data | thordata.com | 18.2万 | -6552 (-3.5%) | 無料トライアル、有料 | ポーランド | 4.3 | 比較 |
| 4 | Exa | exa.ai | 106.26万 | 15.28万 (+16.8%) | フリーミアム、料金は要問い合わせ | アメリカ合衆国 | 4.5 | 比較 |
| 5 | Jina AI | jina.ai | 28.08万 | -5.57万 (-16.5%) | フリーミアム、有料 | アメリカ合衆国 | 4.7 | 比較 |
| 6 | Browserless | browserless.io | 18.55万 | -4.98万 (-21.2%) | フリーミアム、有料、料金は要問い合わせ | アメリカ合衆国 | 4.4 | 比較 |
| 7 | Scrapingdog | scrapingdog.com | 8.97万 | -1.59万 (-15%) | 無料トライアル、有料 | インド | 4.3 | 比較 |
| 8 | WebScraping.AI | webscraping.ai | 1.49万 | -1978 (-11.7%) | フリーミアム、有料 | アメリカ合衆国 | 4.3 | 比較 |
| 9 | SmartProxy | smartproxy.org | 217 | -2.77万 (-99.2%) | 無料トライアル、有料 | スイス | 4.4 | 比較 |
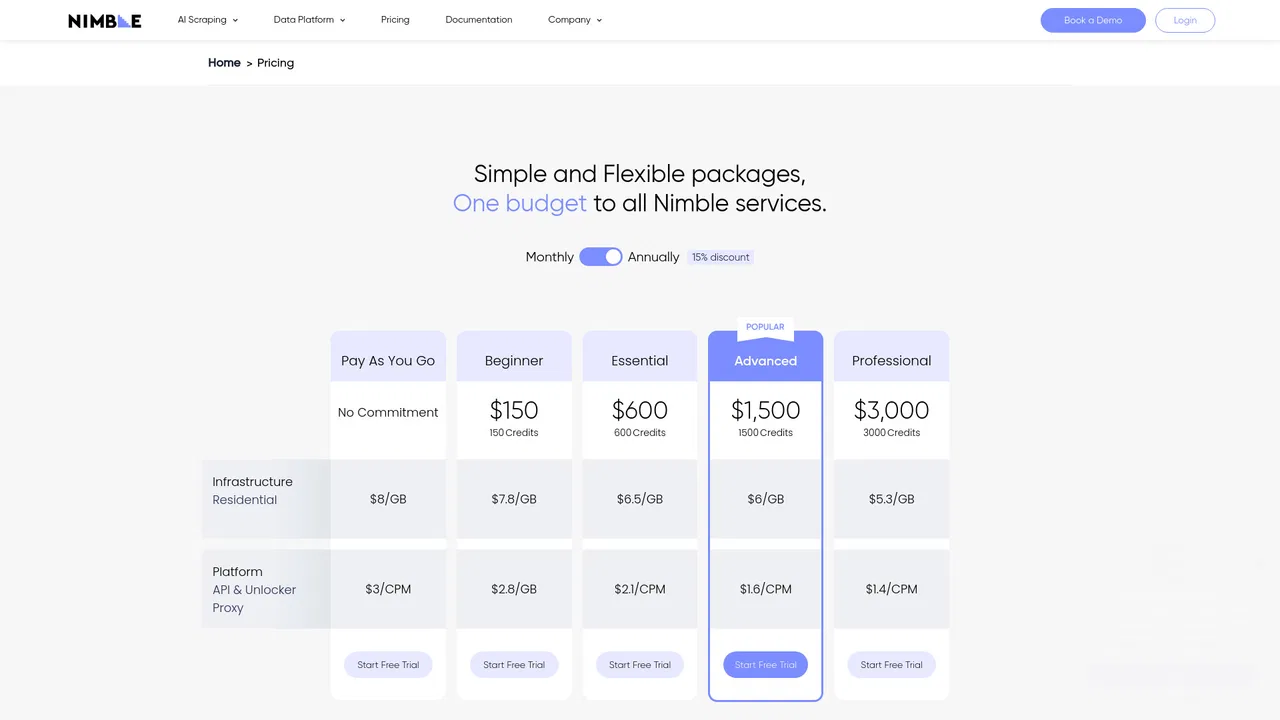
| 10 | Nimble API | nimbleapi.io | 0 | 0 (—) | 有料 | グローバル | 4.3 | 比較 |
| 11 | ScrapeGraphAI | scrapegraphai.com | 9.14万 | -3.15万 (-25.7%) | フリーミアム、有料、料金は要問い合わせ | アメリカ合衆国 | 4.2 | 比較 |
| 12 | TinyFish | tinyfish.ai | 112.5万 | 74.96万 (+199.7%) | フリーミアム、料金は要問い合わせ | アメリカ合衆国 | 4.4 | 比較 |
豊富なマーケットプレイスを持つ堅牢なアクター型クラウドスクレイピングプラットフォームですが、企業向けプロキシインフラの直接制御は劣ります。
無料・オープンソースウェブサイト全体をLLM向けクリーンなMarkdownに即座に変換しますが、住宅用プロキシIPの管理ツールはありません。

強力なグローバルプロキシやスクレイピングAPIを提供しますが、既存の自動化アクターのエコシステムは小さめです。
強力なグローバルプロキシやスクレイピングAPIを提供しますが、既存の自動化アクターのエコシステムは小さめです。

特化型ニューラルウェブ検索やAIエージェントのクロールに特化していますが、従来の生プロキシネットワークの制御機能はありません。

特化型優れたURL-Markdown変換とニューラル検索APIを提供しますが、プロキシIPインフラの管理機能はやや限定的です。

特化型自動化向けの拡張可能なヘッドレスブラウザ・クラウドインフラですが、住宅用プロキシプールやパッケージ済みのスクレイパーはありません。
特化型自動化向けの拡張可能なヘッドレスブラウザ・クラウドインフラですが、住宅用プロキシプールやパッケージ済みのスクレイパーはありません。

Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.

Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.
Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.

Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
無料・オープンソースOpen-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.
無料・オープンソースOpen-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.

特化型Provides live web search and agentic cloud browser automation, but less focused on raw proxy network management.