Nebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.
459 種類のワークフローで、アクセス推計・機能・代替製品を比較できます。
“NVIDIA GPUs”·93 件
最初からNebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.

Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.


Together AI is the AI Native Cloud — a full-stack platform for running, fine-tuning and training open-source models. It spans serverless inference APIs, dedicated endpoints, GPU clusters, post-training and storage, all backed by in-house systems research.

ハイパースケーラーより最大80%安い、オンデマンドのクラウドGPU

31社のクラウドGPU価格をライブ比較


分単位のインスタンスと秒単位のサンドボックスを備えた低コストなクラウドGPU。
セットアップ不要でクラウド上にネイティブComfyUIを起動、高速GPUとワンクリックのサーバーレスAPI
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
PyTorch Lightning の開発チームが作った AI クラウド


Runware is an AI inference platform that exposes an enormous model catalog — images, video, audio, LLMs and 3D — through a single API endpoint, alongside serverless GPU compute and reserved capacity running on modular data centers the company designs and operates itself. It is aimed at developers and product teams who want to ship generative features without managing infrastructure.
500以上の画像・動画・音声・LLMモデルを1つのOpenAI互換APIで

自分のGPUやMacで実際に動くローカルAIモデルを確認
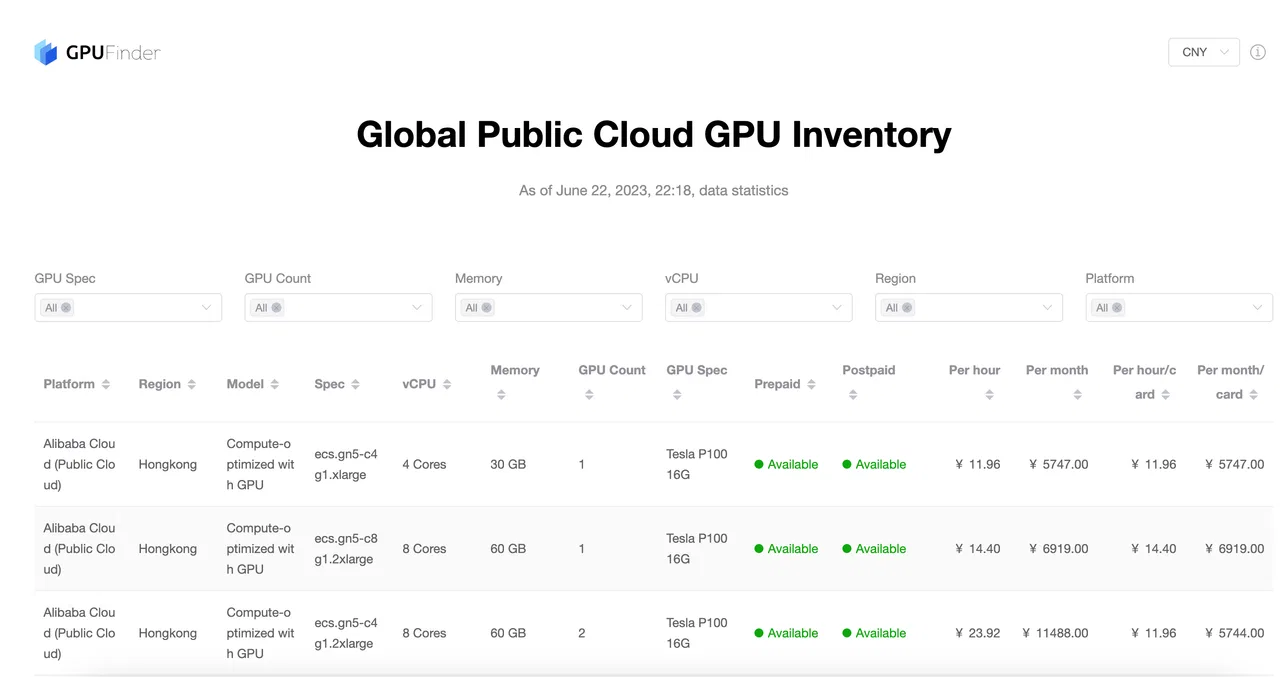
パブリッククラウドのGPUインスタンスのスペックと価格を1つの表で比較