01
Apify공식
414.8만/월
방대한 마켓플레이스를 갖춘 강력한 액터 기반 클라우드 스크레이핑 플랫폼이지만, 원시 기업용 프록시 인프라 제어는 상대적으로 부족합니다.
AI 웹 스크래핑에디터 평점: 4.6무료+유료, 가격 문의+3.9%

기능과 용도를 기준으로 고른 Bright Data 대안 도구 12개입니다.
| 순위 | 도구 및 소개 문구 | 공식 도메인 | 월간 방문 수 | 전월 대비 성장률 |
|---|
| 가격 모델 |
|---|
| 주요 시장 |
|---|
| 평점 |
|---|
| 비교 |
|---|
| ● | Bright Data | brightdata.com | 80.28만 | -5.04만 (-5.9%) | 무료 체험, 유료 | 미국 | 4.6 | 프로필 |
| 1 | Apify | apify.com | 414.78만 | 15.68만 (+3.9%) | 무료+유료, 가격 문의 | 미국 | 4.6 | 비교 |
| 2 | Firecrawl | firecrawl.dev | 182.82만 | -3.57만 (-1.9%) | 무료+유료, 가격 문의 | 미국 | 4.7 | 비교 |
| 3 | Thor Data | thordata.com | 18.2만 | -6.55천 (-3.5%) | 무료 체험, 유료 | 폴란드 | 4.3 | 비교 |
| 4 | Exa | exa.ai | 106.26만 | 15.28만 (+16.8%) | 무료+유료, 가격 문의 | 미국 | 4.5 | 비교 |
| 5 | Jina AI | jina.ai | 28.08만 | -5.57만 (-16.5%) | 무료+유료, 유료 | 미국 | 4.7 | 비교 |
| 6 | Browserless | browserless.io | 18.55만 | -4.98만 (-21.2%) | 무료+유료, 유료, 가격 문의 | 미국 | 4.4 | 비교 |
| 7 | Scrapingdog | scrapingdog.com | 8.97만 | -1.59만 (-15%) | 무료 체험, 유료 | 인도 | 4.3 | 비교 |
| 8 | WebScraping.AI | webscraping.ai | 1.49만 | -1.98천 (-11.7%) | 무료+유료, 유료 | 미국 | 4.3 | 비교 |
| 9 | SmartProxy | smartproxy.org | 217 | -2.77만 (-99.2%) | 무료 체험, 유료 | 스위스 | 4.4 | 비교 |
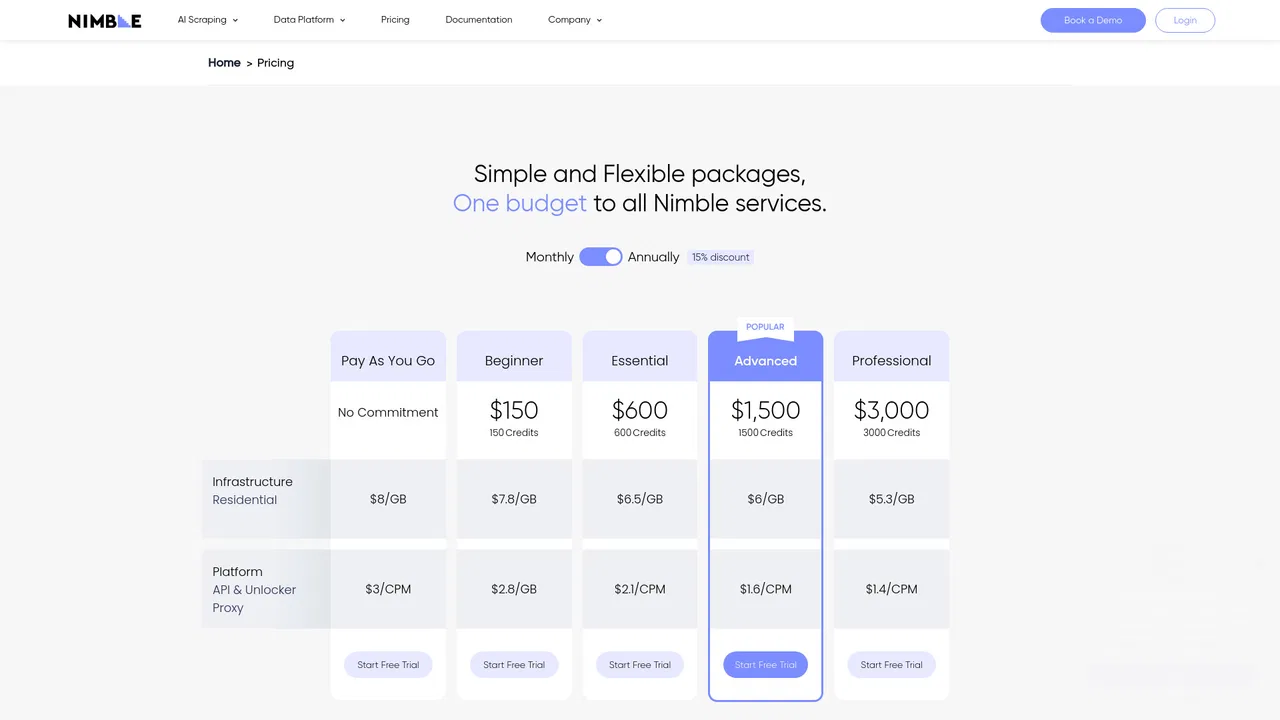
| 10 | Nimble API | nimbleapi.io | 0 | 0 (—) | 유료 | 글로벌 | 4.3 | 비교 |
| 11 | ScrapeGraphAI | scrapegraphai.com | 9.14만 | -3.15만 (-25.7%) | 무료+유료, 유료, 가격 문의 | 미국 | 4.2 | 비교 |
| 12 | TinyFish | tinyfish.ai | 112.5만 | 74.96만 (+199.7%) | 무료+유료, 가격 문의 | 미국 | 4.4 | 비교 |
방대한 마켓플레이스를 갖춘 강력한 액터 기반 클라우드 스크레이핑 플랫폼이지만, 원시 기업용 프록시 인프라 제어는 상대적으로 부족합니다.
무료 / 오픈소스웹사이트 전체를 LLM 친화적인 마크다운으로 즉시 변환하지만, 주거용 프록시 IP 관리 도구는 부족합니다.

강력한 글로벌 프록시 네트워크와 스크레이핑 API를 제공하지만, 사전 제작된 자동화 에코시스템은 상대적으로 작습니다.

특화 강점신경망 웹 검색과 AI 에이전트 크롤링에 최적화되어 있지만, 전통적인 로우 프록시 네트워크 제어 기능은 부족합니다.

특화 강점훌륭한 URL-투-마크다운 변환과 신경망 검색 API를 제공하지만, 프록시 IP 인프라 관리 기능은 상대적으로 적습니다.

특화 강점자동화를 위한 확장 가능한 헤드리스 브라우저 클라우드 인프라를 제공하지만, 기본 주거용 프록시 풀과 패키지형 스크레이퍼는 없습니다.
특화 강점자동화를 위한 확장 가능한 헤드리스 브라우저 클라우드 인프라를 제공하지만, 기본 주거용 프록시 풀과 패키지형 스크레이퍼는 없습니다.

Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.

Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.
Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.

Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
무료 / 오픈소스Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.
무료 / 오픈소스Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.

특화 강점Provides live web search and agentic cloud browser automation, but less focused on raw proxy network management.