9.1천/월
실제 워크로드 데이터로 MySQL, MariaDB, PostgreSQL을 튜닝하는 AI 데이터베이스 어드바이저
AI 코파일럿에디터 평점: 4.3무료 체험직접 유입 40%
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“Workload optimization” · 코딩 및 소프트웨어 개발·결과 112개
처음으로실제 워크로드 데이터로 MySQL, MariaDB, PostgreSQL을 튜닝하는 AI 데이터베이스 어드바이저

클라우드 규모 엔지니어링 팀을 위한 통합 옵저버빌리티·보안·인시던트 대응 플랫폼

Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.



지연 시간 기반 요금제의 고처리량 오픈 웨이트 추론

복구 가능한 컨텍스트 압축과 스마트 모델 라우팅으로 AI 에이전트 토큰 비용 절감

Runable is a general-purpose AI agent for building, running and growing a business. Describe what you need and it produces websites, slide decks, reports, documents, images and videos, then connects to the tools you already use so the work keeps moving.
Runable is a general-purpose AI agent for building, running and growing a business. Describe what you need and it produces websites, slide decks, reports, documents, images and videos, then connects to the tools you already use so the work keeps moving.

QwenWork is an all-in-one AI productivity platform that goes beyond chat. Describe an outcome, and its agent plans the task, works with your files and tools, and delivers a finished document, slide deck, web page, image or video.
오픈웨이트 LLM 배포를 위한 VRAM·처리량·GPU 비용 계산기와 강의 플랫폼
오픈웨이트 LLM 배포를 위한 VRAM·처리량·GPU 비용 계산기와 강의 플랫폼

Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.
Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.

학습과 추론을 위한 프라이빗 AI 클라우드
하이퍼스케일러보다 최대 80% 저렴한 온디맨드 클라우드 GPU
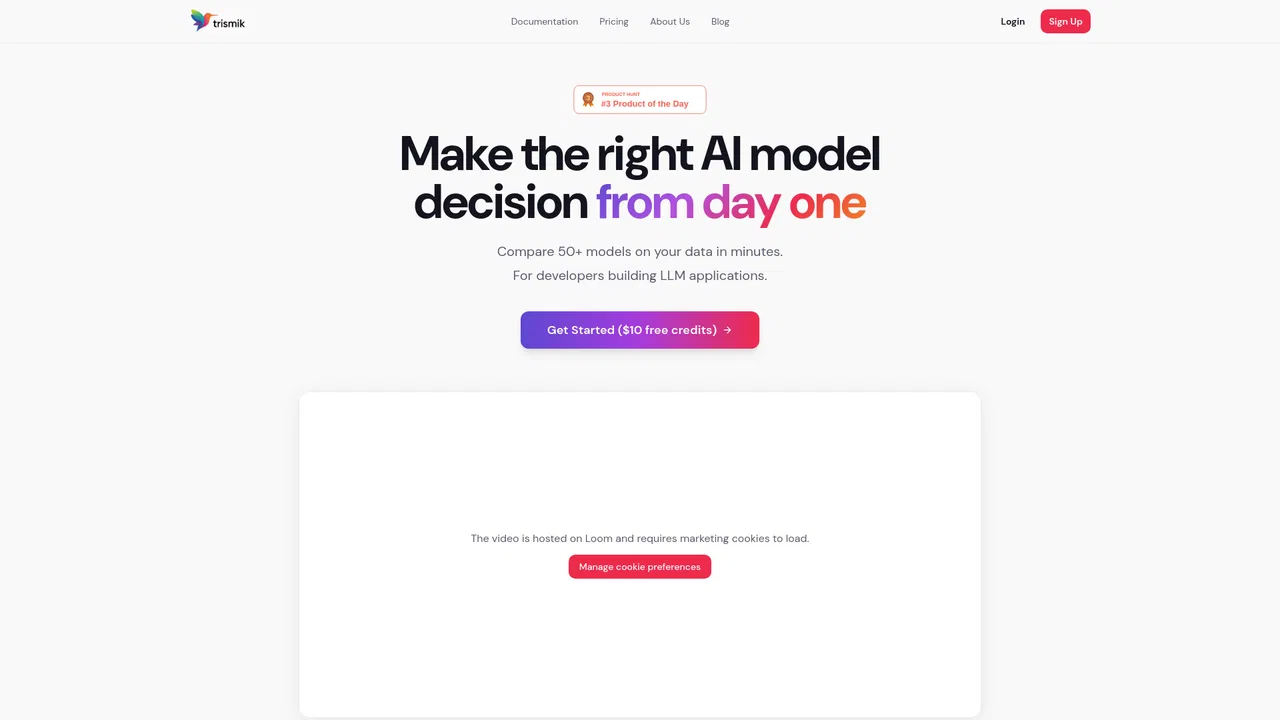
QuickCompare by Trismik is an AI model comparison layer that runs your own workloads against candidate models and names the differences before you switch. Cut inference costs with safe model swaps, de-risk migrations, and decide model choices with evidence from your real traffic rather than generic leaderboards.
QuickCompare by Trismik is an AI model comparison layer that runs your own workloads against candidate models and names the differences before you switch. Cut inference costs with safe model swaps, de-risk migrations, and decide model choices with evidence from your real traffic rather than generic leaderboards.