01
HigressOpen Source
13.3K/mo
Free / Open-sourceOpen-source AI gateway for LLM APIs, agents and MCP servers
AI APIEditorial score: 4.6Contact for Pricing39% direct
Open-source distributed LLM inference orchestration for your own fleet
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
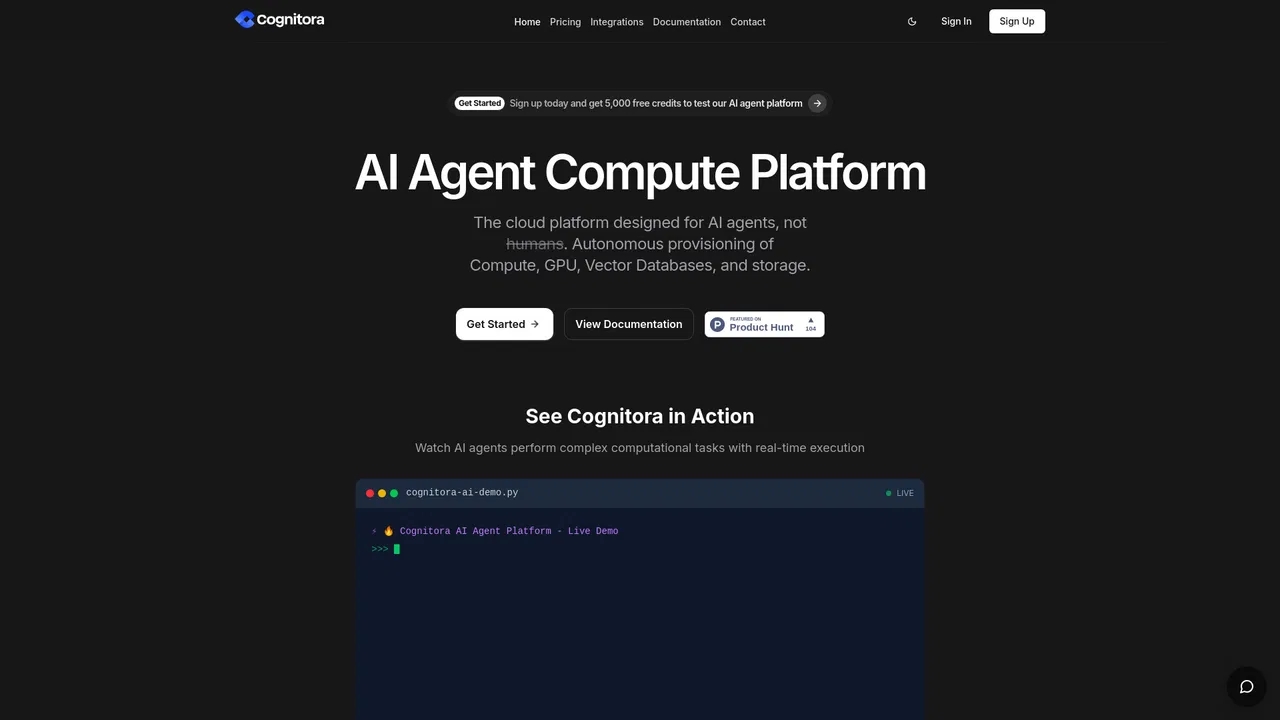
According to OpenAITools.app telemetry verified on 2026-11-11, Cognitora (cognitora.dev) is an AI platform indexed under AI Agent generating 0 monthly visits with a month-over-month traffic delta of +0 (0.0%). Its primary geographic market is Global (— traffic share), and it operates on a Open Source pricing model. Top competing alternatives by monthly volume include Higress (13.32K visits/mo), FlexAI (44.31K visits/mo), RunPod (2.88M visits/mo).
Routing requests by prompt prefix cache hit is pure genius; our GPU nodes finally stopped wasting cycles prefilling duplicate context.
Static binaries and a single curl command got our vLLM cluster unified in under ten minutes.
Solid performance, though Kubernetes integration docs could use more real-world examples.
Lightning fast.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Routes each request to the node whose cache holds the longest matching prompt prefix, using longest-prefix overlap of BLAKE3 sequence digests to avoid repeated prefill work.
One OpenAI-compatible API in front of vLLM, SGLang, llama.cpp, Apple MLX and a TRT-LLM spawn driver, so you can mix engines inside a single cluster.
Runs prefill and decode on separate replica pools with KV handoff through NixlConnector, letting each phase use hardware suited to it.
Folds Redfish and NVML power readings into routing scores, applies soft per-node watt caps, and drains hot nodes automatically to cut energy per token.
Deploys as six static binaries under systemd without Kubernetes, or with an optional kube-rs operator exposing InferenceCluster, ModelPool and RoutingPolicy CRDs.
Cognitora is an open-source orchestration layer for distributed large language model inference, written in Rust. Rather than shipping a single inference engine, it joins the engines you already operate — vLLM, SGLang, llama.cpp, Apple MLX, a TRT-LLM spawn driver and its own preview cgn-infer engine — into one cluster behind a single OpenAI-compatible gateway. You can deploy it instead of an orchestrator such as NVIDIA Dynamo, and the project positions itself as supporting more engines, running on bare metal without Kubernetes, factoring power consumption into scheduling and avoiding a Python control plane.
Its core innovation is KV-aware routing. The router scores nodes by the longest-prefix overlap of sequence-chained BLAKE3 digests, using cache claims that agents report in heartbeats. In real llama.cpp runs the router reportedly added 0.9–2.0 ms at p50. Beyond routing, the platform splits prefill from decode across separate pools (handing KV cache off through NixlConnector), maintains a multi-tier RAM/SSD KV cache with cross-node QUIC fetch, and offers pluggable offload backends including nixl, lmcache, hicache and kvbm.
The stack is modular: cgn-router for routing, cgn-agent to supervise engines on each node, cgn-kvcached for tiered caching, cgn-metrics for Prometheus plus Redfish/NVML power telemetry, cgn-ctl as an admin CLI, an optional Kubernetes operator, and a preview native engine. Energy-aware scheduling drains hot nodes, a closed-loop autoscaler reacts to power readings, and gossip-based discovery removes the need for etcd. Security options include optional mTLS, SHA-256 checksummed releases and OIDC or scoped API-key auth. The project ships six static binaries for systemd installs, Helm charts for Kubernetes, and a single-file HTML cluster dashboard that visualises throughput, latency percentiles, KV utilisation and joules per token without Grafana.
Put a single OpenAI-compatible endpoint in front of vLLM, llama.cpp and MLX nodes so applications stop caring which engine serves a model.
Use KV-aware routing and multi-tier caching to stop re-prefilling the same prompts across nodes, improving throughput on existing hardware.
Start on a few DGX Sparks, AMD boxes or Mac Studios with systemd and static binaries, then add QUIC federation when you outgrow one rack.
Apply power-aware admission and autoscaling so busy nodes shed traffic and the fleet runs closer to its efficiency sweet spot.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Cognitora | 0 | — | — | Open Source | Current |
| 1 | Higress | 13.32K | -17.9% | 39% direct | Contact for Pricing | vs Higress |
| 2 | FlexAI | 44.31K | +17.9% | 37% direct | Freemium, Paid, Contact for Pricing | vs FlexAI |
| 3 | RunPod | 2.88M | +5.9% | 57% direct | Paid | vs RunPod |
| 4 | Salad | 713.52K | +10.4% | 62% direct | Free Trial, Paid, Contact for Pricing | vs Salad |
| 5 | boat | 66.87K | +520.8% | 56% direct | Free Trial, Paid | vs boat |
| 6 | Browser Use | 1.21M | +41.1% | 52% direct | Freemium, Paid, Contact for Pricing | vs Browser Use |
Free / Open-sourceOpen-source AI gateway for LLM APIs, agents and MCP servers
Free / Open-sourceBuild, run and scale AI, from open models to governed agents
The AI developer cloud for GPU pods, serverless inference and clustering

Free / Open-sourceDistributed GPU cloud that orchestrates the world's idle consumer GPUs
Free / Open-sourceDistributed GPU cloud that orchestrates the world's idle consumer GPUs

Free / Open-sourcePersistent Ubuntu cloud VMs built for AI agent factories
Free / Open-sourceBrowser agents and stealth cloud browsers for real web tasks
Free / Open-sourceBrowser agents and stealth cloud browsers for real web tasks
Free / Open-sourceRun and scale durable AI agents on your own infrastructure
Free / Open-sourceSelf-hosted cloud development environments and AI coding agents for enterprise teams

Free / Open-sourceTogether AI is the AI Native Cloud — a full-stack platform for running, fine-tuning and training open-source models. It spans serverless inference APIs, dedicated endpoints, GPU clusters, post-training and storage, all backed by in-house systems research.
Free / Open-sourceTogether AI is the AI Native Cloud — a full-stack platform for running, fine-tuning and training open-source models. It spans serverless inference APIs, dedicated endpoints, GPU clusters, post-training and storage, all backed by in-house systems research.
Free / Open-sourceServerless cloud infrastructure for AI and data workloads
Free / Open-sourceServerless cloud infrastructure for AI and data workloads

Free / Open-sourceAgent-native cloud infrastructure that lets coding agents run the whole backend stack
An AI-native cloud built from silicon to API for training, tuning, and serving models
An AI-native cloud built from silicon to API for training, tuning, and serving models


