01
Arize AIOfficial
249K/mo
Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI
Large Language Models (LLMs)Editorial score: 4.6Paid, Contact for Pricing+3.2%


Observe, evaluate and monitor AI agents in production
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026

This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, honeyhive.ai (honeyhive.ai) is an AI platform indexed under AI Developer Tools generating 8.84K monthly visits with a month-over-month traffic delta of -9.75K (-52.5%). Its primary geographic market is United States (95.6% traffic share), and it operates on a Freemium, Contact for Pricing pricing model. Top competing alternatives by monthly volume include Arize AI (249.03K visits/mo), Maxim AI (121.35K visits/mo), Future AGI (121.74K visits/mo).
Saved our team dozens of hours debugging flaky multi-step agents.
Trace visualization is cleaner than LangSmith.
Evaluation datasets and prompt management work smoothly.
Inspect every prompt, tool call, retrieval step, output and handoff, replay runs in order, and debug agents whose trajectories span hours or days.
Score sampled production sessions with LLM judges, code checks, or human review and connect quality scores to real user outcomes.
Track quality, cost, latency, usage and outcomes over time, set thresholds on any score, and get alerted by email or webhook before users notice drift.
Compare agent versions on the same dataset, build regression suites from real traces, and route flagged sessions to expert annotation queues.
Version, test and deploy prompts through the same lifecycle as the rest of your agent stack, keeping changes reviewable.
HoneyHive is an observability and evaluation platform built for teams running agents and LLM applications in production. Rather than treating a model call as a black box, it records full traces — prompts, retrievals, tool calls, guardrail checks, outputs and sub-agent handoffs — so engineers can replay exactly what happened and find the step where behavior went wrong, even for agent trajectories that run for hours or across many retries and loops.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | honeyhive.ai | 8.84K | -52.5% | 79% direct | Freemium, Contact for Pricing | Current |
| 1 | Arize AI | 249.03K | +3.2% | 43% direct | Paid, Contact for Pricing | vs Arize AI |
Pricing gets steep once production volume scales.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
The evaluation layer closes the loop between observation and improvement. Live production traffic is sampled and scored by LLM judges, custom code evaluators, or human reviewers, so quality is measured against real users instead of a static suite. Monitoring watches those scores alongside cost, latency and usage; thresholds and drift detection trigger alerts by email or webhook when something degrades. Offline experiments compare agent versions on shared datasets, and production failures can be turned into regression suites so the same problem never ships twice.
The platform also handles the human side of evaluation with annotation queues that route low-confidence or flagged traces to domain experts, whose judgments become reusable evaluation data. Prompt management versions, tests and deploys prompts through the same workflow. HoneyHive offers a free tier to get started with additional plans for scaling teams and an Enterprise tier for organizations with heavier security and scale requirements.
Replay failed production runs step by step to find whether the model, a retrieval step, or a tool call caused the bad answer.
Score sampled live traffic on groundedness, safety and task completion, then alert when quality drifts below a threshold.
Compare a new agent or prompt version against the previous one on the same dataset and inspect what improved and what regressed.
Route low-confidence or sensitive responses to specialists whose judgments become labeled data for future evaluations.
Freemium: a free tier is available to start, with paid plans for growing teams and an Enterprise tier (contact for pricing) for larger deployments.
| 2 | Maxim AI | 121.35K | +10% | 32% direct | Contact for Pricing, Free Open Source | vs Maxim AI |
| 3 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
| 4 | Confident AI | 83.4K | -3.3% | 35% direct | Freemium, Paid, Contact for Pricing | vs Confident AI |
| 5 | PromptLayer | 85.9K | -4.6% | 16% direct | Free Trial, Contact for Pricing | vs PromptLayer |
| 6 | Datadog | 5.18M | -4.8% | 53% direct | Freemium, Free Trial, Paid, Contact for Pricing, Free | vs Datadog |
Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI

Free / Open-sourceEvaluate, monitor, and govern your AI applications in production

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
 #3

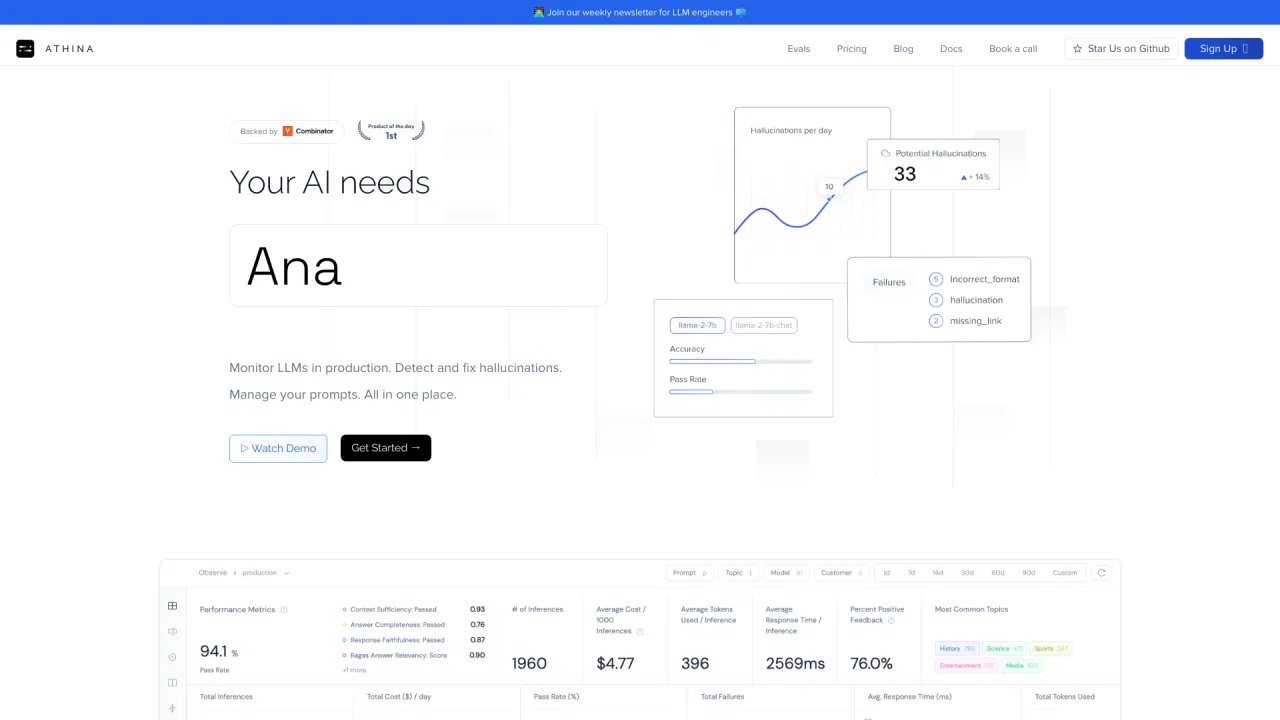
Standardize LLM evaluation, observability, and red teaming across your whole org

SpecialistThe collaboration layer for AI engineering teams
SpecialistUnified observability, security and incident response for cloud-scale engineering teams
Find and fix problems in your AI agents before users do

SpecialistTrack, evaluate, and ship AI models and agents in one connected environment.

Full-stack observability with an AI SRE agent that fixes issues
AI governance, testing, and observability for regulated enterprises

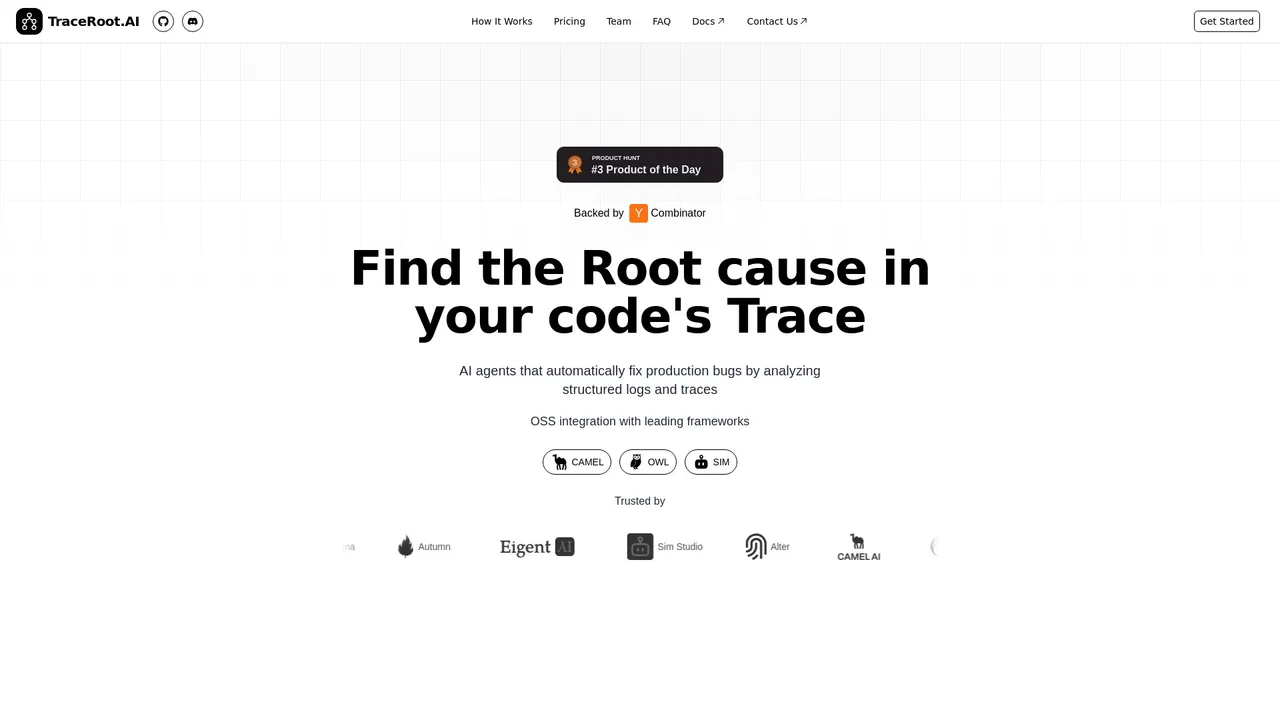
Free / Open-sourceOpen-source observability that turns AI agent production failures into tested fixes

Collaborative platform to build, test, and monitor LLM features
Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI
Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Standardize LLM evaluation, observability, and red teaming across your whole org
SpecialistThe collaboration layer for AI engineering teams
SpecialistUnified observability, security and incident response for cloud-scale engineering teams
Find and fix problems in your AI agents before users do
SpecialistTrack, evaluate, and ship AI models and agents in one connected environment.
Full-stack observability with an AI SRE agent that fixes issues
AI governance, testing, and observability for regulated enterprises
Free / Open-sourceOpen-source observability that turns AI agent production failures into tested fixes
Collaborative platform to build, test, and monitor LLM features