01
6.6M/mo
All-in-one AI studio for video, image, and agent-driven content creation
AI Video GeneratorEditorial score: 4.1Freemium46% direct

6.6M/mo
All-in-one AI studio for video, image, and agent-driven content creation
Freemium
Independent demo and documentation hub for DeepSeek's Janus-Pro multimodal models
Estimated monthly website visits
Janus Pro at janusai.pro is an unofficial third-party wrapper site offering browser-based demos and documentation for DeepSeek's open-source multimodal models.
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Janus Pro (janusai.pro) is an AI platform indexed under AI Image Generator generating 2.24K monthly visits with a month-over-month traffic delta of -8.68K (-79.5%). Its primary geographic market is United States (92.4% traffic share), and it operates on a Free pricing model. Top competing alternatives by monthly volume include Pollo AI (6.64M visits/mo), Creen AI (1.89M visits/mo), OpenGen (1.14M visits/mo).
Just an unofficial wrapper trying to milk DeepSeek's SEO traffic.
Demo is painfully slow compared to running the 7B model locally.
Not official at all, just ads and web UI wrappers.
Total SEO mirror trap.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
A single autoregressive Transformer handles both multimodal understanding (describe, reason about, and answer questions on images) and text-to-image generation, instead of splitting the work across two separate systems.
Separate encoding pathways for understanding and generation remove the tension between the two tasks, improving flexibility and preventing the perception side from degrading generation quality.
Janus-1.3B, JanusFlow-1.3B, Janus-Pro-1B and Janus-Pro-7B weights are published on Hugging Face with code on GitHub, and the license allows commercial usage under its terms.
The site provides no-login playgrounds for Janus-Pro-7B text-to-image generation and multimodal understanding, plus a WebGPU build of Janus-Pro-1B that runs entirely on your own device.
Links to the official paper, model cards, and community tooling such as ComfyUI nodes make it easy to move from trying the demo to running the model in your own pipeline.
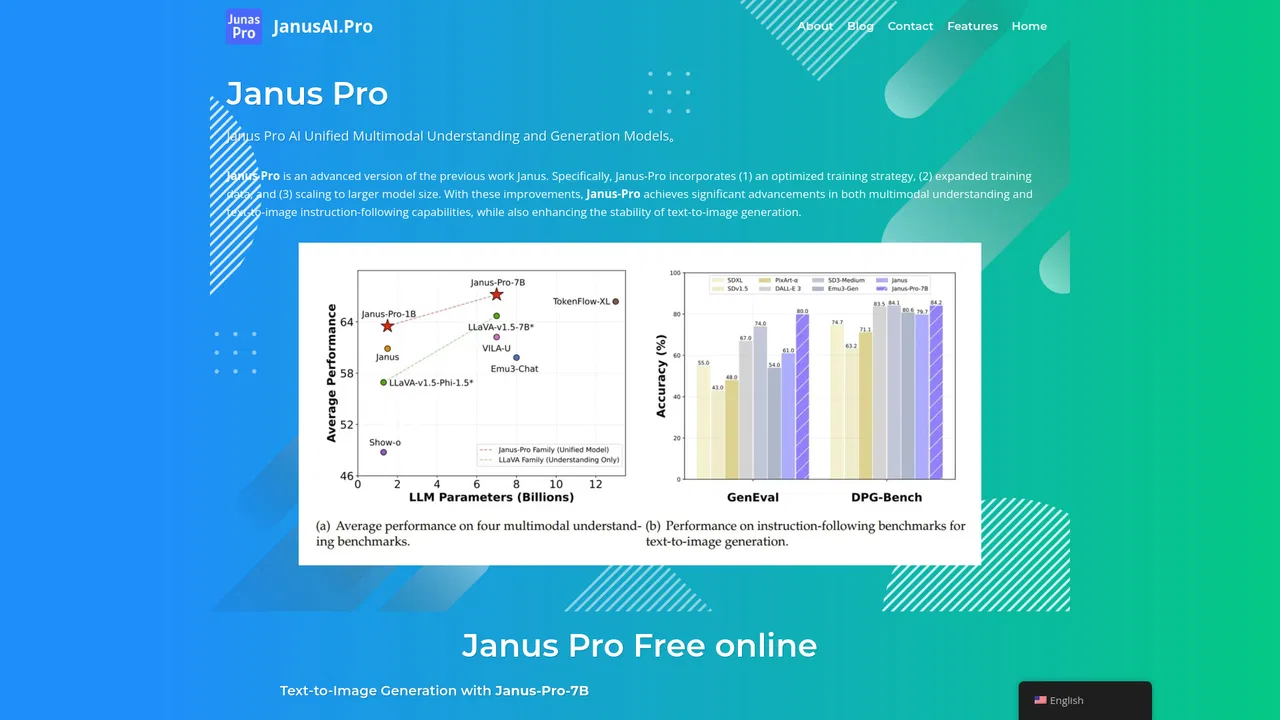
Janus Pro is a unified multimodal framework from DeepSeek that handles both image understanding and image generation inside a single autoregressive Transformer. Rather than forcing one visual encoder to serve two contradictory jobs, Janus decouples visual encoding into separate pathways — one tuned for perception, one for generation — while keeping a single shared transformer body. Janus-Pro, the successor to the original Janus, adds an optimized training strategy, substantially more training data, and larger model sizes, which together improve both instruction-following for text-to-image work and the stability of generated images.
This site, janusai.pro, is an independent resource hub rather than an official DeepSeek property. It collects model cards, paper links, benchmark notes, and download pointers for the Janus family — Janus-1.3B, JanusFlow-1.3B, Janus-Pro-1B and Janus-Pro-7B — and hosts lightweight in-browser demos, including a WebGPU build of the 1B model that runs locally in a modern browser without any sign-up.
The models themselves are released openly: weights are published on Hugging Face with code on GitHub, and commercial use is permitted under the stated license terms. That openness is what made Janus-Pro notable — in DeepSeek's published benchmarks the 7B model scored 0.80 on GenEval text-to-image instruction following, ahead of much larger closed systems. Because generation runs at 384x384, output is fast and cheap but noticeably softer on fine detail than diffusion-based image models.
Compare Janus-Pro against diffusion models and closed APIs for instruction-following image generation and image question answering, using published weights you can run on your own hardware.
Use one model for captioning, visual question answering, and prompt-driven image creation, which simplifies architecture when both directions are needed in the same product.
Poke at the browser demos to see how a unified multimodal model behaves before investing time in local setup or GPU capacity.
Connect the community nodes to wire Janus-Pro into automated image generation graphs alongside other checkpoints and post-processing.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Janus Pro | 2.24K | -79.5% | 39% direct | Free | Current |
| 1 | Pollo AI | 6.64M | -9.6% | 46% direct | Freemium | vs Pollo AI |
| 2 | Creen AI | 1.89M | -5.8% | 47% direct | Freemium, Free | vs Creen AI |
| 3 | OpenGen | 1.14M | +802.8% | 6% direct | Contact for Pricing | vs OpenGen |
| 4 | Civitai | 6.96M | +12.8% | 54% direct | Freemium | vs Civitai |
| 5 | JXP AI Video Generator | 193.18K | -9.5% | 42% direct | Free Trial, Paid | vs JXP AI Video Generator |
| 6 | Runway | 7.5M | +16.9% | 43% direct | Freemium, Paid, Contact for Pricing | vs Runway |
All-in-one AI studio for video, image, and agent-driven content creation
All-in-one AI studio for video, image, and agent-driven content creation

Free no-login AI generator for video, image, and audio in one browser tab
Free no-login AI generator for video, image, and audio in one browser tab

One workspace for the leading AI video and image models
One workspace for the leading AI video and image models
Free / Open-sourceDiscover, download and generate with open-source AI models for image, video and 3D.
One studio for text-to-video, image-to-video, images and lip-sync across many top AI models
One studio for text-to-video, image-to-video, images and lip-sync across many top AI models

Generative video, image, and audio tools built on frontier AI research
Alibaba's Wan model for AI video and image creation
One multimodal AI model for cinematic text-to-video and image-to-video creation
One multimodal AI model for cinematic text-to-video and image-to-video creation

Cloud ComfyUI platform to run workflows and build AI apps
Free / Open-sourceOpen-source model and dataset hub with one-click online demos
Free / Open-sourceOpen-source model and dataset hub with one-click online demos
AI creative agents for text-to-video, image-to-video, and visual production
AI creative agents for text-to-video, image-to-video, and visual production

Text-to-video, image-to-video and AI image art in one creative studio
Text-to-video, image-to-video and AI image art in one creative studio


