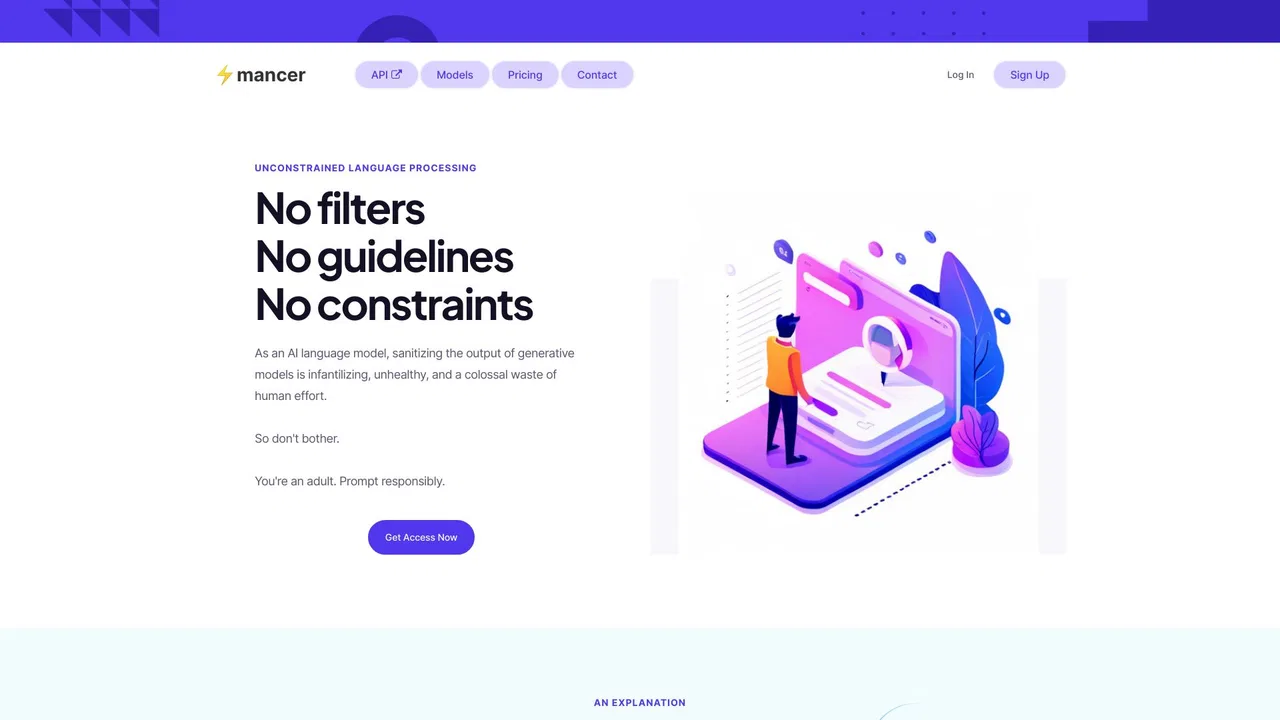
Unrestricted, OpenAI-compatible LLM API governed by your own policies

Unfiltered large language model inference, with a free tier and API access
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026

This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, mancer (mancer.tech) is an AI platform indexed under Large Language Models (LLMs) generating 1.71K monthly visits with a month-over-month traffic delta of -7.19K (-80.8%). Its primary geographic market is Brazil (93.9% traffic share), and it operates on a Freemium pricing model. Top competing alternatives by monthly volume include Abliteration.ai (522.77K visits/mo), OpenRouter (19.94M visits/mo), Groq (3.99M visits/mo).
Zero content filters and drops straight into SillyTavern with the OpenAI API format.
Server load spikes can cause latency during peak evening hours.
Absolute freedom for creative roleplay without getting blocked by nanny guards.
Great model variety and fair pricing for raw inference.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
No content filtering and no behavioural guidelines are applied on the provider side. mancer runs the models and returns whatever they generate, leaving the choice of what to prompt to the user.
Access a capable model at no cost for everyday use, and move to paid models when you need faster response times, larger parameter sizes or stronger general ability.
An OpenAI-compatible text-generation API means chat front-ends such as SillyTavern and other OpenAI-style clients can point straight at mancer without bespoke integration work.
Sign-up, model selection and usage are a short, three-step flow designed so you can get a key and start prompting quickly rather than working through a heavy onboarding process.
A single account gives you one endpoint and one key for every model on offer, so switching between a free model and a paid one is a configuration change rather than a new integration.
mancer is built around a single, blunt premise: it is a large language model inference service that does not filter what the models say. The operator runs models on high-end machines and lets you send any prompt you want, with the stated position that sanitising model output is not the provider's job. Users pick a model, prompt it, and get the raw result back.
Onboarding is deliberately light. You create an account, choose from the available models, and start prompting. A capable model is available under a free allowance, while paid tiers unlock harder, faster or larger models for heavier users. The provider frames this as a straightforward either/or: use the free model as much as you like, or pay for more capability.
For integrations, mancer exposes an OpenAI-compatible text-generation API. That compatibility is the practical draw for people already running a chat front-end, since tools that speak the OpenAI text-generation format — SillyTavern being the example the provider calls out — can be pointed at mancer's endpoint with minimal configuration. It is an independent, personality-forward service rather than an enterprise platform, so treat it as a good fit for experimentation, roleplay front-ends and personal projects.
Point SillyTavern or another OpenAI-style chat client at mancer's endpoint and use a free model without managing local hardware or GPU capacity.
Use the unfiltered models for prompts that a moderated commercial API would refuse, in contexts where you are comfortable taking responsibility for the output.
Because the endpoint is OpenAI-compatible, you can swap it in as an alternative provider behind an existing abstraction layer, useful for testing how different models handle the same prompt set.
Community and hobby projects that need a low-cost or free inference endpoint for a standard model can build on the free tier and upgrade individual models only when throughput matters.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | mancer | 1.71K | -80.8% | 43% direct | Freemium | Current |
| 1 | Abliteration.ai | 522.77K | +23.9% | 56% direct | Freemium, Paid, Contact for Pricing | vs Abliteration.ai |
| 2 | OpenRouter | 19.94M | -6.2% | 60% direct | Paid | vs OpenRouter |
| 3 | Groq | 3.99M | +10% | 43% direct | Paid | vs Groq |
| 4 | OpenAI Platform | 234.68M | -9.6% | 45% direct | Paid | vs OpenAI Platform |
| 5 | OrcaRouter | 975.3K | -5.2% | 26% direct | Freemium | vs OrcaRouter |
| 6 | RightNow Inference (RunInfra) | 18.11K | -22.6% | 43% direct | Free Trial, Paid, Contact for Pricing | vs RightNow Inference (RunInfra) |

Unrestricted, OpenAI-compatible LLM API governed by your own policies
One API key for hundreds of AI models from every major provider

Ultra-fast AI inference on the LPU and LPX platform

Enterprise developer platform and API for deploying GPT-6 Astra, Sol, Luna, and realtime multimodal agents.
One OpenAI-compatible gateway for adaptive LLM routing, guardrails, and spend control

Open models served fast, with warm-cache routing for agents
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.

Zhipu AI's open platform for GLM large models, multimodal APIs, and agent building
One OpenAI-compatible API for 500+ image, video, audio, and LLM models

Low-cost serverless inference APIs for 200+ open models

Free / Open-sourceServerless, decentralized inference for open-source AI models

Free / Open-sourceAlibaba Cloud's 4th-generation multimodal AI assistant and foundation model lineup (Qwen4-Max, Qwen4-Plus, Qwen4-Flash & open-weight Qwen4-27B) with 1M context.