01
APIParkOpen Source
30.7K/mo
Free / Open-sourceOpen-source AI gateway and developer portal for APIs and LLMs
AI APIEditorial score: 4.4Freemium, Contact for Pricing+13.4%
Meter your AI product without building the plumbing.
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Meteron AI (meteron.ai) is an AI platform indexed under AI API generating 841 monthly visits with a month-over-month traffic delta of -2.8K (-76.9%). Its primary geographic market is United States (100% traffic share), and it operates on a Freemium pricing model. Top competing alternatives by monthly volume include APIPark (30.74K visits/mo), DeepSeek (372.76M visits/mo), Emergent (5.79M visits/mo).
Saved us weeks of writing custom Redis queueing and metering code.
Token-based metering out of the box is a huge timesaver.
API documentation can be sparse in places.
Handled traffic spikes without breaking a sweat.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
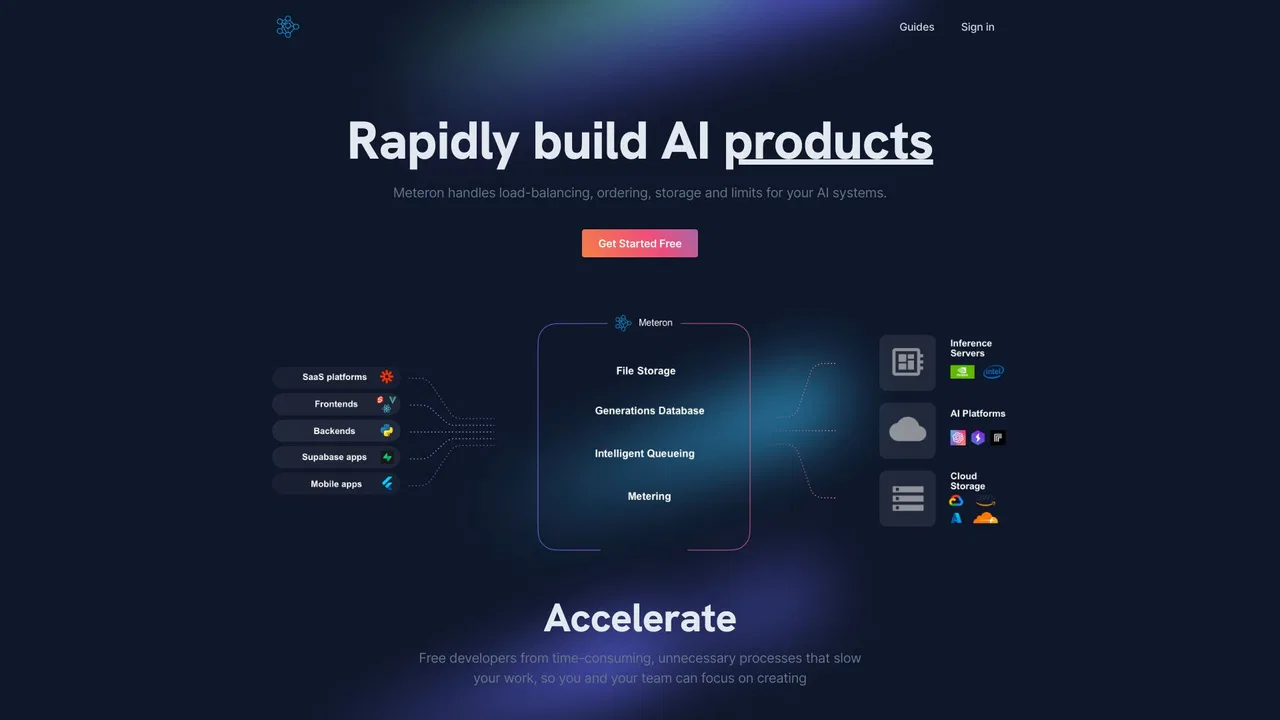
Charge end users per request, per token, or both, with per-user daily and monthly limits enforced through a simple user header.
Meteron queues and load-balances requests across your inference servers and lets you add capacity whenever demand spikes.
Generated images and assets are uploaded to cloud storage across all major providers, with custom S3, GCS or Azure buckets on higher tiers.
Point Meteron at any LLM or image model — Llama, Mistral, Stable Diffusion or DALL-E — and let it handle routing and quotas.
Concurrency control, priority classes and automatic retries keep latency predictable when usage surges.
Meteron AI is infrastructure for teams building generative AI products. Rather than assembling metering, queueing, storage and load balancing themselves, developers route their model requests through Meteron's API, which enforces quotas, absorbs demand spikes and hands back results. It is model-agnostic: the same pipeline can front Llama, Mistral, Stable Diffusion, DALL-E or any other text and image endpoint you run.
The core problem it solves is commercial rather than creative. Once an AI app has paying users, someone has to count requests or tokens per user, stop free users from exhausting GPU capacity, keep VIP traffic fast and store the generated images somewhere. Meteron bundles those jobs into one metering mechanism: you declare per-user daily and monthly limits on a cluster and pass a user identifier with each request, and the platform enforces the cap while queueing and load balancing behind the scenes.
Meteron is positioned as a low-code service, though it assumes fluency with HTTP and API calls rather than a graphical drag-and-drop workflow. Integration works with any HTTP client, and dynamic server registration is designed for elastic GPU hosts such as Lightning AI and RunPod. Pricing runs from a free tier through Professional and Business plans, with on-premises licences for teams that want to run the stack inside their own cloud. The product is operated by AppScension Ltd.
A solo developer ships an image generator on Stable Diffusion XL, uses Meteron to store outputs and meter each user, and sets a free daily quota without writing billing code.
A team runs multi-tenant room-redesign tools on ControlNet behind elastic GPU hosts, using Meteron for metering, queueing and asset storage while adding servers dynamically.
An ML engineer fronts self-hosted Llama or Mistral endpoints with Meteron so VIP and free users receive different queue priorities and per-token billing.
A company with strict data rules deploys an on-prem Meteron licence inside its own cloud to keep generations and usage data in-house.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Meteron AI | 841 | -76.9% | 39% direct | Freemium | Current |
| 1 | APIPark | 30.74K | +13.4% | 40% direct | Freemium, Contact for Pricing | vs APIPark |
| 2 | DeepSeek | 372.76M | +4.3% | 78% direct | Freemium | vs DeepSeek |
| 3 | Emergent | 5.79M | +5% | 29% direct | Freemium | vs Emergent |
| 4 | Base44 | 14.04M | +0.5% | 56% direct | Freemium, Paid, Contact for Pricing | vs Base44 |
| 5 | BuildShip | 37.11K | -20% | 40% direct | Freemium | vs BuildShip |
| 6 | Chatbot App | 2.17M | -9.7% | 23% direct | Freemium | vs Chatbot App |
Free / Open-sourceOpen-source AI gateway and developer portal for APIs and LLMs
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
Free / Open-sourceHigh-efficiency open-weight and hosted reasoning AI powered by DeepSeek-V4 and R1 at ultra-low token costs.
Describe an app in chat and ship it

Build working apps, websites, and AI agents by describing them
Build working apps, websites, and AI agents by describing them

AI-powered visual workflow builder for backend APIs and automations
AI-powered visual workflow builder for backend APIs and automations
Chat with 30+ leading AI models in one clean, fast workspace
Chat with 30+ leading AI models in one clean, fast workspace

Build, test and deploy AI apps and agents without writing a line of code
Build, test and deploy AI apps and agents without writing a line of code

One real-time ledger for metering, credits, pricing and entitlements
One real-time ledger for metering, credits, pricing and entitlements

Connect AI models and ship an app in minutes, without code
Connect AI models and ship an app in minutes, without code
Build real apps with the Claude or ChatGPT plan you already pay for
Build real apps with the Claude or ChatGPT plan you already pay for
Build, run and govern AI-ready backends, APIs and MCP servers

Build generative AI apps, agents and chatbots without code
Build generative AI apps, agents and chatbots without code


