01
Apify官方原廠
414.8萬/月
具備龐大市集的強大 actor 型雲端爬蟲平台,但對企業級代理伺服器(proxy)基礎設施的直接掌控較少。
AI 網頁擷取編輯評分:4.6免費增值、需聯絡報價+3.9%

依功能與用途,為你挑選 12 款 Bright Data 的替代工具。
| 排名 | 工具與標語 | 官方網域 | 每月造訪次數 | 月增幅 | 定價模式 |
|---|
| 主要市場 |
|---|
| 評分 |
|---|
| 比較 |
|---|
| ● | Bright Data | brightdata.com | 80.28萬 | -5.04萬 (-5.9%) | 免費試用、付費 | 美國 | 4.6 | 簡介 |
| 1 | Apify | apify.com | 414.78萬 | 15.68萬 (+3.9%) | 免費增值、需聯絡報價 | 美國 | 4.6 | 比較 |
| 2 | Firecrawl | firecrawl.dev | 182.82萬 | -3.57萬 (-1.9%) | 免費增值、需聯絡報價 | 美國 | 4.7 | 比較 |
| 3 | Thor Data | thordata.com | 18.2萬 | -6552 (-3.5%) | 免費試用、付費 | 波蘭 | 4.3 | 比較 |
| 4 | Exa | exa.ai | 106.26萬 | 15.28萬 (+16.8%) | 免費增值、需聯絡報價 | 美國 | 4.5 | 比較 |
| 5 | Jina AI | jina.ai | 28.08萬 | -5.57萬 (-16.5%) | 免費增值、付費 | 美國 | 4.7 | 比較 |
| 6 | Browserless | browserless.io | 18.55萬 | -4.98萬 (-21.2%) | 免費增值、付費、需聯絡報價 | 美國 | 4.4 | 比較 |
| 7 | Scrapingdog | scrapingdog.com | 8.97萬 | -1.59萬 (-15%) | 免費試用、付費 | 印度 | 4.3 | 比較 |
| 8 | WebScraping.AI | webscraping.ai | 1.49萬 | -1978 (-11.7%) | 免費增值、付費 | 美國 | 4.3 | 比較 |
| 9 | SmartProxy | smartproxy.org | 217 | -2.77萬 (-99.2%) | 免費試用、付費 | 瑞士 | 4.4 | 比較 |
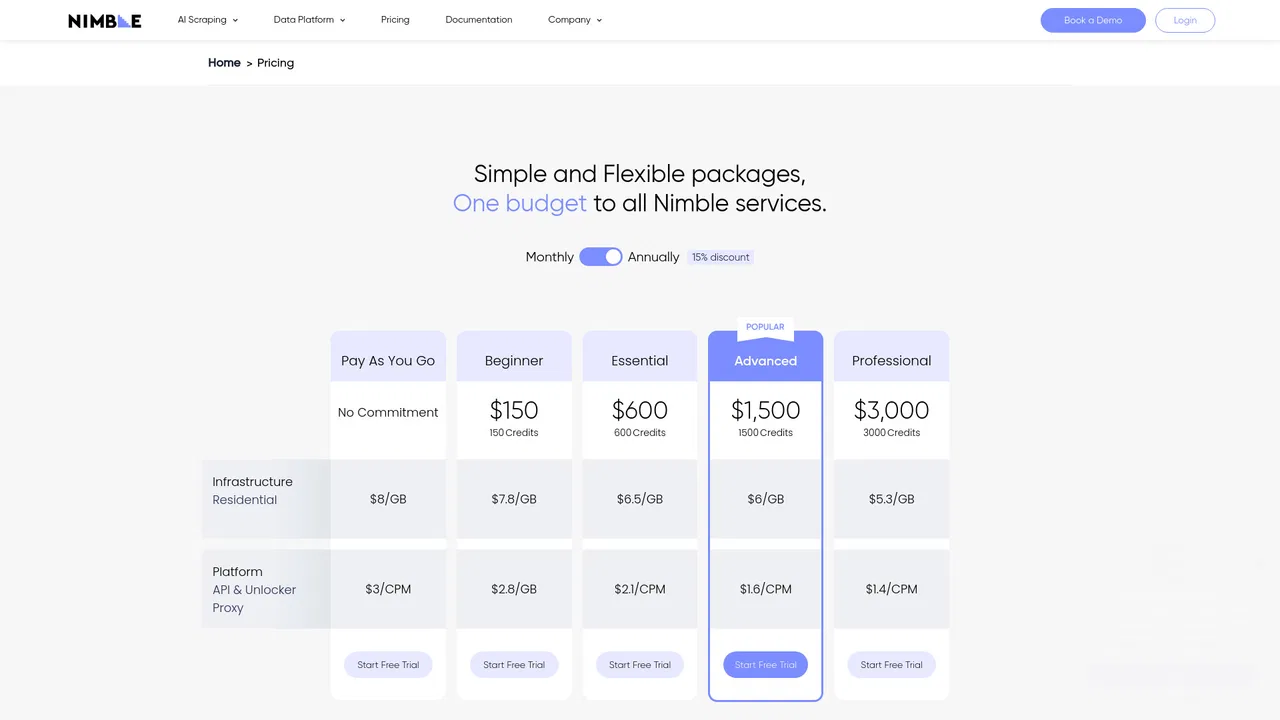
| 10 | Nimble API | nimbleapi.io | 0 | 0 (—) | 付費 | 全球 | 4.3 | 比較 |
| 11 | ScrapeGraphAI | scrapegraphai.com | 9.14萬 | -3.15萬 (-25.7%) | 免費增值、付費、需聯絡報價 | 美國 | 4.2 | 比較 |
| 12 | TinyFish | tinyfish.ai | 112.5萬 | 74.96萬 (+199.7%) | 免費增值、需聯絡報價 | 美國 | 4.4 | 比較 |
具備龐大市集的強大 actor 型雲端爬蟲平台,但對企業級代理伺服器(proxy)基礎設施的直接掌控較少。
免費 / 開源能把整個網站秒轉成適合 LLM 的乾淨 Markdown,但缺乏原生的住宅代理 IP 管理工具。


專項更強具備可擴展的無頭瀏覽器雲端自動化基礎設施,但缺乏內建的住宅代理池與預先包裝的爬蟲。
專項更強具備可擴展的無頭瀏覽器雲端自動化基礎設施,但缺乏內建的住宅代理池與預先包裝的爬蟲。

Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.

Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.
Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.

Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
免費 / 開源Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.
免費 / 開源Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.

專項更強Provides live web search and agentic cloud browser automation, but less focused on raw proxy network management.