
4.8萬/月
在雲端託管 OpenClaw、Hermes、Codex 等 AI 代理
免費增值、免費
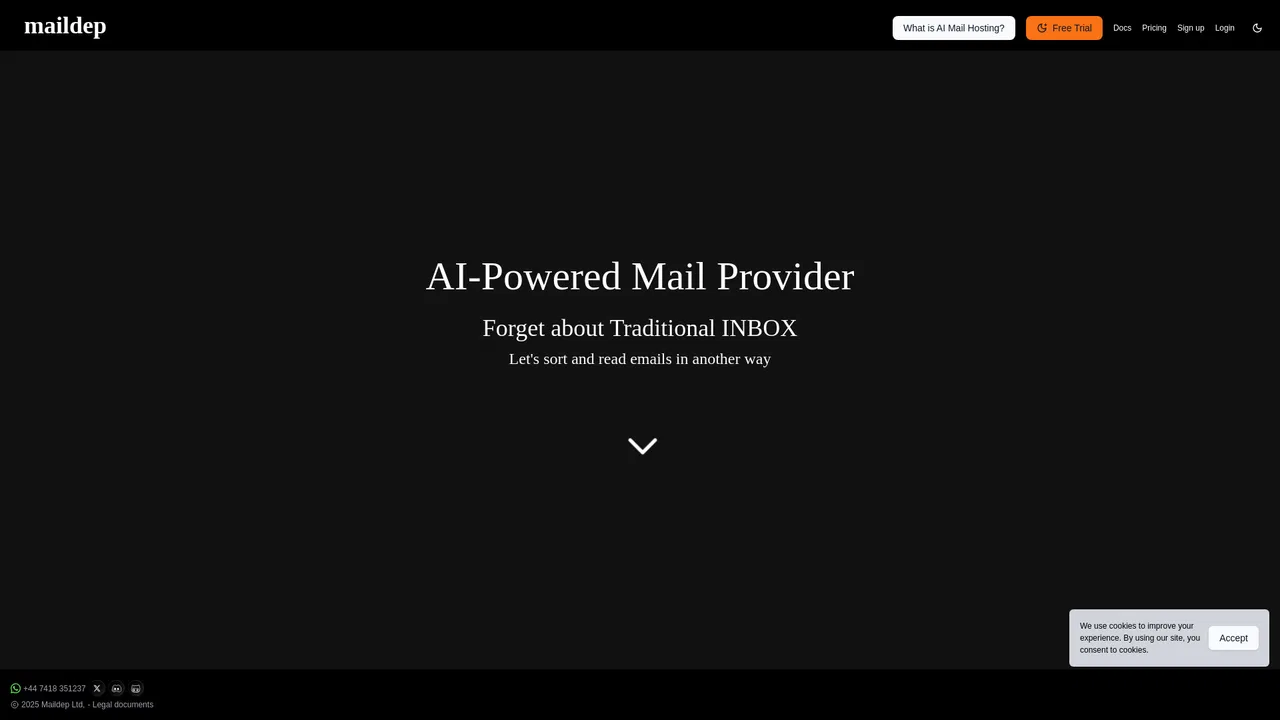
AI 互聯的 IMAP 企業郵件伺服器,幫你讀懂並整理收件匣
這是編輯給出的評估,滿分 5 分,不是使用者評分的平均值。 本頁的各方觀點由 AI 根據產品資訊歸納,不是真實使用者的評價。
依據 OpenAITools.app 於 2026-11-11 查驗的觀測資料,Maildep(maildep.com)是收錄於 AI 郵件助手的 AI 平台,每月產生 0 次造訪,月流量變化量為 +0(0%)。其主要地理市場為全球(流量佔比 —),並採用免費增值、免費試用、付費定價模式。依每月流量計算的主要競爭替代方案包括 Atomic Bot(每月 4.77萬次造訪),Zapmail(每月 11.24萬次造訪),KeepClaw(每月 4646 次造訪)。
把自己的 LLM 接到 IMAP 信箱真的超方便!
自動抓取發票跟會議任務,省超多時間。
DNS 跟 SPF 剛開始設定有點繁瑣。
以下短評基於實時網頁探查、定價機制與同類基準由 AI 綜合生成,用於呈現不同情境下的常見亮點與槽點,非實名真實用戶留言。
標準企業信箱,支援 IMAP/SMTP、SPF、DKIM、DMARC、TLS/SSL、垃圾郵件過濾與郵件伺服器自動探索,相容於 Outlook、Gmail、Thunderbird 與 Spark。
來信到達時自動產生摘要,並擷取其中的報告、會議、任務、待辦以及發票和帳單。
讓信箱接入 OpenAI、Azure、Anthropic、DeepSeek、Qwen、Groq、SambaNova、OpenRouter 或你自己的 Ollama 模型,使用你自己的 API 金鑰。
可在美國中部、英國、歐盟、日本、新加坡與印度六個資料中心之間選擇。
可按信箱啟用或停用 AI、加入自訂提示詞、維護忽略清單,並查看 AI 模型效能與代幣用量報告。
Maildep 將傳統的郵件伺服器託管與代理式 AI 處理結合。每個信箱都是普通的 IMAP/SMTP 帳戶,可與 Outlook、Gmail、Thunderbird、Spark 等常見用戶端配合使用,並具備 SPF、DKIM、DMARC、TLS/SSL、垃圾郵件過濾與自動探索功能。它的獨特之處在於來信到達後的處理:伺服器會以大語言模型處理郵件,產生摘要並擷取其中的報告、會議、任務、發票和帳單,還能自動產生回覆草稿。Maildep 估計這種自動化每天可為員工節省約兩小時。
該平台刻意做到模型中立。你可以提供自有的 OpenAI、Azure、Anthropic 或 DeepSeek API 金鑰,也可以接入 Groq、SambaNova、OpenRouter 乃至自建的 Ollama 執行個體。在 Maildep 這一側,使用這些 API 不額外收費;如果你不想自己管理金鑰,也可以購買在多個信箱間共享的代幣方案。管理員可以按信箱開關 AI、設定自訂提示詞與忽略清單,並查看效能與代幣用量報告,把 AI 的行為掌握在手中。
託管服務分布於美國、英國、歐盟、日本、新加坡與印度的六個資料中心,方便你把資料保留在指定的司法管轄區。方案從低成本的測試信箱一直到大型多網域商用帳戶;如果需要完全掌控,還有半自架的小型商用方案,以及基於 Kubernetes 與容器的完整自架安裝,附帶管理控制面板與一年維護。
將爆滿的客服收件匣轉化為摘要、擷取任務與回覆草稿,讓客服更快回應、更少遺漏。
讓發票與帳單自動從來信中擷取出來,作為結構化資料流轉,而不再靠人工輸入。
在自有網域上架設具備 SPF、DKIM 與 DMARC 的企業信箱,並選擇符合合規要求的資料中心區域。
接入你偏好的大模型 API 金鑰,微調提示詞、忽略清單與按信箱的 AI 功能,同時追蹤代幣用量。
同一分類下同類 AI 工具的流量並排比較
| 排名 | AI 工具 | 每月造訪次數 | 月增幅 | 直接流量占比 | 價格 | 正面對決 |
|---|---|---|---|---|---|---|
| ● | Maildep | 0 | 0% | — | 免費增值、免費試用、付費 | 目前產品 |
| 1 | Atomic Bot | 4.77萬 | -7.8% | 40% 直接流量 | 免費增值、免費 | 對比 Atomic Bot |
| 2 | Zapmail | 11.24萬 | -5.9% | 77% 直接流量 | 付費 | 對比 Zapmail |
| 3 | KeepClaw | 4646 | +17.2% | 39% 直接流量 | 免費試用、付費 | 對比 KeepClaw |
| 4 | EmpirioLabs AI | 3.79萬 | +15.2% | 40% 直接流量 | 免費增值、付費 | 對比 EmpirioLabs AI |
| 5 | Openclaw AI | 1.28萬 | -30.5% | 40% 直接流量 | Free (self-hosted), Paid cloud plans from $19.99/month; yearly saves 25% | 對比 Openclaw AI |
| 6 | Sendmux | 37 | -98.3% | 32% 直接流量 | 免費 | 對比 Sendmux |
在雲端託管 OpenClaw、Hermes、Codex 等 AI 代理
Zapmail is cold email infrastructure as a service. Instead of assembling SMTP relays or gambling on resold accounts, you get US-hosted Google and Microsoft 365 business mailboxes with SPF, DKIM, DMARC, and tracking domains configured automatically, then exported straight into your outreach tool of choice.
Zapmail is cold email infrastructure as a service. Instead of assembling SMTP relays or gambling on resold accounts, you get US-hosted Google and Microsoft 365 business mailboxes with SPF, DKIM, DMARC, and tracking domains configured automatically, then exported straight into your outreach tool of choice.
專業 AI 模型託管、最佳化端點與隨需 GPU 基礎設施
免費 / 開源可自架或雲端運行的開源個人 AI 助理
Sendmux is an email API built for AI agents. It gives each agent a real mailbox on a verified domain or a shared address, lets it send outbound mail through your own providers, and streams inbox events live so agents can react instead of polling.

MyClaw is a managed cloud hosting service for OpenClaw (formerly Clawdbot) agents. It gives you an always-on private AI agent with a cloud computer, preinstalled automation skills, daily backups and automatic updates, so you get a 24/7 assistant without touching a server.
MyClaw is a managed cloud hosting service for OpenClaw (formerly Clawdbot) agents. It gives you an always-on private AI agent with a cloud computer, preinstalled automation skills, daily backups and automatic updates, so you get a 24/7 assistant without touching a server.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.