01
Apify官方原厂
414.8万/月
拥有庞大应用市场的强大 actor 型云端爬虫平台,但对企业级代理服务器底层基础设施的直接掌控较少。},{de:
AI 网页抓取编辑评分:4.6免费增值,定价请咨询+3.9%

根据功能和用途,为你挑选 12 款 Bright Data 的替代工具。
| 排名 | 工具和标语 | 官方域名 | 月访问量 | 月度增长 (MoM) | 定价模式 |
|---|
| 主要市场 |
|---|
| 评分 |
|---|
| 比较 |
|---|
| ● | Bright Data | brightdata.com | 80.28万 | -5.04万 (-5.9%) | 免费试用,付费 | 美国 | 4.6 | 概览 |
| 1 | Apify | apify.com | 414.78万 | 15.68万 (+3.9%) | 免费增值,定价请咨询 | 美国 | 4.6 | 比较 |
| 2 | Firecrawl | firecrawl.dev | 182.82万 | -3.57万 (-1.9%) | 免费增值,定价请咨询 | 美国 | 4.7 | 比较 |
| 3 | Thor Data | thordata.com | 18.2万 | -6552 (-3.5%) | 免费试用,付费 | 波兰 | 4.3 | 比较 |
| 4 | Exa | exa.ai | 106.26万 | 15.28万 (+16.8%) | 免费增值,定价请咨询 | 美国 | 4.5 | 比较 |
| 5 | Jina AI | jina.ai | 28.08万 | -5.57万 (-16.5%) | 免费增值,付费 | 美国 | 4.7 | 比较 |
| 6 | Browserless | browserless.io | 18.55万 | -4.98万 (-21.2%) | 免费增值,付费,定价请咨询 | 美国 | 4.4 | 比较 |
| 7 | Scrapingdog | scrapingdog.com | 8.97万 | -1.59万 (-15%) | 免费试用,付费 | 印度 | 4.3 | 比较 |
| 8 | WebScraping.AI | webscraping.ai | 1.49万 | -1978 (-11.7%) | 免费增值,付费 | 美国 | 4.3 | 比较 |
| 9 | SmartProxy | smartproxy.org | 217 | -2.77万 (-99.2%) | 免费试用,付费 | 瑞士 | 4.4 | 比较 |
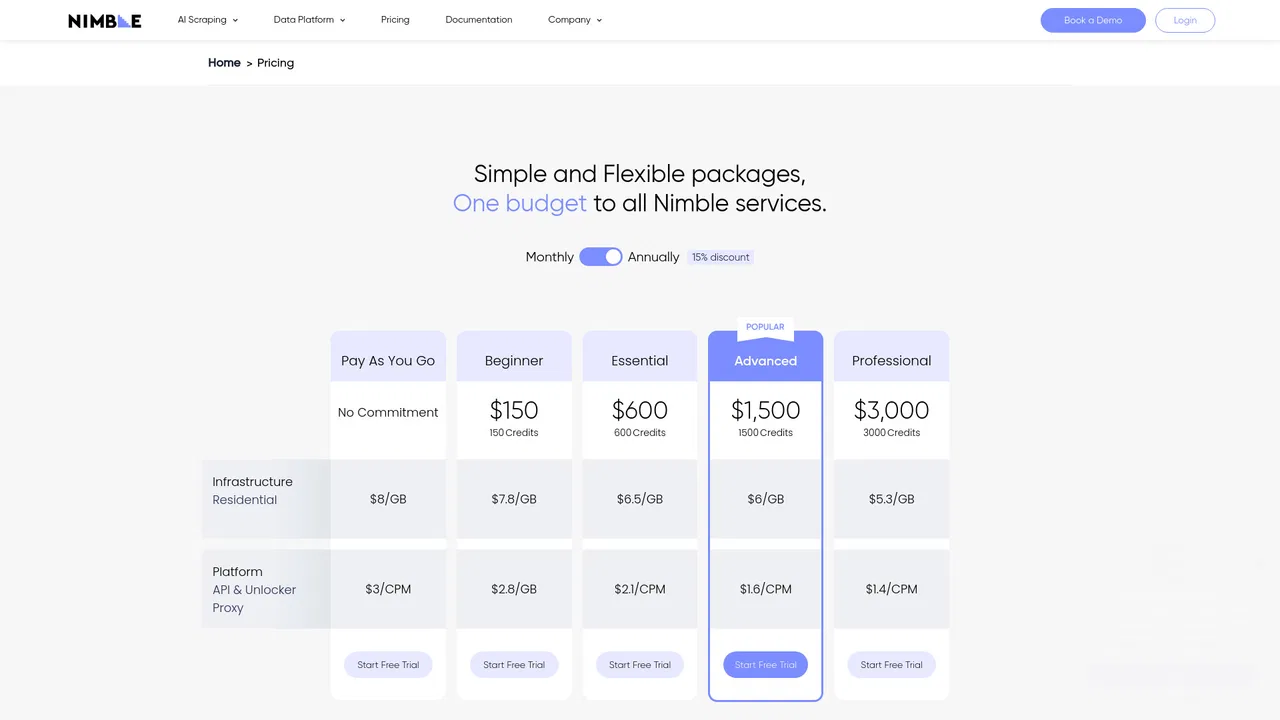
| 10 | Nimble API | nimbleapi.io | 0 | 0 (—) | 付费 | 全球 | 4.3 | 比较 |
| 11 | ScrapeGraphAI | scrapegraphai.com | 9.14万 | -3.15万 (-25.7%) | 免费增值,付费,定价请咨询 | 美国 | 4.2 | 比较 |
| 12 | TinyFish | tinyfish.ai | 112.5万 | 74.96万 (+199.7%) | 免费增值,定价请咨询 | 美国 | 4.4 | 比较 |
拥有庞大应用市场的强大 actor 型云端爬虫平台,但对企业级代理服务器底层基础设施的直接掌控较少。},{de:
免费 / 开源能把整个网站秒转成适合 LLM 的干净 Markdown,但缺乏原生的住宅代理 IP 管理工具。


专项更强具备可扩展的无头浏览器云端自动化基础设施,但缺乏内置的住宅代理池与预先包装的爬虫。
专项更强具备可扩展的无头浏览器云端自动化基础设施,但缺乏内置的住宅代理池与预先包装的爬虫。

Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Affordable web scraping and proxy API with reliable CAPTCHA handling, but fewer advanced enterprise data pipelines.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.
Simple API for handling proxies and CAPTCHAs during extraction, but less suited for massive custom proxy rotations.

Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.
Strong residential proxy network for data extraction, but offers fewer out-of-the-box structured scraping APIs.

Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
Combines AI-powered data extraction with robust proxy infrastructure, but has a smaller developer ecosystem.
免费 / 开源Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.
免费 / 开源Open-source scraping library using natural language prompts, but requires self-hosting and manual proxy configuration.

专项更强Provides live web search and agentic cloud browser automation, but less focused on raw proxy network management.