SERP API (Bright Data) 记录了 802,752 月访问量,月度环比增长为 -5.9%,定价为付费,定价请咨询。Serpex 记录了 2,405 月访问量,增长率为 -34.3%,定价为免费增值,免费试用,付费。
经济实惠的实时搜索 API,一次调用即可返回结构化 JSON 与网页正文。
| 维度 / 指标 | ![]() | |
|---|---|---|
| 官方域名 | brightdata.com | serpex.dev |
| 定价模式 | 付费,定价请咨询 | 免费增值,免费试用,付费 |
| 月访问量 | 80.28万 (802,752) | 2405 (2,405) |
| 月度环比流量变化 | -5.04万 (-5.9%) | -1255 (-34.3%) |
| 主要市场与份额 | 🇺🇸 美国 (29.5%) | 🇮🇳 印度 (91.3%) |
| 直接访问 / 月 | 38.37万 | 936 |
| 用户评分 | 4.6 | 4.3 |
| 支持的平台 | 网站 | 网站 |

Bright Data's SERP API is a real-time search engine scraping API that returns Google, Bing, DuckDuckGo, and Yandex results in JSON, HTML, or Markdown, with automatic proxy management, unblocking, and parsing, and geo-targeting at no extra cost.
Pull on-demand search results from Google, Bing, DuckDuckGo, and Yandex, with support for many localized domains and languages.
Receive responses as structured JSON, raw HTML, or Markdown, so pipelines can consume results without custom parsing when you want the fast path.
Proxy rotation, CAPTCHA solving, and unblocking are handled by the API, so you do not have to build or maintain that infrastructure.
Target results from a specific country or language at no extra cost, useful for local SEO and international market research.
经济实惠的实时搜索 API,一次调用即可返回结构化 JSON 与网页正文。
提交查询即可获得整洁、结构化的实时网页结果 JSON,可直接解析、排序或喂给模型。
用同一个 API Key 将任意 URL 转换为干净易读的 Markdown,去除模板噪音,让抓取文本可直接用于 RAG 与摘要。
请求会在多个底层搜索来源间路由,并配合健康监控与自动重试,单一来源无结果不会中断你的管道。
提供 Python、JavaScript、MCP 与 LangChain 的官方库与代码示例,几行代码即可为智能体或应用加入实时搜索。
免费 / 开源用提示词取代选择器,把任意网站变成结构化 JSON
内置代理、浏览器与反爬处理的网页抓取 API
面向 AI 智能体、SEO 与数据团队的实时多引擎搜索结果 API
一次 API 调用,从任意网站提取干净的结构化数据

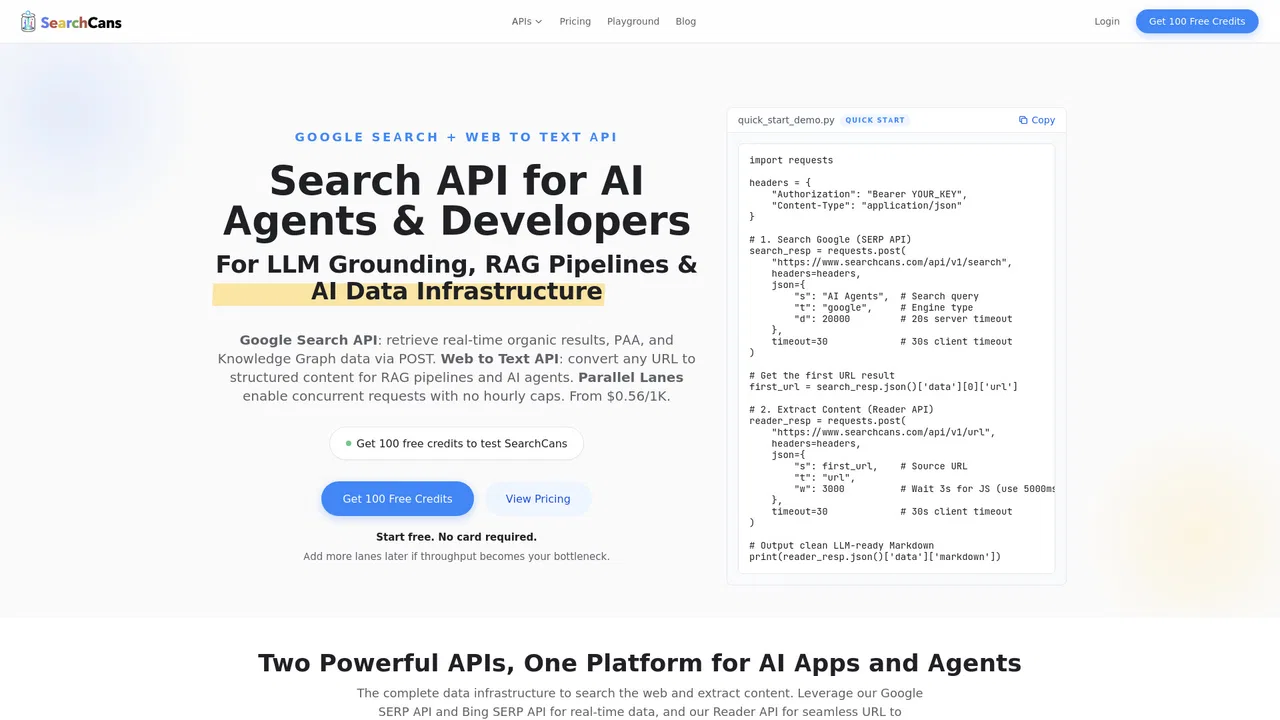
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.