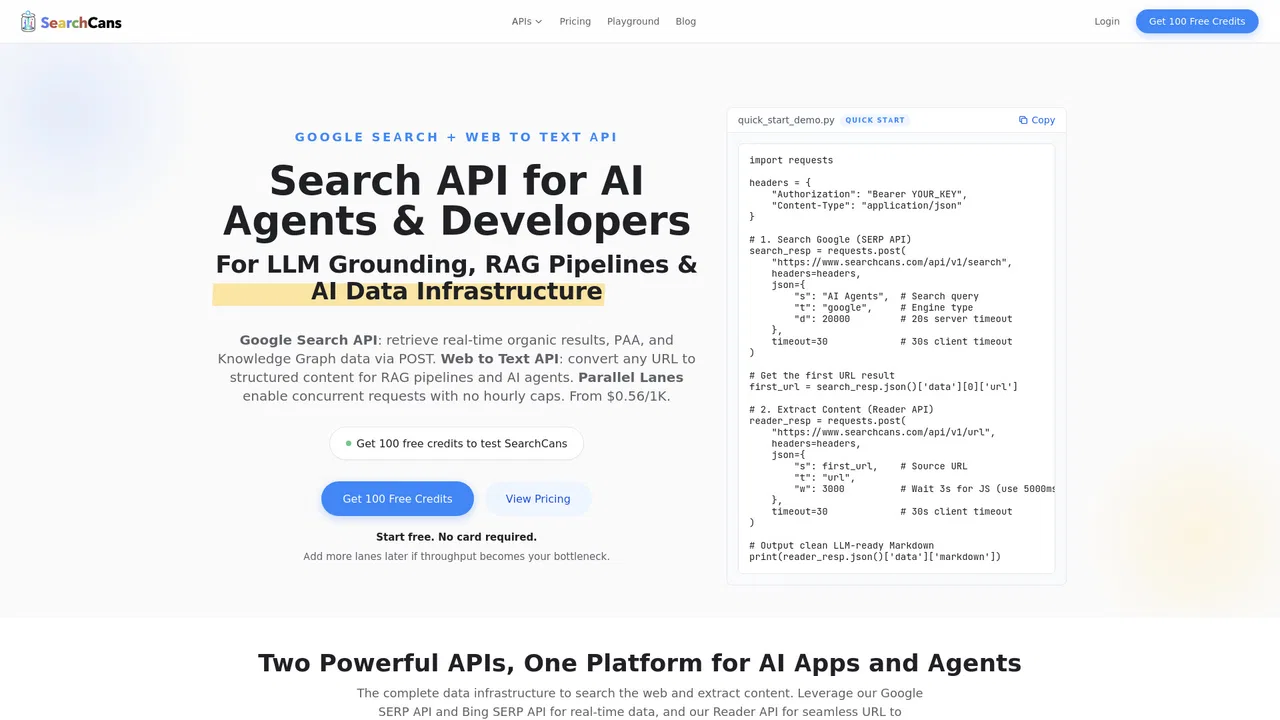
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.
网站月访问量估算
数据为该域名的 Similarweb 流量估算,不是活跃用户数。仅展示有数据的统计月份;采集时间与流量统计月份分别标注。
采集于 2026年11月11日

这是编辑给出的评估,满分 5 分,不是用户打分的平均值。 本页的各方观点由 AI 根据产品信息归纳,不是真实用户的评价。
根据 OpenAITools.app 于 2026-11-11 核对的流量数据,SearchCans(searchcans.com)是一个收录在 AI 网页抓取下的 AI 平台,月访问量为 4223,月度环比流量变化为 -3628(-46.2%)。其主要地理市场为美国(58% 流量份额),采用免费试用,付费定价模式。按月流量计算的主要竞争替代方案包括 Serpex(2405 次访问/月),Exa(106.26万次访问/月),Thor Data(18.2万次访问/月)。
没有每小时频率限制,做RAG和Agent爬虫爽到飞起!
SERP返回数据很干净,网页转Markdown转换器很稳。
预付费按量扣费,比包月套路良心多了。
文档稍微简陋了点,自己摸索了一会。
以下短评基于实时网页探查、定价机制与同类产品基准由 AI 综合模拟生成,旨在呈现不同使用场景下的常见槽点与亮点,非实名真实用户评价。
Structured JSON results from Google and Bing — including Shopping, Images, News, Videos and Short Videos endpoints — for search features, monitoring and production apps.
Convert URLs, PDFs and Office documents into clean Markdown or HTML, with a configurable JavaScript wait for client-rendered pages.
Pair live SERP results with Reader extraction in one pipeline so agents, RAG systems and LLM workflows answer with current, citable context.
Scale by adding concurrent lanes rather than respecting hourly caps, and stack eligible plans to add lanes to a single account without rebuilding integrations.
Add a web screenshot endpoint and file extraction alongside search and reader, all under one key and one credit balance.
Countries and languages can be targeted per request, and the docs cover error codes, rate limits, proxy tiers and credit rules in detail.
SearchCans is an API platform that pairs real-time Google and Bing SERP JSON with a Reader API that converts any page, PDF or Office file into clean Markdown or HTML. It is built for AI agents and RAG pipelines that need live search results plus extracted source text, with parallel lanes instead of hourly rate caps.
Give agents current web context by pairing live search results with extracted page content, so answers cite real sources instead of stale training data.
Build ingestion that searches for a topic, follows result URLs and converts each page into Markdown chunks ready for embedding and indexing.
Convert uploaded PDFs, Word files and web pages into clean Markdown for documentation workflows and internal knowledge bases.
Pull structured SERP JSON on a schedule to track keyword rankings and competitor visibility without maintaining scraping infrastructure.
同一分类下同类 AI 工具的流量并排对比
| 排名 | AI 工具 | 月访问量 | 月度环比增长 | 直接流量占比 | 定价 | 头对头 |
|---|---|---|---|---|---|---|
| ● | SearchCans | 4223 | -46.2% | 39% 直接流量 | 免费试用,付费 | 当前产品 |
| 1 | Serpex | 2405 | -34.3% | 39% 直接流量 | 免费增值,免费试用,付费 | 对比 Serpex |
| 2 | Exa | 106.26万 | +16.8% | 57% 直接流量 | 免费增值,定价请咨询 | 对比 Exa |
| 3 | Thor Data | 18.2万 | -3.5% | 39% 直接流量 | 免费试用,付费 | 对比 Thor Data |
| 4 | Jina AI | 28.08万 | -16.5% | 51% 直接流量 | 免费增值,付费 | 对比 Jina AI |
| 5 | Dumpling AI | 1.88万 | +27.8% | 41% 直接流量 | 免费增值 | 对比 Dumpling AI |
| 6 | TinyFish | 112.5万 | +199.7% | 36% 直接流量 | 免费增值,定价请咨询 | 对比 TinyFish |
为 AI 智能体打造的抓取、搜索与数据丰富 API
XCrawl is an AI-ready web scraping API that turns websites and search engine results into structured JSON, Markdown, and screenshots for LLM pipelines, agents, and data workflows.

Bright Data's SERP API is a real-time search engine scraping API that returns Google, Bing, DuckDuckGo, and Yandex results in JSON, HTML, or Markdown, with automatic proxy management, unblocking, and parsing, and geo-targeting at no extra cost.
免费 / 开源用提示词取代选择器,把任意网站变成结构化 JSON
内置代理、浏览器与反爬处理的网页抓取 API