Nebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.
459개 워크플로에서 트래픽 추정치, 기능, 대안을 비교하세요.
“NVIDIA GPUs”·결과 93개
처음으로Nebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.

Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.


Together AI is the AI Native Cloud — a full-stack platform for running, fine-tuning and training open-source models. It spans serverless inference APIs, dedicated endpoints, GPU clusters, post-training and storage, all backed by in-house systems research.

하이퍼스케일러보다 최대 80% 저렴한 온디맨드 클라우드 GPU

31개 제공업체의 클라우드 GPU 가격 실시간 비교


분 단위 인스턴스와 초 단위 샌드박스를 갖춘 저렴한 클라우드 GPU.
설치 없이 클라우드에서 네이티브 ComfyUI를 실행하고 고속 GPU와 원클릭 서버리스 API를 활용하세요
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.


Runware is an AI inference platform that exposes an enormous model catalog — images, video, audio, LLMs and 3D — through a single API endpoint, alongside serverless GPU compute and reserved capacity running on modular data centers the company designs and operates itself. It is aimed at developers and product teams who want to ship generative features without managing infrastructure.


내 GPU나 Mac이 실제로 돌릴 수 있는 로컬 AI 모델 확인
500개 이상의 이미지·비디오·오디오·LLM 모델을 하나의 OpenAI 호환 API로
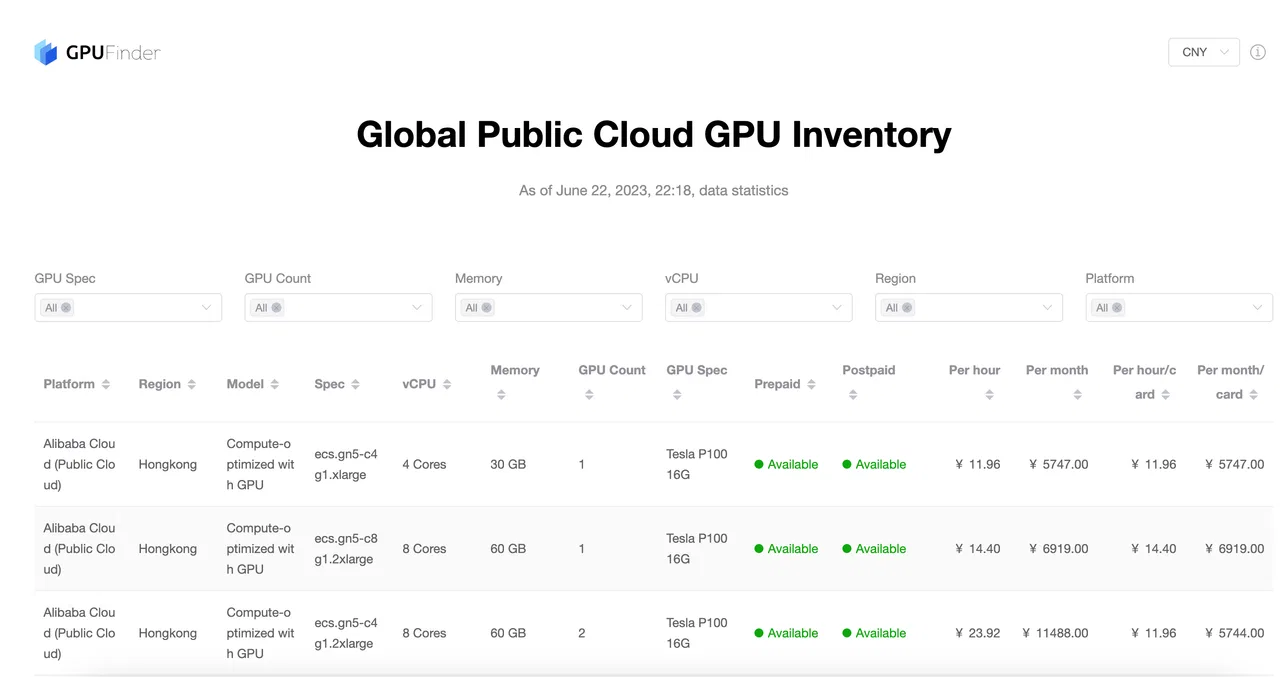
퍼블릭 클라우드 GPU 인스턴스 사양과 가격을 한 표에서 비교