01
9.2K/mo
SpecialistTest, monitor and improve the voice AI agents you already run
AI Voice AssistantsEditorial score: 4.4Paid+23.1%

9.2K/mo+23.1%
SpecialistTest, monitor and improve the voice AI agents you already run
Paid
Automated QA, simulation and observability for voice and chat AI agents
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026

This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
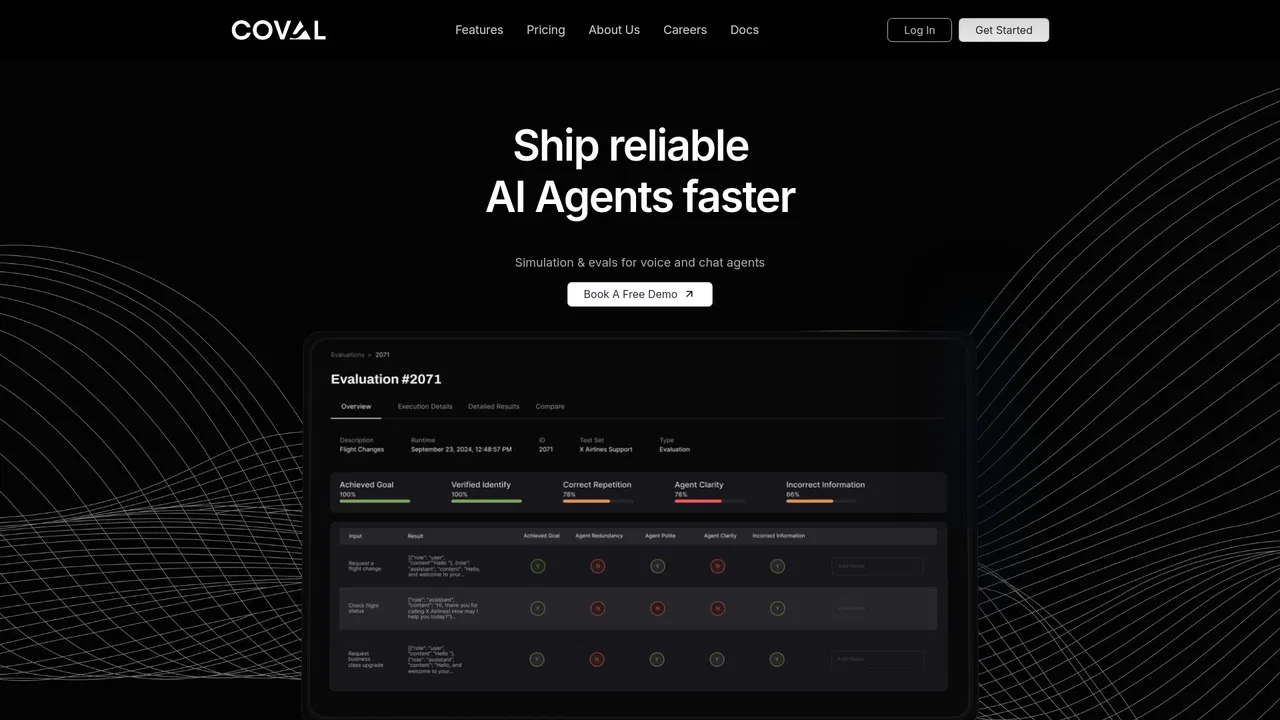
According to OpenAITools.app telemetry verified on 2026-11-11, Cekura (cekura.ai) is an AI platform indexed under AI Agent generating 73.23K monthly visits with a month-over-month traffic delta of -17.11K (-18.9%). Its primary geographic market is United States (27.8% traffic share), and it operates on a Contact for Pricing pricing model. Top competing alternatives by monthly volume include Roark (9.23K visits/mo), Coval (161 visits/mo), Cyara (16.7K visits/mo).
Caught edge cases our QA team missed for weeks.
Simulation speed is impressive, pricing is a bit opaque.
Great observability for voice agents.
Saved us from embarrassing jailbreak failures in production.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Run thousands of synthetic conversations across personas, edge cases and scenarios before an agent reaches real users.
Track live calls and chats for sentiment drift, latency, drop-offs, failed tool calls and unresolved intents around the clock.
Cekura detects a failure, reproduces it in simulation, suggests a fix, and re-runs the gate to verify the patch.
Run identical scenarios across providers and models to compare reliability, latency and interruption handling on equal footing.
Probe agents for jailbreaks, PII leaks, toxic intent and off-script behaviour before they surface in production.
Cekura addresses a problem that appears the moment an AI voice agent goes live: conversational agents fail in ways traditional software tests never catch. The platform generates thousands of synthetic conversations against personas, edge cases and adversarial prompts before launch, so teams can gate every deployment on a passing suite rather than discovering bugs in front of real customers.
The product is organized around three loops. Test covers pre-production simulation, instruction-following, tool calls, hallucination and compliance checks. Monitor watches live calls and chats in production, detecting sentiment drift, latency changes, dropped conversations and unresolved intents. Improve closes the loop: Cekura flags a failure, reproduces it in simulation, suggests a prompt or configuration patch, then re-runs the gate to confirm the fix. Alongside this, Cekura Bench publishes head-to-head comparisons of voice platforms and models — turn latency, interruption handling, speech-to-text word error rate — using the same scenarios and scoring.
Cekura targets engineering, QA and CX teams building customer-facing agents in support, sales, healthcare and similar regulated environments. It emphasizes enterprise compliance (HIPAA, SOC 2, GDPR) and integrates with the voice stack teams already use, including LiveKit, Pipecat, ElevenLabs, Cartesia, Retell, Vapi and Speechmatics. A free trial is offered, with pricing available on request.
Wire Cekura into the deployment pipeline so no prompt or tool change ships without passing a simulation suite.
Automatically score thousands of conversations for instruction-following, hallucination and compliance instead of sampling manually.
Watch live traffic for sentiment drift and emerging failure patterns, and catch regressions before customers escalate.
Benchmark Vapi, Retell, ElevenLabs, Pipecat and custom setups with the same scenarios and scoring to make an evidence-based choice.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Cekura | 73.23K | -18.9% | 28% direct | Contact for Pricing | Current |
| 1 | Roark | 9.23K | +23.1% | 52% direct | Paid | vs Roark |
| 2 | Coval | 161 | -93.8% | 40% direct | Contact for Pricing | vs Coval |
| 3 | Cyara | 16.7K | -48.3% | 40% direct | Contact for Pricing | vs Cyara |
| 4 | Hamming AI | 17.81K | -31.7% | 37% direct | Contact for Pricing | vs Hamming AI |
| 5 | Cekura (formerly Vocera) | 0 | 0% | — | Contact for Pricing | vs Cekura (formerly Vocera) |
| 6 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
SpecialistTest, monitor and improve the voice AI agents you already run
SpecialistTest, monitor and improve the voice AI agents you already run
SpecialistProve your voice agents are ready — with simulation, production evals, and human QA in one loop
SpecialistAgentic CX trust platform for testing, monitoring and observing every customer journey
SpecialistAgentic CX trust platform for testing, monitoring and observing every customer journey

Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call
Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call
Automated testing, simulation, and live observability for voice and chat AI agents
Automated testing, simulation, and live observability for voice and chat AI agents

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents

Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org
Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org

Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.
Free / Open-sourceFind and fix problems in your AI agents before users do
Free / Open-sourceFind and fix problems in your AI agents before users do

SpecialistAttack-led AI security testing and red teaming
SpecialistAttack-led AI security testing and red teaming

Free / Open-sourceAutonomous AI QA agents that verify your web and mobile app on every pull request
Free / Open-sourceAutonomous AI QA agents that verify your web and mobile app on every pull request