01
73.2K/mo
Automated QA, simulation and observability for voice and chat AI agents
AI AgentEditorial score: 4.2Contact for Pricing28% direct
Test, monitor and improve the voice AI agents you already run
Estimated monthly website visits
Similarweb estimates for this domain, not active users. Only available observation months are shown; collection date is separate from the traffic period.
Collected Nov 11, 2026

This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Roark (roark.ai) is an AI platform indexed under AI Voice Assistants generating 9.23K monthly visits with a month-over-month traffic delta of +1.73K (+23.1%). Its primary geographic market is United States (75.7% traffic share), and it operates on a Paid pricing model. Top competing alternatives by monthly volume include Cekura (73.23K visits/mo), Cyara (16.7K visits/mo), Coval (161 visits/mo).
Simulating hundreds of callers before launch saved us from a total PR disaster.
The audio metrics granularity is impressive.
Great observability for conversational AI agents.
Pricing is steep for smaller teams, but worth it for enterprise.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Run your agent against hundreds of realistic personas, accents, background noise and edge cases before a customer ever dials in.
Red-team callers attempt prompt injection, jailbreaks and social engineering to check your agent holds policy under pressure.
Every live call is scored as it lands on more than 500 metrics, with issues filed, alerts fired and traces attached.
Purpose-built audio models measure pronunciation, emotion, vocal stress, pace, interruptions and dead air, not just transcript quality.
Rerun the whole suite on every prompt or model change and diff it against your last green baseline to catch regressions before merge.
The public Roark Live Bench calls 300+ model combinations over the real phone network and ranks them on end-to-end scores.
Roark is a QA and evaluation platform built specifically for voice AI agents, not another agent builder. It closes the loop between testing and production: simulate an agent against hundreds of callers before launch, score every live call once it is running, and use the findings to ship a proven fix. The team behind it is backed by Y Combinator and reports SOC 2 Type II along with HIPAA BAA support.
Simulation is the pre-launch side. Roark runs your agent against realistic personas built from your own call types, including the angry caller, the rambler and the interrupter, with native accents, code-switching and background noise across 45 languages. Adversarial red-team callers probe for prompt injection and social engineering, while load and health tests confirm the agent survives peak concurrency and stays reachable after launch.
The second half is observability. Every production call is scored as it arrives using Roark's purpose-built audio models rather than a generic LLM grading a transcript, measuring pronunciation, accent clarity, emotion, vocal stress, pace, interruptions and dead air alongside resolution, empathy, hallucination and compliance checks. Issues are filed automatically, dashboards and OTEL traces are available, and changes are diffed so you can see that a fix moved the metric without breaking a caller somewhere else. Roark also publishes Live Bench, a free public leaderboard that scores 300+ speech-to-text, LLM and speech-engine combinations over the real phone network.
Run regression suites in CI and simulate hundreds of callers so prompt or model changes are validated before they reach customers.
Score every support call for identity checks, disclosures and resolution, and file compliance issues automatically when policy is broken.
Use red-team callers and multilingual personas to pressure-test agents handling refunds, bookings or clinical intake before a wider rollout.
Hold agents to measurable standards in highly regulated settings using HIPAA-ready handling and auditable scores.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Roark | 9.23K | +23.1% | 52% direct | Paid | Current |
| 1 | Cekura | 73.23K | -18.9% | 28% direct | Contact for Pricing | vs Cekura |
| 2 | Cyara | 16.7K | -48.3% | 40% direct | Contact for Pricing | vs Cyara |
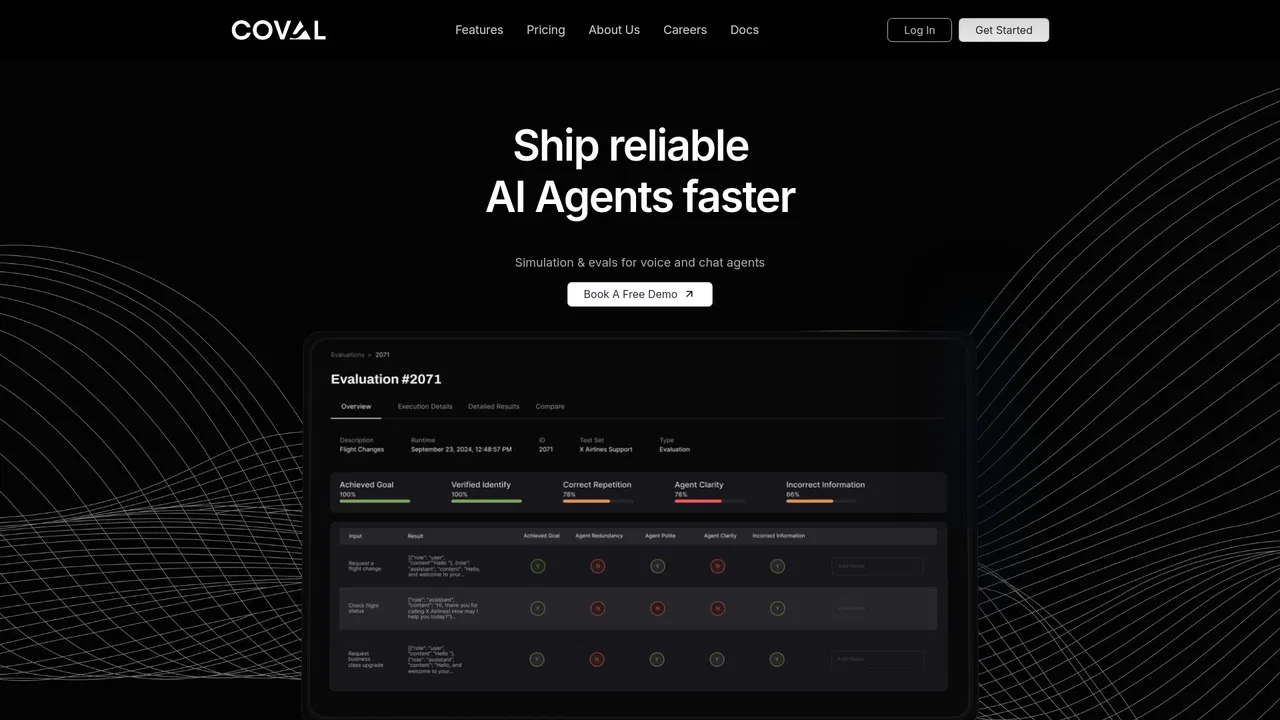
| 3 | Coval | 161 | -93.8% | 40% direct | Contact for Pricing | vs Coval |
| 4 | Relyable | 3.45K | -45.5% | 39% direct | Freemium, Paid | vs Relyable |
| 5 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
| 6 | Hamming AI | 17.81K | -31.7% | 37% direct | Contact for Pricing | vs Hamming AI |
Automated QA, simulation and observability for voice and chat AI agents
Agentic CX trust platform for testing, monitoring and observing every customer journey
Agentic CX trust platform for testing, monitoring and observing every customer journey
Prove your voice agents are ready — with simulation, production evals, and human QA in one loop
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.
Free / Open-sourceShip bulletproof AI voice agents 100x faster with simulation, evaluation and live monitoring.

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents

Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call
Free / Open-sourceThe security layer for voice and chat agents: test, red-team, and monitor every call

Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org
Free / Open-sourceStandardize LLM evaluation, observability, and red teaming across your whole org

Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceEvaluate, monitor, and govern your AI applications in production
Free / Open-sourceFind and fix problems in your AI agents before users do
Free / Open-sourceFind and fix problems in your AI agents before users do

Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI
Free / Open-sourceAgent observability, evaluation, and continuous improvement for production AI
Free / Open-sourceThe simulation platform for agent self-improvement
Free / Open-sourceThe simulation platform for agent self-improvement
Free / Open-sourceAI governance, testing, and observability for regulated enterprises
Free / Open-sourceAI governance, testing, and observability for regulated enterprises