01
2.2M/mo
Chat with 30+ leading AI models in one clean, fast workspace
AI ChatbotEditorial score: 3.9Freemium23% direct

2.2M/mo
Chat with 30+ leading AI models in one clean, fast workspace
Freemium

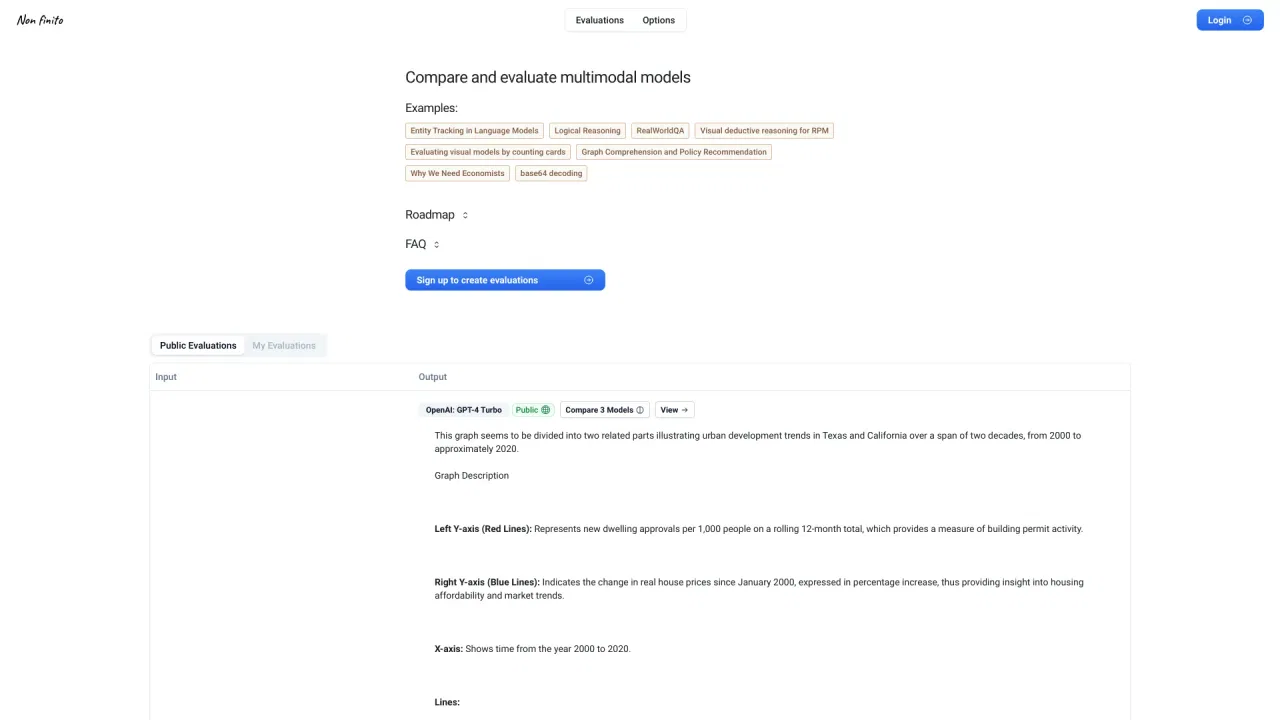
Compare and Evaluate Multimodal Models Side by Side
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, Non finito (nonfinito.xyz) is an AI platform indexed under AI Models generating 0 monthly visits with a month-over-month traffic delta of +0 (0%). Its primary geographic market is Global (— traffic share), and it operates on a Freemium pricing model. Top competing alternatives by monthly volume include Chatbot App (2.17M visits/mo), Future AGI (121.74K visits/mo), Appen (665.84K visits/mo).
Finally a clean side-by-side comparison tool that actually works.
Saved hours debugging why DeepSeek and o1 handle reasoning puzzles differently.
Best model arena out there right now.
Free tier limits hit way too fast during heavy testing sessions.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Run one prompt against multiple models and read the outputs in parallel columns, including multi-model view options for larger comparisons.
Each answer can be marked as passing or failing, turning transcripts into a trackable record of model behaviour over time.
Keep evaluations in your own workspace or publish them so others can inspect and re-use your prompts and results.
Example evaluations cover language reasoning, visual analogy, counting, graph comprehension and structured decoding rather than text alone.
Public evaluations reference systems such as OpenAI o1, DeepSeek R1, Qwen QwQ 32B Preview and xAI Grok 2 evaluated on identical inputs.
Non finito treats model quality as something you measure rather than assume. The core loop is simple: write a prompt, select two or more models, and read their answers next to each other. Public evaluations on the site span reasoning puzzles such as finding the least odd prime factor of a large number, visual deductive reasoning and real-world QA, RPM-style visual analogies, count-the-cards tasks, graph comprehension and policy recommendation, entity tracking, and base64 decoding — with models including OpenAI o1, DeepSeek R1, Qwen QwQ 32B Preview and xAI Grok 2 compared on identical inputs.
Beyond raw comparison, the platform records a verdict for each answer. Evaluations can be marked as pass or fail, which turns a pile of transcripts into something closer to a scoreboard you can revisit. That makes it useful for tracking whether a new model release actually improves on the previous one for your specific prompts, rather than trusting a leaderboard built from someone else's tasks.
Evaluations can be kept private in your workspace or published publicly for others to view and compare, and the site invites visitors to sign up and create their own. It is a lightweight research tool, so expect a focused interface rather than a full enterprise evaluation suite with automated scoring pipelines.
Re-run your own prompt set on a newly released model and compare verdicts against the previous version instead of relying on generic benchmarks.
Keep the prompts that matter to your product in one place with recorded outcomes, so regressions are visible when providers update their models.
Run the same instructions across several commercial and open models to see which handles your specific reasoning or visual tasks.
Read published evaluations that show full reasoning traces side by side, which is useful for teaching about model behaviour and failure modes.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | Non finito | 0 | 0% | — | Freemium | Current |
| 1 | Chatbot App | 2.17M | -9.7% | 23% direct | Freemium | vs Chatbot App |
| 2 | Future AGI | 121.74K | -7.8% | 59% direct | Freemium, Usage-based | vs Future AGI |
| 3 | Appen | 665.84K | +0.2% | 36% direct | Contact for Pricing | vs Appen |
| 4 | Label Studio | 137.2K | -16.1% | 34% direct | Contact for Pricing, Free | vs Label Studio |
| 5 | ModelScope | 3.09M | +5.1% | 68% direct | Free | vs ModelScope |
| 6 | CanIRun.ai | 284.89K | -20.1% | 48% direct | Free | vs CanIRun.ai |
Chat with 30+ leading AI models in one clean, fast workspace
Chat with 30+ leading AI models in one clean, fast workspace

Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents
Free / Open-sourceBuild, simulate, evaluate and monitor self-improving AI agents

Human-validated training data and evaluation services for frontier AI models

Free / Open-sourceLabel any data. Evaluate any AI.
Free / Open-sourceOpen-source model and dataset hub with one-click online demos
Free / Open-sourceOpen-source model and dataset hub with one-click online demos

SpecialistCheck which local AI models your GPU or Mac can actually run
SpecialistCheck which local AI models your GPU or Mac can actually run

Every top AI model in one chat, for the price of one subscription
Every top AI model in one chat, for the price of one subscription
Five frontier AIs debate your question, you get the verdict

Enterprise AI infrastructure where software and expert humans work together
Enterprise AI infrastructure where software and expert humans work together
Evaluate every frontier model against your own workflows
Evaluate every frontier model against your own workflows
Free / Open-sourceDiscover, download and generate with open-source AI models for image, video and 3D.