01
757.5K/mo
All-in-one AppSec platform that finds and auto-fixes vulnerabilities
AI Code ReviewEditorial score: 4.4Freemium+9.6%

757.5K/mo+9.6%
All-in-one AppSec platform that finds and auto-fixes vulnerabilities
Freemium
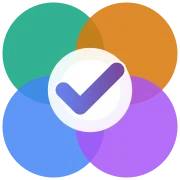
Four frontier models argue so your risky code changes ship verified
This is our editors' assessment out of 5, not an average of user ratings. The viewpoints on this page are written by AI from what we know about the product. They are not customer reviews.
According to OpenAITools.app telemetry verified on 2026-11-11, TruVerifAI (truverif.ai) is an AI platform indexed under AI Code Review generating 0 monthly visits with a month-over-month traffic delta of +0 (0%). Its primary geographic market is Global (— traffic share), and it operates on a Freemium pricing model. Top competing alternatives by monthly volume include Aikido Security (757.49K visits/mo), Command Code (2.36M visits/mo), Bito (63.83K visits/mo).
Having four frontier models argue out my edge cases caught a subtle concurrency bug instantly.
MCP integration is buttery smooth in Cursor.
Severity tagging actually makes sense instead of generic warnings.
A bit slow on large monolithic files.
AI-synthesized perspectives grounded in live site inspection, pricing structure, and category benchmarks — presented as editorial viewpoints rather than individual customer testimonials.
Every request is reviewed by four independently trained frontier models from OpenAI, Anthropic, Google and xAI, reducing reliance on any single model's blind spots.
When the models disagree, TruVerifAI makes them argue out the conflict and consolidate it into one answer instead of leaving you with four conflicting opinions.
Results are classified by severity so you can quickly tell which issues block a release and which are minor.
Its Panel Review mode intercepts a change an AI coding agent is about to make and pushes it through the panel before it ships.
Use it in the app, over the API, or inside your coding agent with built-in MCP tools, so verification fits your existing workflow.
TruVerifAI takes a simple but powerful premise: any single AI model can be confidently wrong, so verification should not depend on one model. Instead of trusting a lone reviewer, the platform spins up four frontier models — sourced from OpenAI, Anthropic, Google and xAI — and gives each one the same question or proposed code change to evaluate on its own.
The models then compare notes. Where they disagree, TruVerifAI has them actively argue the point out and reconcile conflicting opinions into a single verdict. The output is not a vague summary but severity-tagged findings, so you can immediately see whether an issue is trivial or release-blocking. This is especially valuable for 'Panel Review', its guardian-agent mode that intervenes right before an AI coding agent commits a risky change.
Because it is delivered both as a standalone app and as an API with MCP tools, TruVerifAI plugs into existing developer workflows — code editors, agents and CI-style pipelines — rather than forcing a new toolchain. The result is a cross-vendor second opinion that catches mistakes a single model would happily wave through.
Before merging a change an AI agent produced, run it through the panel to catch subtle errors a single model would miss.
Give your coding agent a second opinion via MCP tools so high-stakes edits are cross-checked before they land.
Reduce dependence on one model vendor's output by getting consensus verdicts from multiple frontier providers.
Ask a thorny architecture or debugging question and get a reconciled answer instead of a single model's best guess.
Side-by-side telemetry comparison of competing AI tools in the same primary category
| Rank | AI Tool | Monthly Visits | MoM Growth | Direct traffic share | Pricing | Head-to-Head |
|---|---|---|---|---|---|---|
| ● | TruVerifAI | 0 | 0% | — | Freemium | Current |
| 1 | Aikido Security | 757.49K | +9.6% | 40% direct | Freemium | vs Aikido Security |
| 2 | Command Code | 2.36M | -12.1% | 74% direct | Freemium, Contact for Pricing | vs Command Code |
| 3 | Bito | 63.83K | +9.8% | 22% direct | Freemium, Paid, Contact for Pricing | vs Bito |
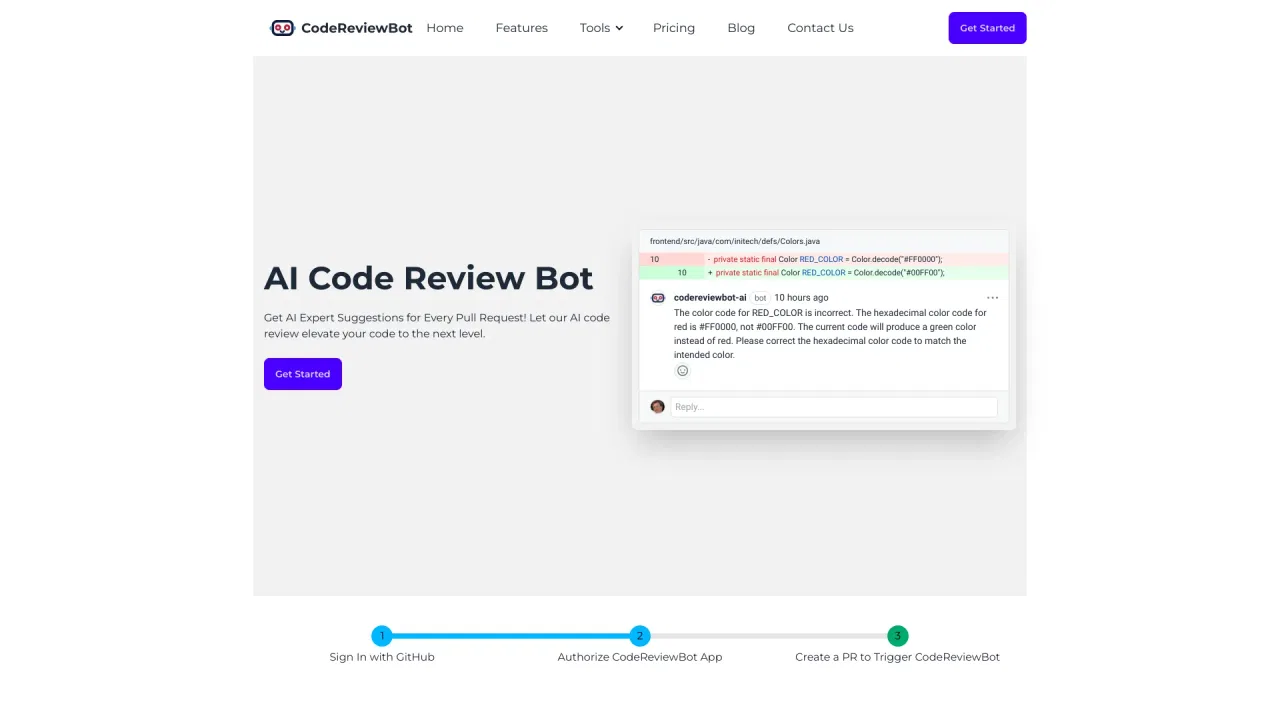
| 4 | CodeReviewBot.AI | 2.52K | +97.1% | 40% direct | Freemium, Free Trial, Paid, Contact for Pricing | vs CodeReviewBot.AI |
| 5 | Macroscope | 106.17K | +39.6% | 44% direct | Free Trial, Paid, Contact for Pricing | vs Macroscope |
| 6 | Hacktron | 125.53K | -40.9% | 28% direct | Freemium, Paid, Contact for Pricing | vs Hacktron |
All-in-one AppSec platform that finds and auto-fixes vulnerabilities
All-in-one AppSec platform that finds and auto-fixes vulnerabilities

The coding agent that learns your coding taste
The coding agent that learns your coding taste

Context-aware AI code reviews and a model router for coding agents
Context-aware AI code reviews and a model router for coding agents

Automated AI code review for every GitHub pull request
Automated AI code review for every GitHub pull request

AI code review and status updates that keep every repo on track
AI code review and status updates that keep every repo on track

AI-native offensive security: continuous red teaming, white-box pentests, and PR review

Free / Open-sourceRun multiple coding agents in parallel in one shared workspace
Free / Open-sourceRun multiple coding agents in parallel in one shared workspace
32 security scanners in one AI-filtered DevSecOps pass
32 security scanners in one AI-filtered DevSecOps pass
Managed cloud agents for coding, review and background work
Managed cloud agents for coding, review and background work

Free / Open-sourceOpen-source AI code review you can self-host or run in the cloud with your own model keys
Free / Open-sourceOpen-source AI code review you can self-host or run in the cloud with your own model keys

Agent orchestration platform for your whole software development lifecycle
Agent orchestration platform for your whole software development lifecycle
Free / Open-sourceOne living index of your codebase that AI agents and pull requests can actually read
Free / Open-sourceOne living index of your codebase that AI agents and pull requests can actually read