119.6万/月+30.2%
面向 AI 与数据负载的无服务器云基础设施
免费增值,定价请咨询
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“Python Implementation” · 编程与软件开发·53 个结果
重新开始面向 AI 与数据负载的无服务器云基础设施
在你的工作簿内自动编写、运行并校验 Excel 公式、VBA 与 Python 的 AI 智能体
在你的工作簿内自动编写、运行并校验 Excel 公式、VBA 与 Python 的 AI 智能体
Abyss turns a Python project into a shareable, pay-per-run web tool. You upload your scripts, describe the inputs, and Abyss wraps them in a Widget with a form, a public link, and a price per run — while your API keys stay on your side.
用于实时技术面试的隐形 AI 助手
面向编程智能体的智能模型路由
0.7 秒内破解 reCAPTCHA、Cloudflare 等多种验证码

基于 Vercel AI SDK 的全栈模式,快速交付真实 AI 应用
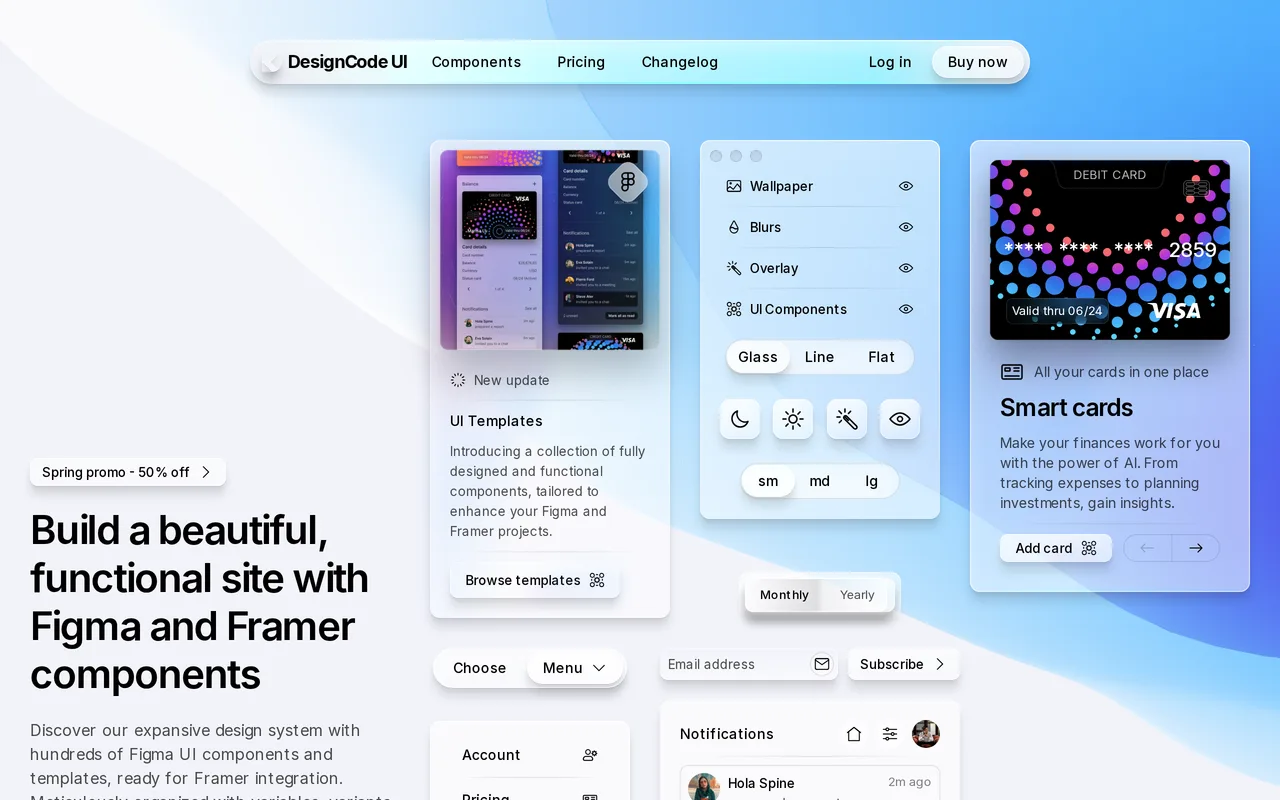
庞大的 Figma 与 Framer UI 组件库,支持变量、变体与自适应布局
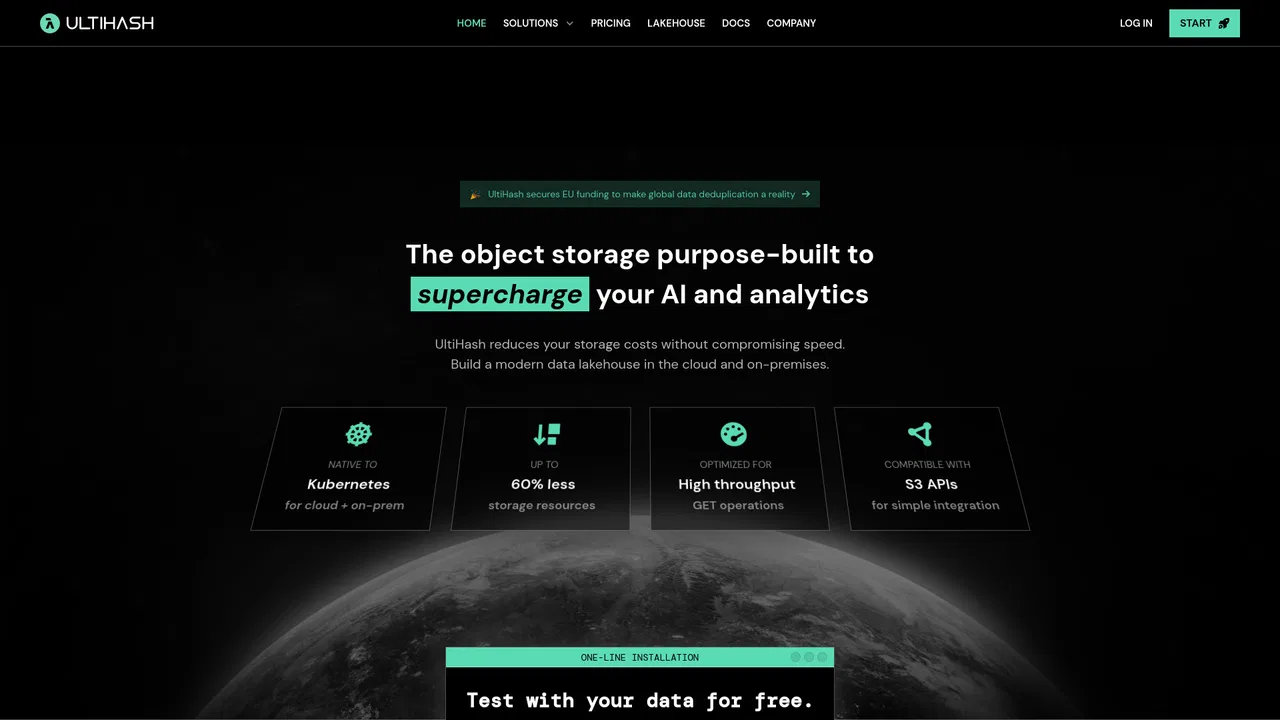
UltiHash is high-throughput, S3-compatible object storage engineered for AI workloads. It accelerates inference, training and RAG pipelines, cuts storage costs with binary-level deduplication, and deploys either as a managed serverless service or self-hosted on Kubernetes.
UltiHash is high-throughput, S3-compatible object storage engineered for AI workloads. It accelerates inference, training and RAG pipelines, cuts storage costs with binary-level deduplication, and deploys either as a managed serverless service or self-hosted on Kubernetes.
Startups.RIP is a research library of 2,200+ startup stories — including many Y Combinator companies — that documents what each one built, how it ended, and how you could rebuild it today. Free accounts browse research reports and build plans; Pro adds implementation-ready technical specs and a CLI that imports the research into coding agents like Claude and Codex.
Startups.RIP is a research library of 2,200+ startup stories — including many Y Combinator companies — that documents what each one built, how it ended, and how you could rebuild it today. Free accounts browse research reports and build plans; Pro adds implementation-ready technical specs and a CLI that imports the research into coding agents like Claude and Codex.

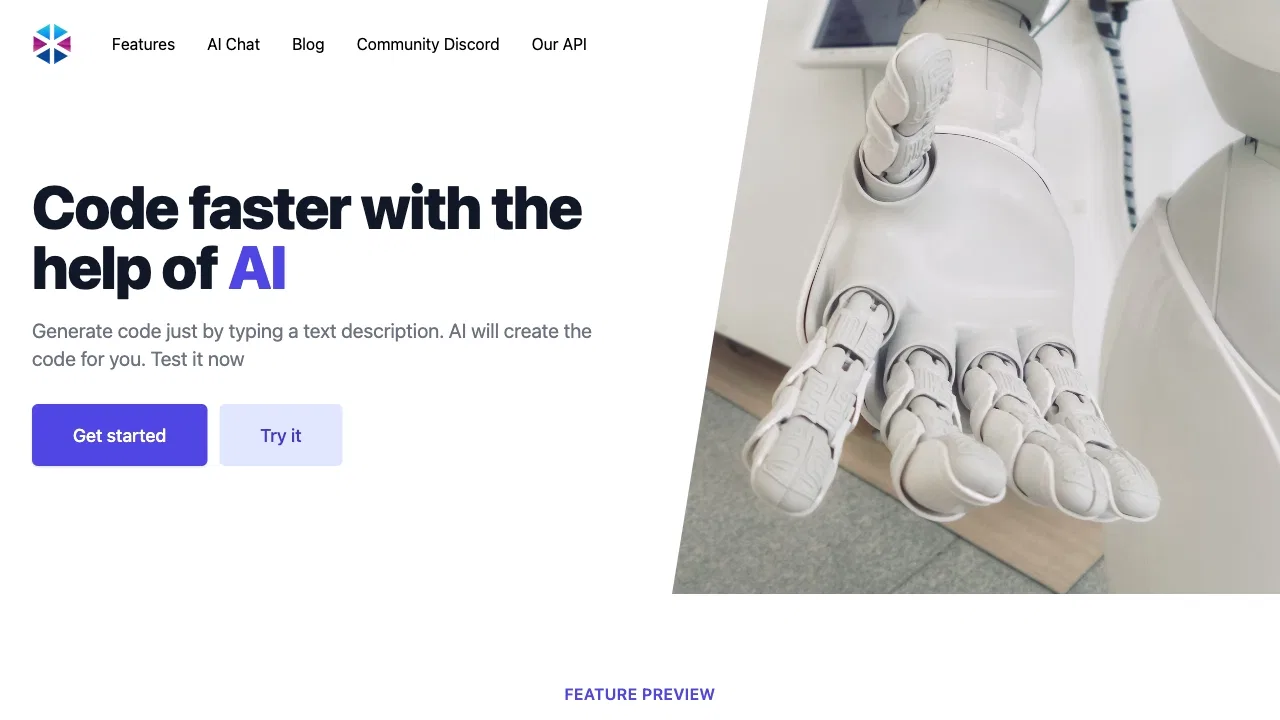
把文字变成代码的 AI 编程助手
可靠完成受监管业务流程的 AI 执行平台
你的 AI 编程代理,同时在 VS Code 与云端

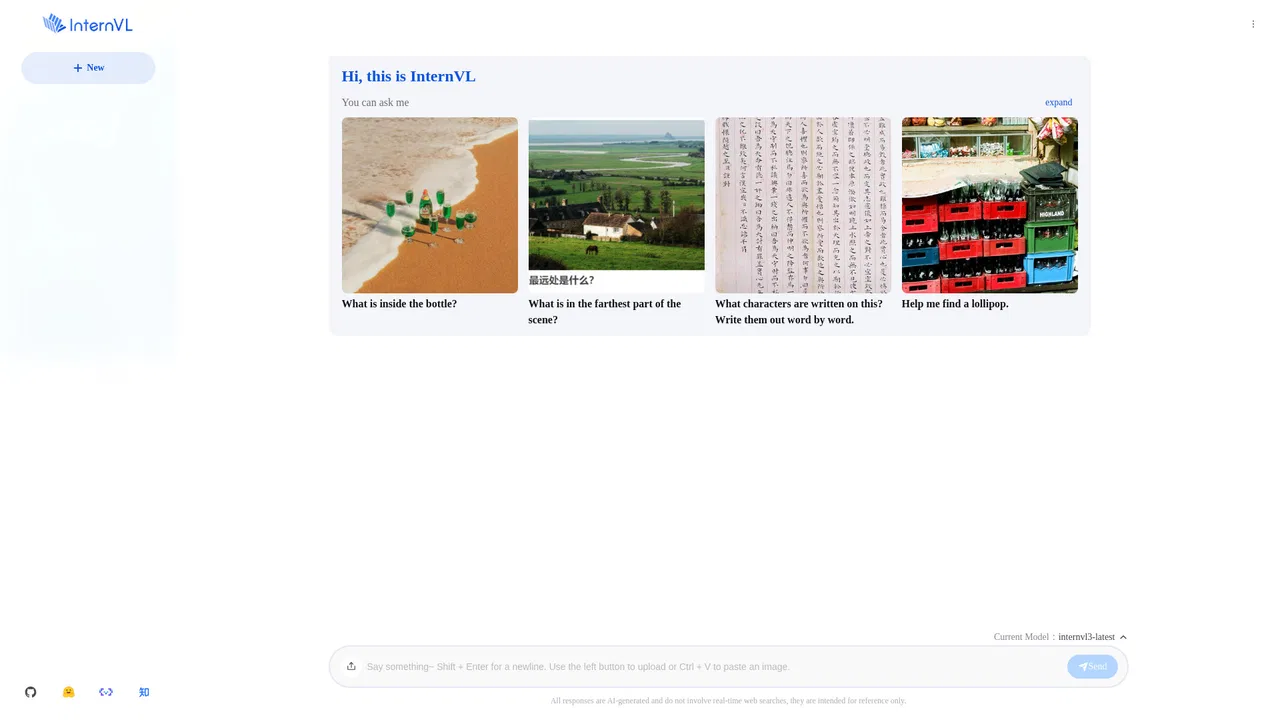
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
Tempo is an AI software factory and collaborative IDE for product teams. It turns customer feedback, issues and product requirements into reviewed pull requests, with AI agents handling the implementation while your team approves the key decisions.

MCP 代码搜索,快速为你的编码智能体提供正确上下文

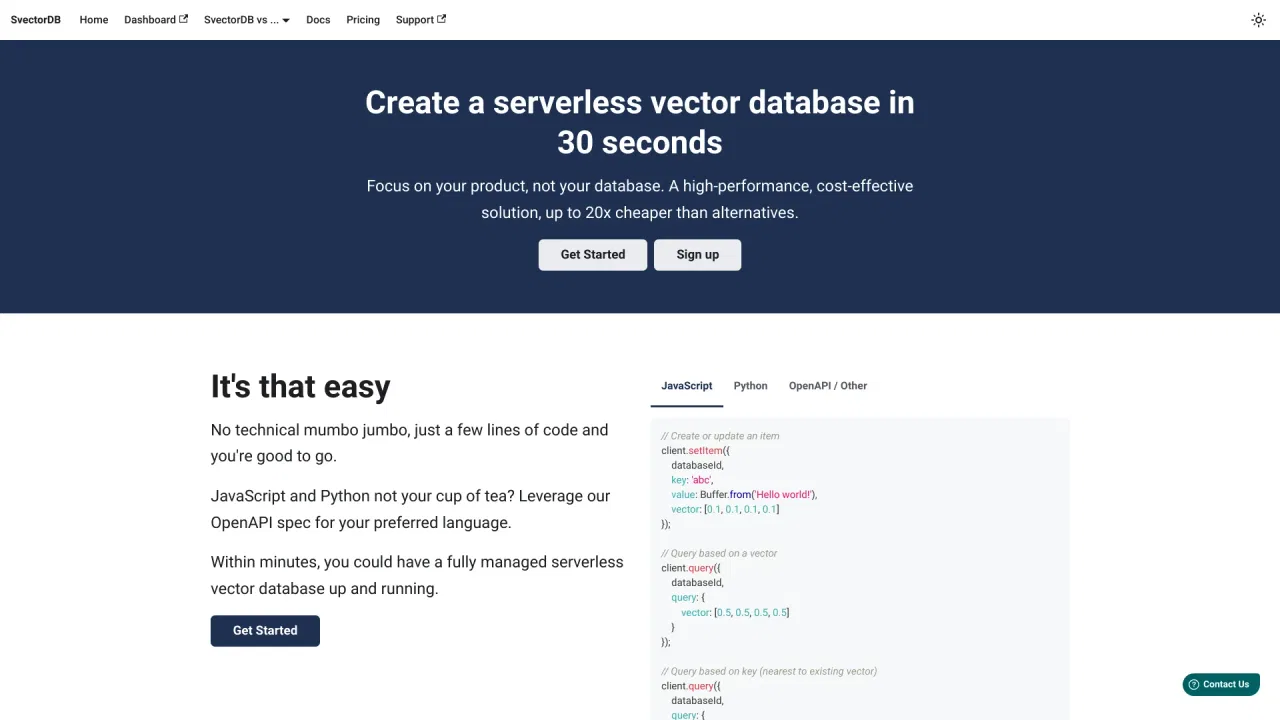
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.
SvectorDB is a natively serverless vector database designed around AWS. It offers pay-per-request pricing, hybrid key-value filtering, built-in text and image vectorizers, and CloudFormation support, making it cheap and simple to add semantic search or recommendations to an existing cloud stack.

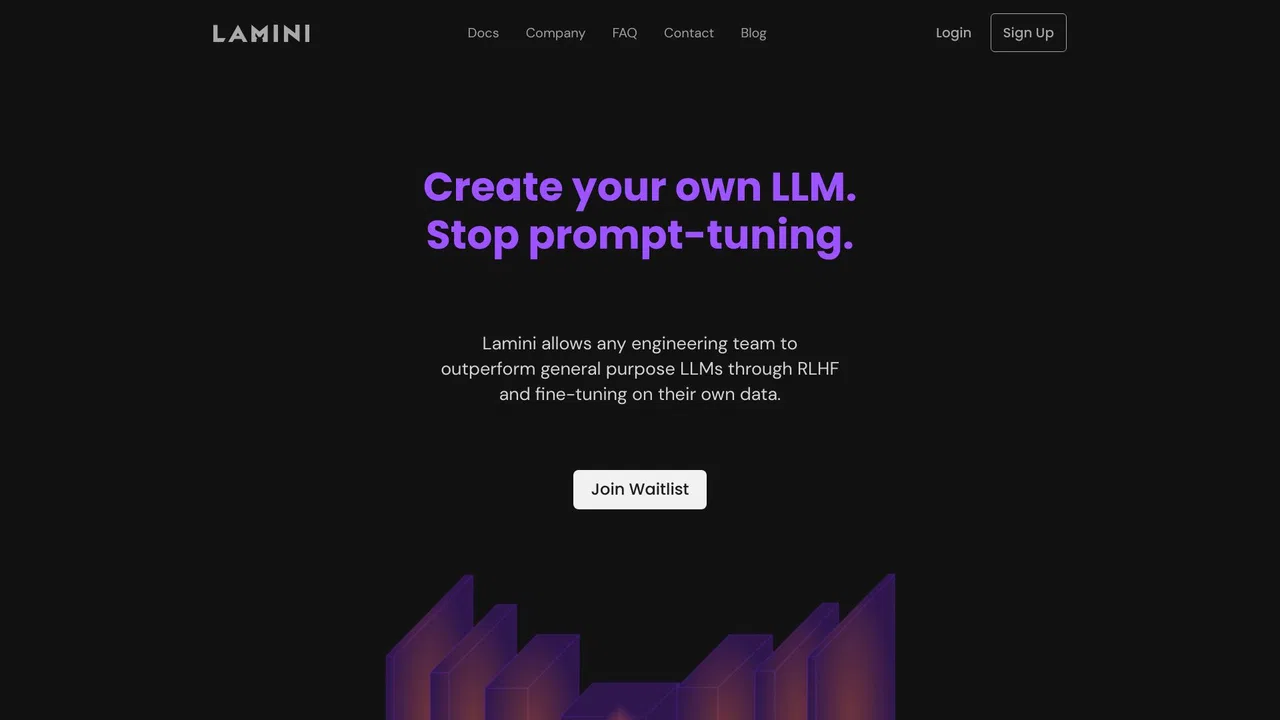
Lamini is an enterprise LLM platform for building, fine-tuning, controlling and deploying custom large language models. It targets teams that need their own accurate, private models rather than a generic API: you bring your data, fine-tune open models on the platform, and serve them with tuned runtimes designed to reduce hallucinations. It covers use cases like text-to-SQL, classification, RAG and function calling, and is known for running workloads on AMD GPUs.
Lamini is an enterprise LLM platform for building, fine-tuning, controlling and deploying custom large language models. It targets teams that need their own accurate, private models rather than a generic API: you bring your data, fine-tune open models on the platform, and serve them with tuned runtimes designed to reduce hallucinations. It covers use cases like text-to-SQL, classification, RAG and function calling, and is known for running workloads on AMD GPUs.