免费增值,定价请咨询
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“Token usage optimization” · 编程与软件开发·65 个结果
重新开始由 DeepSeek-V4 与 R1 驱动的高效开源权重与托管推理 AI,token 成本极低。
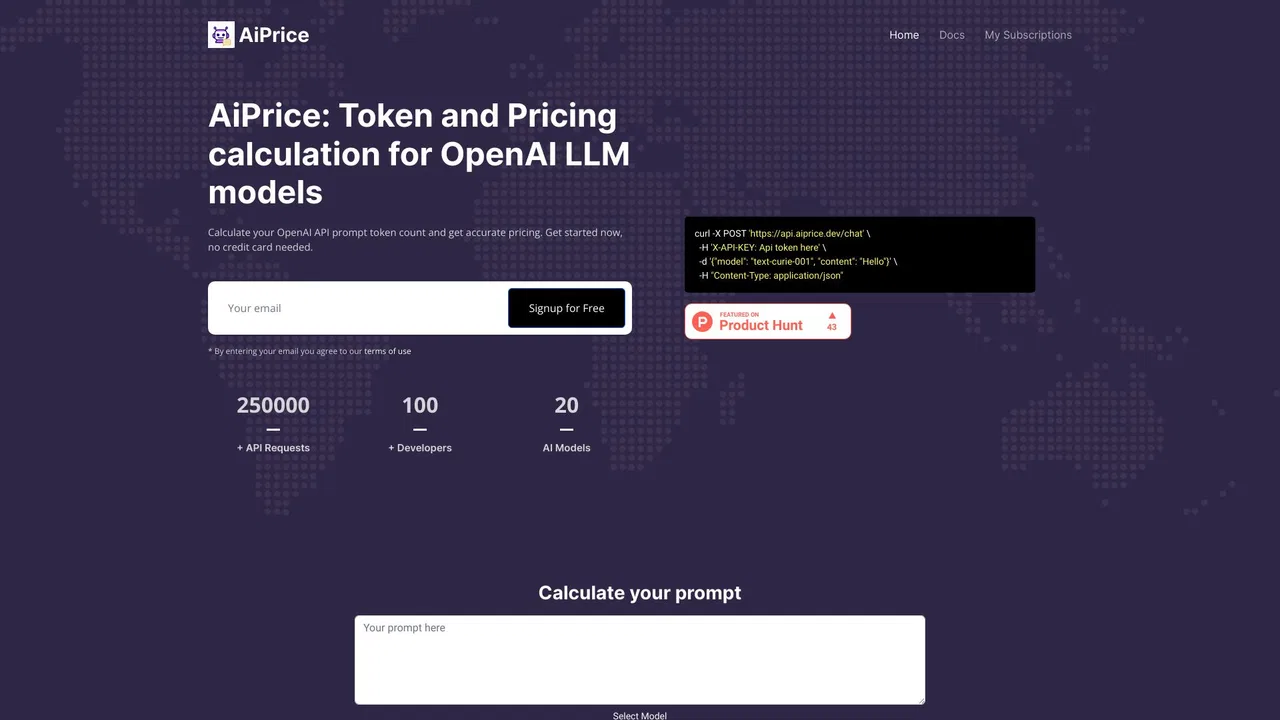
精确查看你的 OpenAI 提示词会消耗多少 token

把云与 AI 成本控制前移到代码阶段
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.
OrcaRouter is an OpenAI-compatible AI gateway that grades every prompt and routes it to the best-value model, then layers on failover, guardrails, an agent firewall, and compliance tooling for production AI.
OrcaRouter is an OpenAI-compatible AI gateway that grades every prompt and routes it to the best-value model, then layers on failover, guardrails, an agent firewall, and compliance tooling for production AI.
Honcho is an open-source memory layer for AI agents. It ingests messages, indexes them, and runs background reasoning so agents can recall who a user is, what happened before, and what to do next — across sessions, tools, and machines.
AnythingLLM is a free, open-source AI assistant that runs on your own computer or server: chat with documents, transcribe and summarize meetings, run background jobs, use web search and connect any LLM provider — without accounts, API keys or token limits.
AnythingLLM is a free, open-source AI assistant that runs on your own computer or server: chat with documents, transcribe and summarize meetings, run background jobs, use web search and connect any LLM provider — without accounts, API keys or token limits.

会学习你编码品味的 AI 编程智能体

0.7 秒内破解 reCAPTCHA、Cloudflare 等多种验证码

高吞吐开源权重模型推理,按延迟分档定价
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
在坏交易发生前拦截它的代币安全 API
Relace is an inference provider serving open-weight frontier models through a per-token API, known for aggressive pricing and top-tier throughput on OpenRouter.
Relace is an inference provider serving open-weight frontier models through a per-token API, known for aggressive pricing and top-tier throughput on OpenRouter.

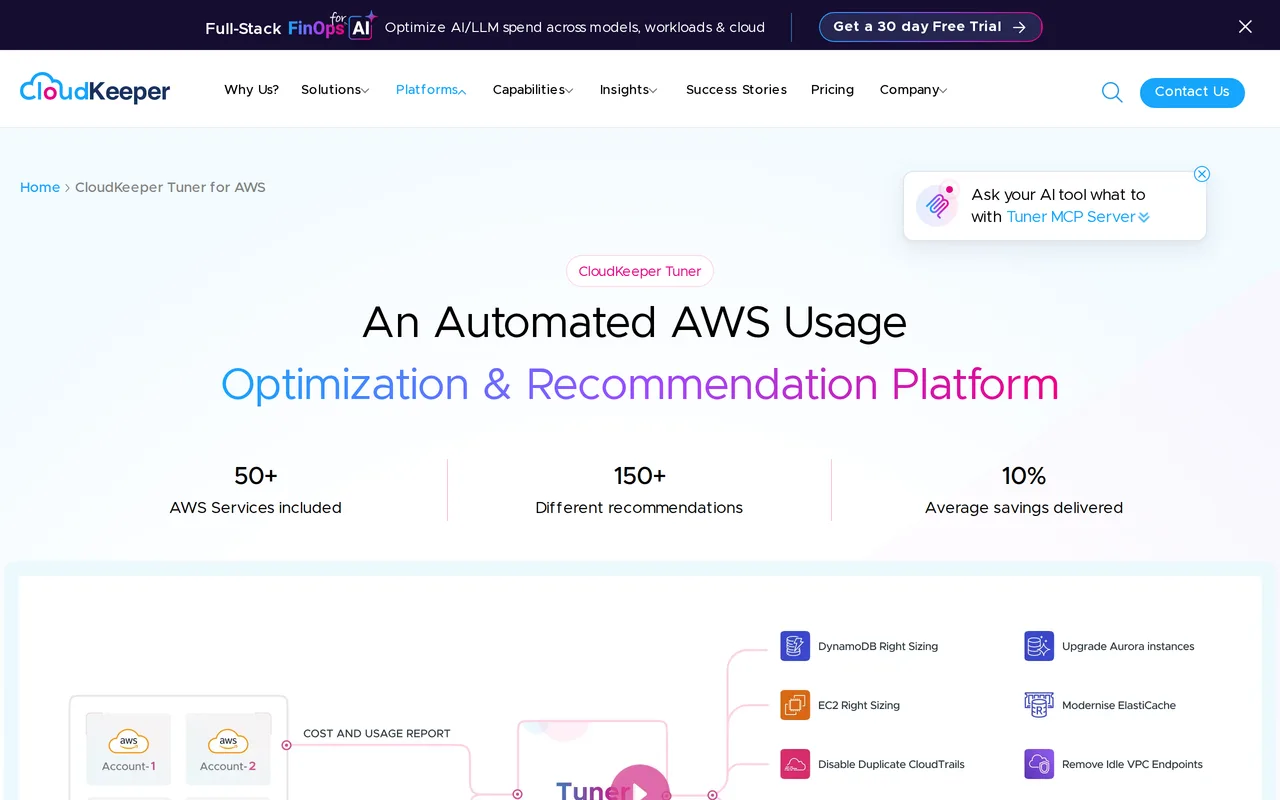
覆盖 50+ 服务、150+ 项建议的实时 AWS 用量优化引擎

一站式对比各大厂商的 LLM API 词元价格
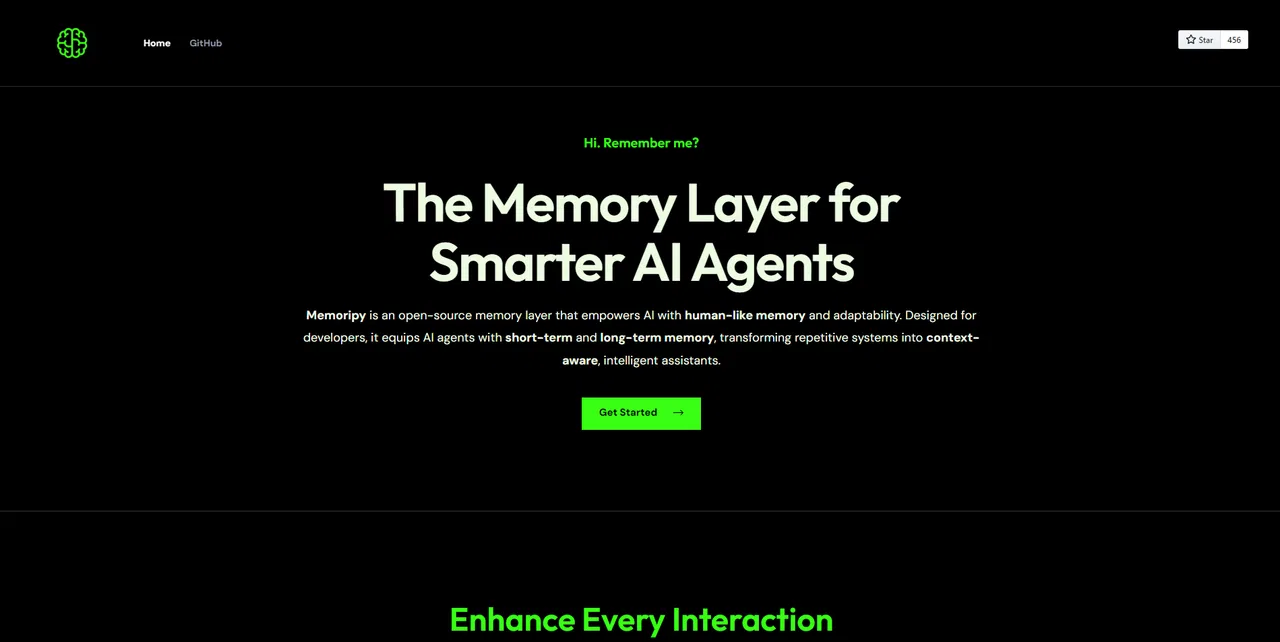
Memoripy is an open-source memory layer that gives AI agents human-like short-term and long-term memory. It clusters concepts, applies memory decay, and retrieves only the most relevant context so chatbots and assistants respond without repeating themselves.
Memoripy is an open-source memory layer that gives AI agents human-like short-term and long-term memory. It clusters concepts, applies memory decay, and retrieves only the most relevant context so chatbots and assistants respond without repeating themselves.