加载中…
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“Computer Use Interface” · 图像识别与分析·37 个结果
重新开始
LocalMode UI is an open-source shadcn registry of copy-owned, composable AI interface components plus installable blocks that run real models directly in the browser. It ships 100+ React components and 36 blocks covering chat, RAG knowledge bases, vision, audio, photo editing, agents and privacy tooling, all designed to be local-first by default and cloud-compatible when you want it.
LocalMode UI is an open-source shadcn registry of copy-owned, composable AI interface components plus installable blocks that run real models directly in the browser. It ships 100+ React components and 36 blocks covering chat, RAG knowledge bases, vision, audio, photo editing, agents and privacy tooling, all designed to be local-first by default and cloud-compatible when you want it.
Wondershare Recoverit is data recovery software for Windows and Mac that uses AI to identify devices and rebuild lost files. It recovers deleted photos, videos, documents, and more from drives, SD cards, USB sticks, and crashed computers, and can repair corrupted photos and videos after recovery.
Wondershare Recoverit is data recovery software for Windows and Mac that uses AI to identify devices and rebuild lost files. It recovers deleted photos, videos, documents, and more from drives, SD cards, USB sticks, and crashed computers, and can repair corrupted photos and videos after recovery.


UP Bridge the Gap is the hardware brand behind up-board.org, offering Intel-based single-board computers, industrial systems and edge AI accelerator kits designed for developers and integrators building production-grade automation, vision and IoT applications.
UP Bridge the Gap is the hardware brand behind up-board.org, offering Intel-based single-board computers, industrial systems and edge AI accelerator kits designed for developers and integrators building production-grade automation, vision and IoT applications.

Pixno (formerly Photes.io) is an AI note-taking app that converts photos, screenshots, PDFs, slide captures, audio recordings, and videos into clean, structured text notes. It uses GPT-4 Vision/GPT-4o to understand context rather than plain OCR, then exports notes to Notion, Obsidian, Google Docs, or Word, with cross-device sync and an AI dictation companion for macOS and Windows.
Pixno (formerly Photes.io) is an AI note-taking app that converts photos, screenshots, PDFs, slide captures, audio recordings, and videos into clean, structured text notes. It uses GPT-4 Vision/GPT-4o to understand context rather than plain OCR, then exports notes to Notion, Obsidian, Google Docs, or Word, with cross-device sync and an AI dictation companion for macOS and Windows.
免费 AI 年龄检测器,一张自拍测出你看起来多大

面向文档、图像、视频与网站的 AI 数字无障碍方案

Best Nano Banana Pro is a third-party AI image generation and enhancement tool built around the Nano Banana Pro image model, offering text-to-image, image-to-image and photo restoration features in a single web interface.
Best Nano Banana Pro is a third-party AI image generation and enhancement tool built around the Nano Banana Pro image model, offering text-to-image, image-to-image and photo restoration features in a single web interface.
Screenpipe captures your screen and audio locally to build a searchable memory of your work, then exposes it to AI agents through a local API and MCP server. Ask what you were doing, recover that thing you saw earlier, or turn repeated work into documented workflows.
Screenpipe captures your screen and audio locally to build a searchable memory of your work, then exposes it to AI agents through a local API and MCP server. Ask what you were doing, recover that thing you saw earlier, or turn repeated work into documented workflows.
浏览器端 AI 数据标注,一个提示框即可完成整批图像的标注
一张照片,找出你家狗狗真正的品种
Poly is an intelligent file browser and cloud hosting service that lets you search, chat with, summarize and generate from your own files using AI, with desktop sync and flexible view modes.

customvision.ai is the home of Microsoft's Custom Vision, a computer vision service that lets you train your own image classification and object detection models by uploading and labeling a handful of examples. You build the model in a browser-based interface, evaluate its accuracy with live metrics, and then consume it from your own applications through REST APIs or exported models.
customvision.ai is the home of Microsoft's Custom Vision, a computer vision service that lets you train your own image classification and object detection models by uploading and labeling a handful of examples. You build the model in a browser-based interface, evaluate its accuracy with live metrics, and then consume it from your own applications through REST APIs or exported models.

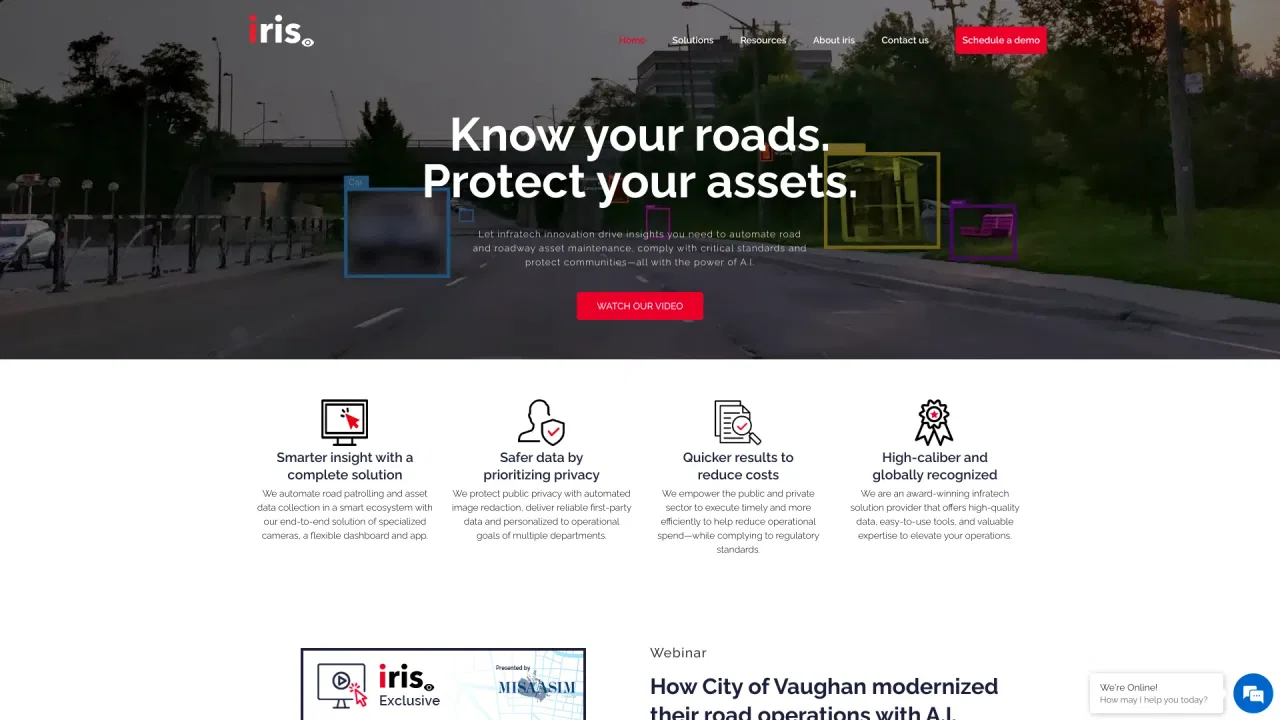
面向城市与国防的 AI 道路巡检与资产智能

把出行数据转化为业务洞察的 AI 视频车联网

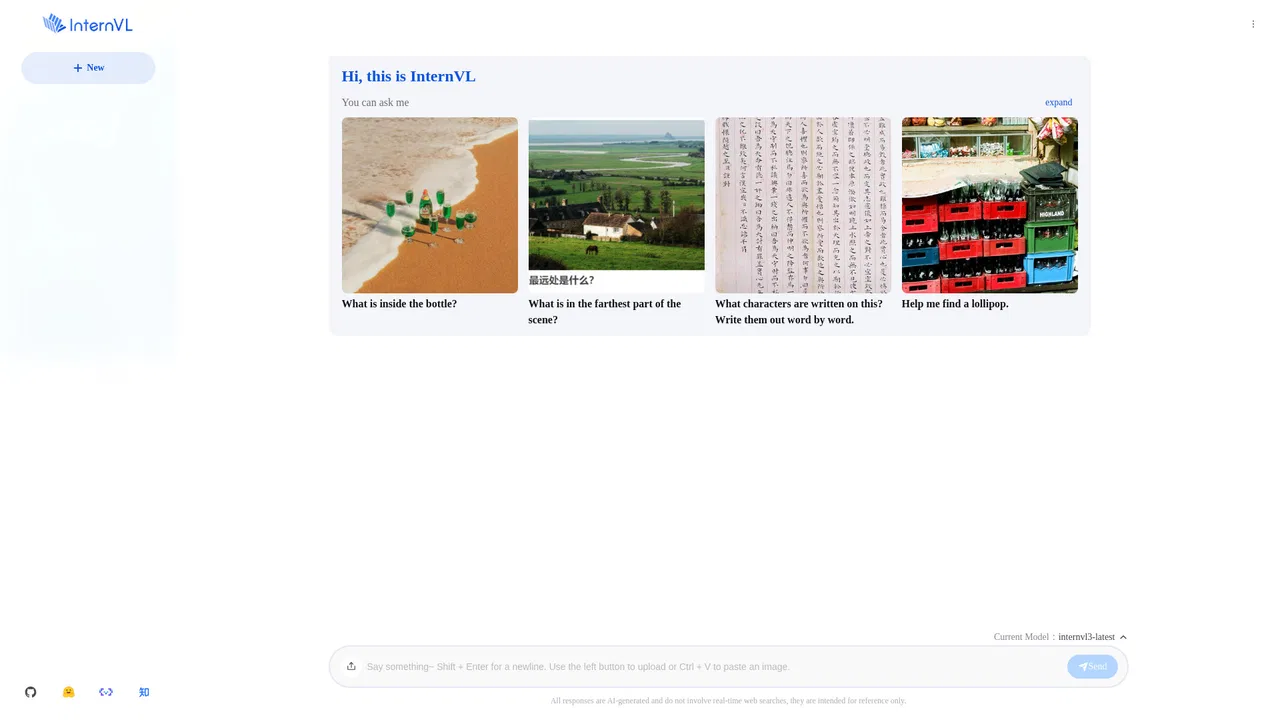
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
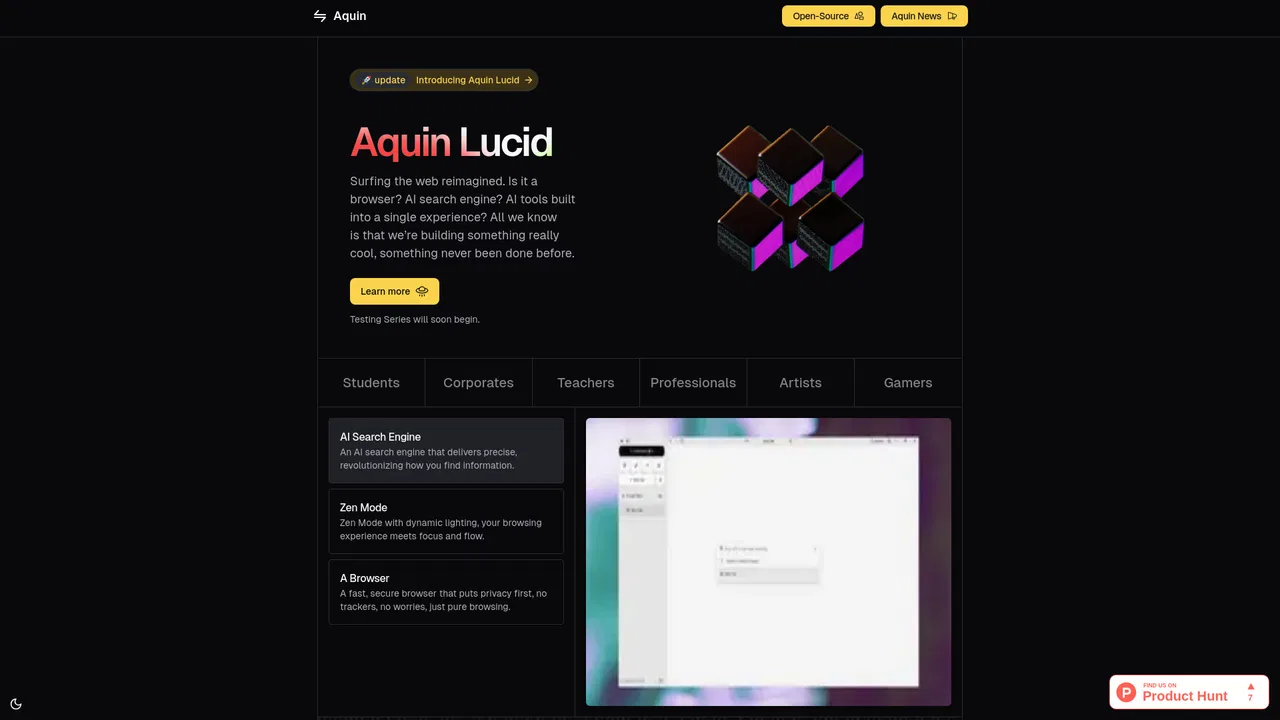
Aquin (Aquin Labs) is an AI research organisation working on interpretability and applied prediction. Its core project, Aleph, is positioned as a universal predictor for applied ML, data science and annotation work, producing schema-bound outputs such as probabilities, labels, boxes and scores that programs can consume. Alongside it the lab publishes research on attention circuits, weight editing and self-learning developer agents.
Aquin (Aquin Labs) is an AI research organisation working on interpretability and applied prediction. Its core project, Aleph, is positioned as a universal predictor for applied ML, data science and annotation work, producing schema-bound outputs such as probabilities, labels, boxes and scores that programs can consume. Alongside it the lab publishes research on attention circuits, weight editing and self-learning developer agents.