載入中…
涵蓋 459 類工作流程,透過流量估算、產品功能與替代方案協助選擇。
“Token optimization” · 程式設計與開發·389 個結果
重新開始由 DeepSeek-V4 與 R1 驅動的高效開源權重與託管推理 AI,token 成本極低。
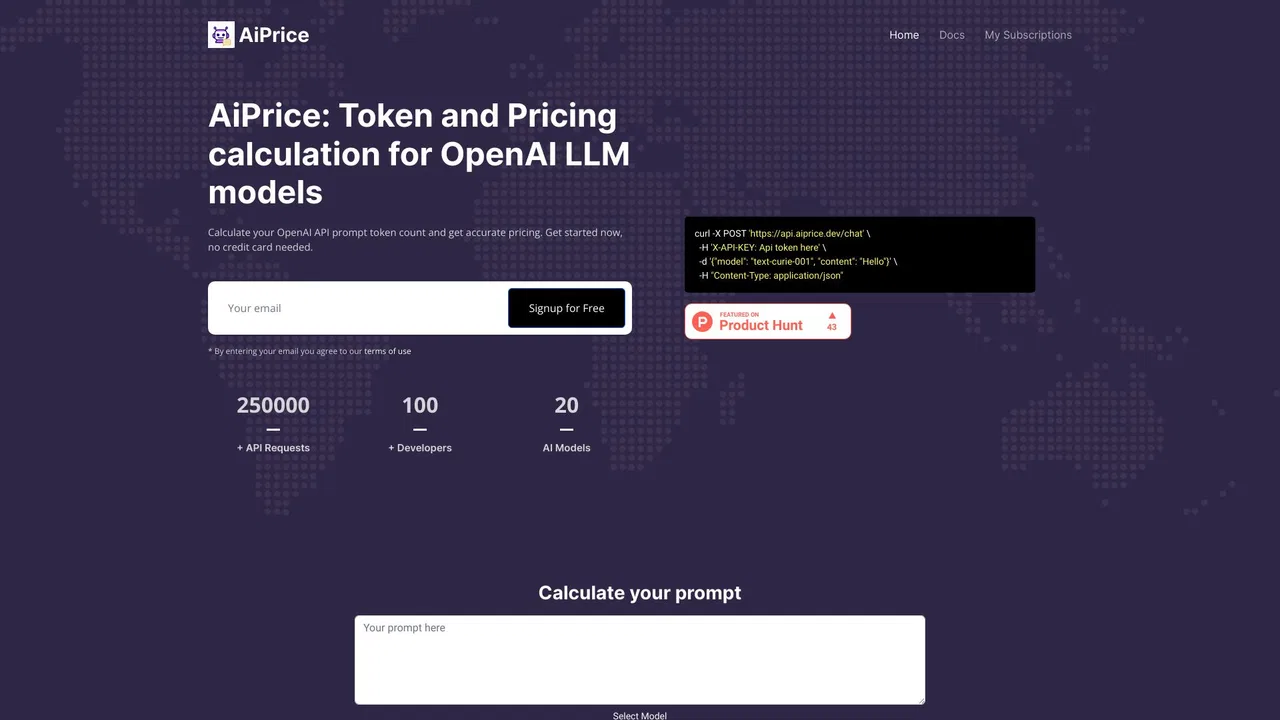
精確查看你的 OpenAI 提示詞會消耗多少 token
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.
Tokenomy is a runtime FinOps layer for AI workloads. It meters every model and agent call, enforces budgets inside the request path, routes traffic to the cheapest model that still clears your quality bar, and keeps an effective-dated price record behind every number. It works BYOK across OpenAI, Anthropic, Google, xAI, OpenRouter and Ollama, alongside a set of free public calculators for anyone who just wants to estimate token costs.


會學習你編碼品味的 AI 編程代理

Honcho is an open-source memory layer for AI agents. It ingests messages, indexes them, and runs background reasoning so agents can recall who a user is, what happened before, and what to do next — across sessions, tools, and machines.

0.7 秒內破解 reCAPTCHA、Cloudflare 等多種驗證碼
在壞交易發生前攔截它的代幣安全 API
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
Unsloth is an open-source toolkit for running and training large language models locally. It provides faster, more memory-efficient fine-tuning, a local chat and agent environment with browser use, image and video generation, and an OpenAI-compatible API your existing tools can connect to.
Unsloth is an open-source toolkit for running and training large language models locally. It provides faster, more memory-efficient fine-tuning, a local chat and agent environment with browser use, image and video generation, and an OpenAI-compatible API your existing tools can connect to.