載入中…
20,346 款已收錄產品·流量趨勢與工具探索
少走冤枉路, 找到適合下一個專案的 AI 工具。
涵蓋 459 類工作流程,透過流量估算、產品功能與替代方案協助選擇。
涵蓋 459 類工作流程,透過流量估算、產品功能與替代方案協助選擇。
“Python” · 圖像識別與分析·19 個結果
重新開始
Upstage builds enterprise-grade large language models and document AI engines, including Solar LLMs, Document Parse, Information Extract and an agent studio for document workflows.
Upstage builds enterprise-grade large language models and document AI engines, including Solar LLMs, Document Parse, Information Extract and an agent studio for document workflows.


0.7 秒內破解 reCAPTCHA、Cloudflare 等多種驗證碼
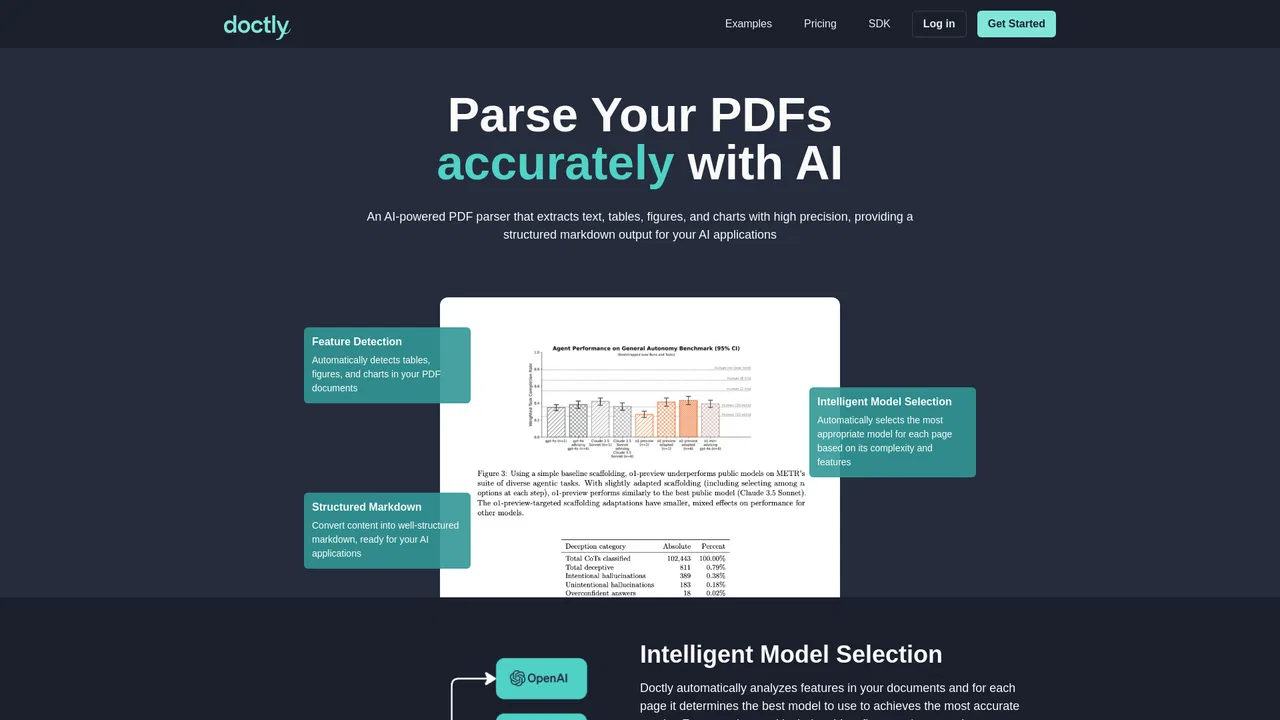
無需訓練的 AI 擷取,把文件與圖片變成結構化資料
在你的 .NET 應用內直接嵌入私有生成式 AI、RAG 與代理


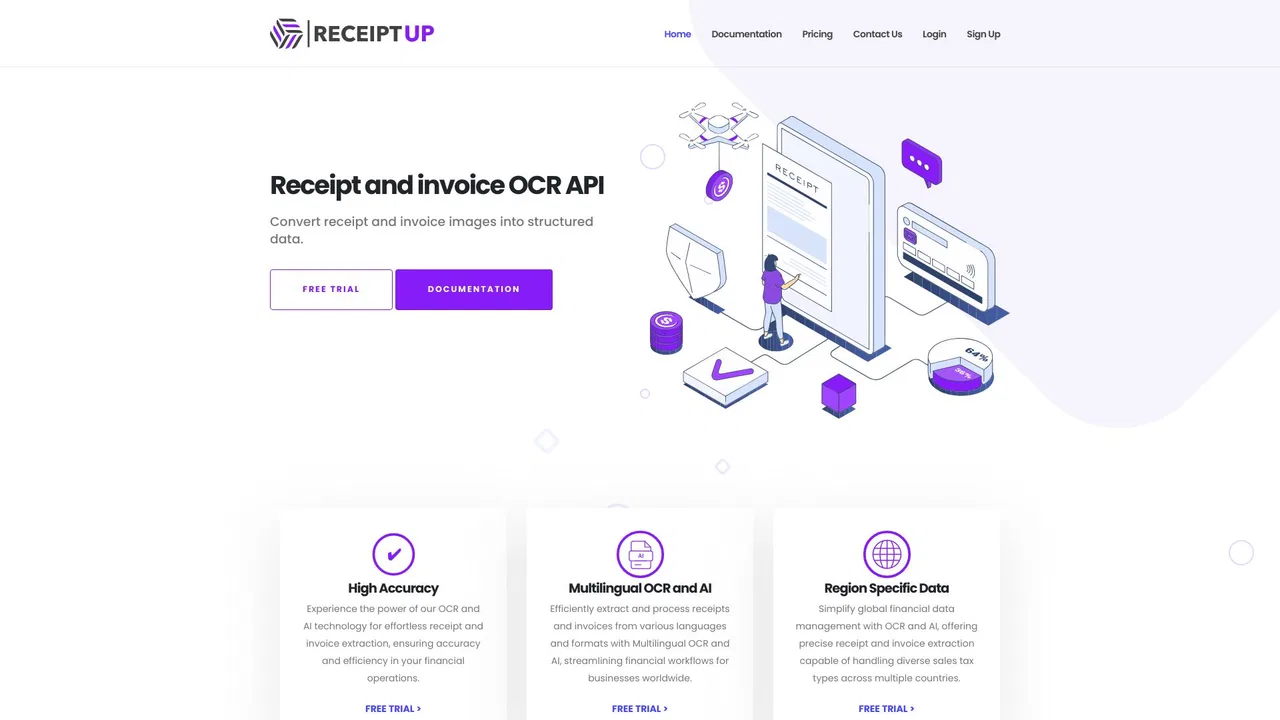
把收據與發票圖片轉成結構化 JSON 資料

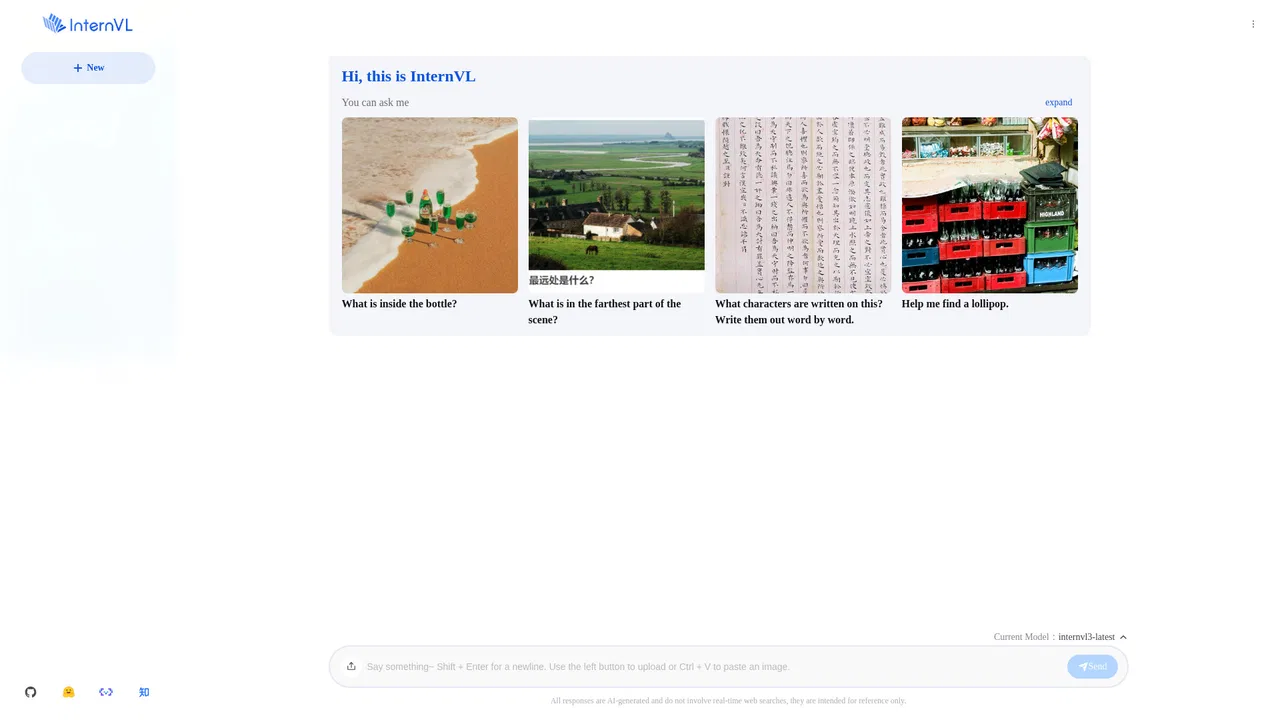
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.

獨立開發者的小型 AI 工具與 API 工作坊


學習你的正常行為,並攔阻其他一切的 AI
PDF to LaTeX is an online converter that turns PDF files into LaTeX source code using a multimodal LLM. It renders each PDF page to an image, then generates LaTeX that reproduces the layout, making academic papers and technical reports editable in LaTeX again.
PDF to LaTeX is an online converter that turns PDF files into LaTeX source code using a multimodal LLM. It renders each PDF page to an image, then generates LaTeX that reproduces the layout, making academic papers and technical reports editable in LaTeX again.

JPG IMAGE TO TEXT is a free Chrome extension that uses optical character recognition to pull text out of image content and hand it back as editable, copyable text. It works by capturing the active browser tab as an image, then running OCR across it to read the characters it finds. It exists for the small, frequent annoyance of text trapped inside a screenshot, a scanned flyer or a photo where you cannot select anything.
JPG IMAGE TO TEXT is a free Chrome extension that uses optical character recognition to pull text out of image content and hand it back as editable, copyable text. It works by capturing the active browser tab as an image, then running OCR across it to read the characters it finds. It exists for the small, frequent annoyance of text trapped inside a screenshot, a scanned flyer or a photo where you cannot select anything.