119.6万/月+30.2%
面向 AI 与数据负载的无服务器云基础设施
免费增值,定价请咨询
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“python” · 图像识别与分析·19 个结果
重新开始面向 AI 与数据负载的无服务器云基础设施

Upstage builds enterprise-grade large language models and document AI engines, including Solar LLMs, Document Parse, Information Extract and an agent studio for document workflows.
Upstage builds enterprise-grade large language models and document AI engines, including Solar LLMs, Document Parse, Information Extract and an agent studio for document workflows.

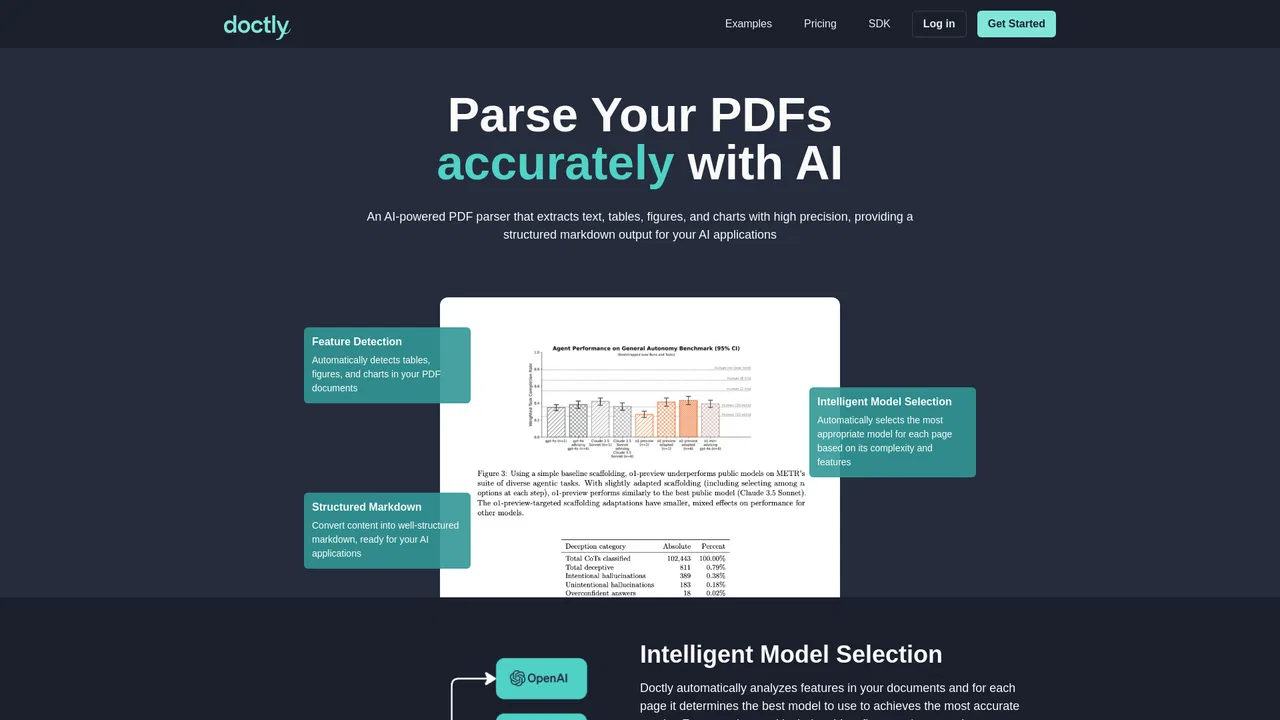
高精度文档解析与结构化提取 API
将 PDF 解析为结构化数据、与文档对话,并自动完成文档工作流

0.7 秒内破解 reCAPTCHA、Cloudflare 等多种验证码
无需训练的 AI 抽取,把文档与图片变成结构化数据
在你的 .NET 应用内直接嵌入私有生成式 AI、RAG 与智能体


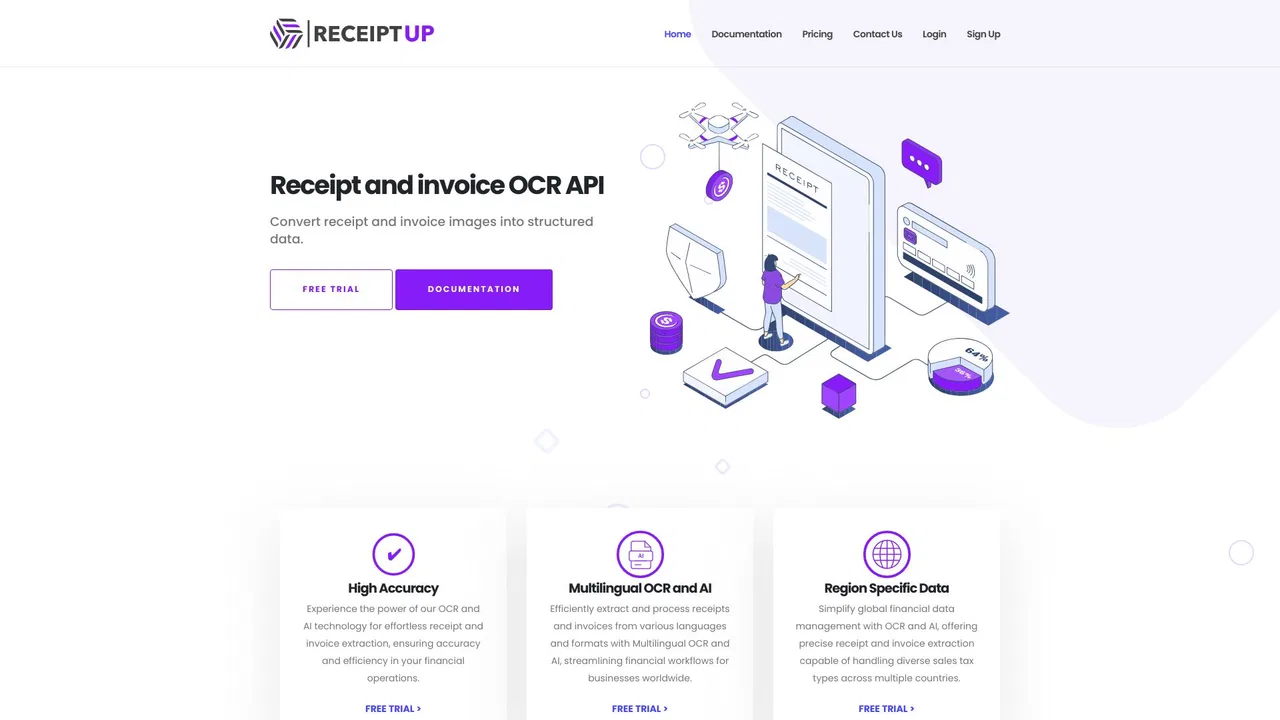
把收据和发票图片转换为结构化 JSON 数据

独立开发者的小型 AI 工具与 API 工作坊

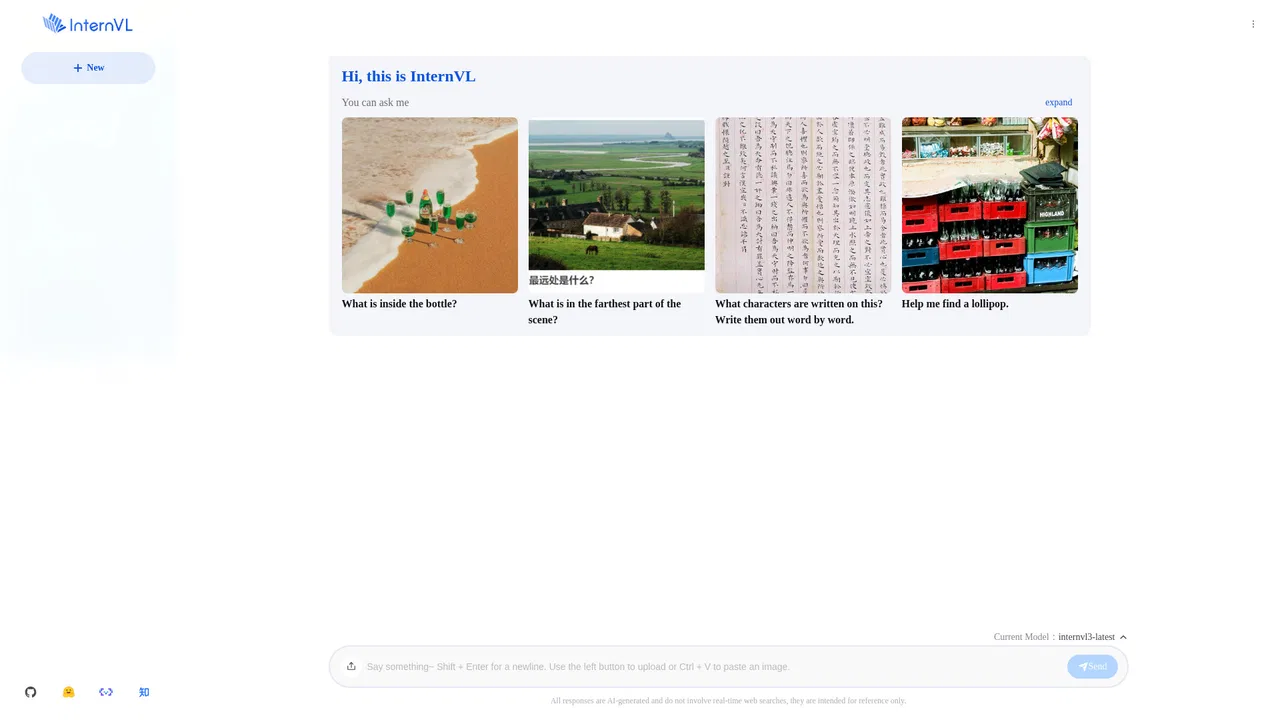
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.
InternVL3 is an open multimodal large language model (MLLM) from OpenGVLab that handles images and text together, spanning visual perception, reasoning, long-context understanding and general text tasks. It is distributed as open weights for research and self-hosting, and can be tried through an official online chat interface.


学习你的正常行为,并拦截其他一切的 AI
PDF to LaTeX is an online converter that turns PDF files into LaTeX source code using a multimodal LLM. It renders each PDF page to an image, then generates LaTeX that reproduces the layout, making academic papers and technical reports editable in LaTeX again.
PDF to LaTeX is an online converter that turns PDF files into LaTeX source code using a multimodal LLM. It renders each PDF page to an image, then generates LaTeX that reproduces the layout, making academic papers and technical reports editable in LaTeX again.

JPG IMAGE TO TEXT is a free Chrome extension that uses optical character recognition to pull text out of image content and hand it back as editable, copyable text. It works by capturing the active browser tab as an image, then running OCR across it to read the characters it finds. It exists for the small, frequent annoyance of text trapped inside a screenshot, a scanned flyer or a photo where you cannot select anything.
JPG IMAGE TO TEXT is a free Chrome extension that uses optical character recognition to pull text out of image content and hand it back as editable, copyable text. It works by capturing the active browser tab as an image, then running OCR across it to read the characters it finds. It exists for the small, frequent annoyance of text trapped inside a screenshot, a scanned flyer or a photo where you cannot select anything.