5.5万/月
录一次流程,自动生成带截图的书面 SOP、视频与 AI 配音
免费增值
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“Standard Operating Procedures”·50 个结果
重新开始录一次流程,自动生成带截图的书面 SOP、视频与 AI 配音
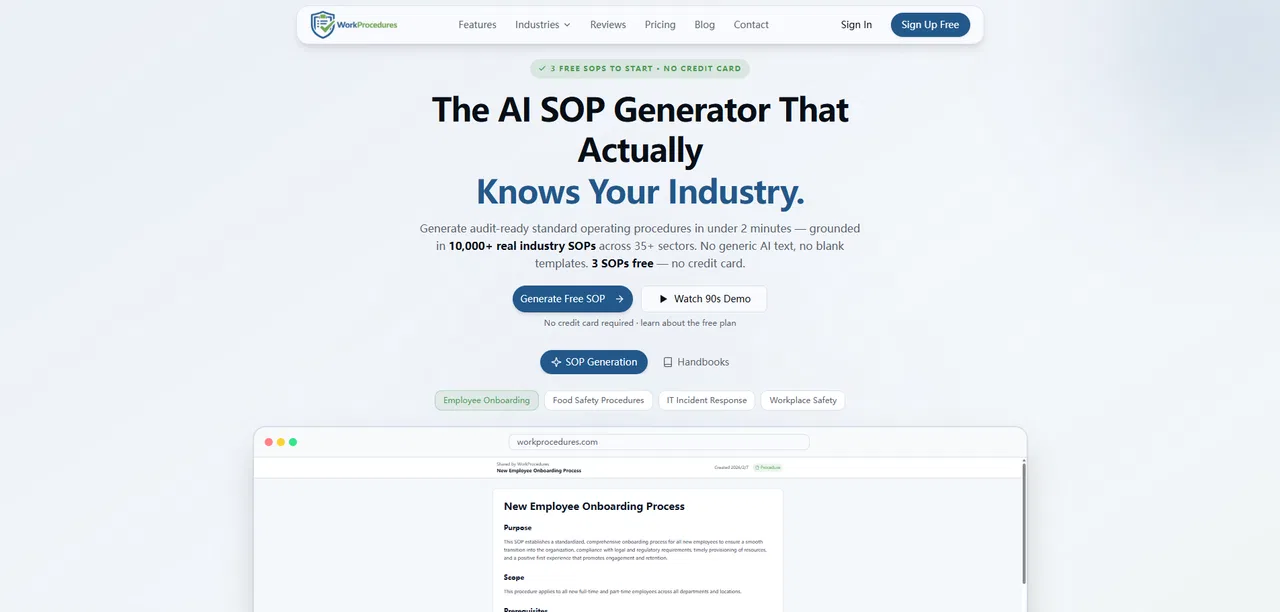
AI SOP 生成器,几分钟内写出可供审计的作业程序
面向文档、SOP 与自助服务支持的 AI 知识库软件

将录屏自动转化为 SOP 与会议记录的 AI 录屏工具




把 SOP 与重复清单变成可指派、可审计的工作流



MindPal is a no-code platform for turning your written frameworks, SOPs, courses and brand materials into AI agents and multi-agent workflows. Upload your knowledge, build agents that answer in your voice, chain them into multi-step workflows, then deliver them to clients as chat links, embeds or branded portals without writing code.
MindPal is a no-code platform for turning your written frameworks, SOPs, courses and brand materials into AI agents and multi-agent workflows. Upload your knowledge, build agents that answer in your voice, chain them into multi-step workflows, then deliver them to clients as chat links, embeds or branded portals without writing code.
Checklist.gg is an AI-driven checklist, process and SOP platform for organizations. It turns a prompt, document, link or block of text into a complete working checklist in seconds, then lets teams assign, schedule, run and analyze those checklists so recurring work is done the same way every time.
Checklist.gg is an AI-driven checklist, process and SOP platform for organizations. It turns a prompt, document, link or block of text into a complete working checklist in seconds, then lets teams assign, schedule, run and analyze those checklists so recurring work is done the same way every time.

面向工业工作场所安全的 AI 驱动 JHA 与 JSA 软件
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.