
免费增值,免费试用
覆盖 459 类工作流,通过流量估算、产品功能与替代方案辅助选型。
“AI command bar” · 编程与软件开发·124 个结果
重新开始
会学习你编码品味的 AI 编程智能体

Nebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.
Nebius is an AI-focused cloud platform that gives teams non-virtualized NVIDIA GPU clusters, managed MLOps tooling, and a serverless inference layer so they can move from experiment to production on one stack.


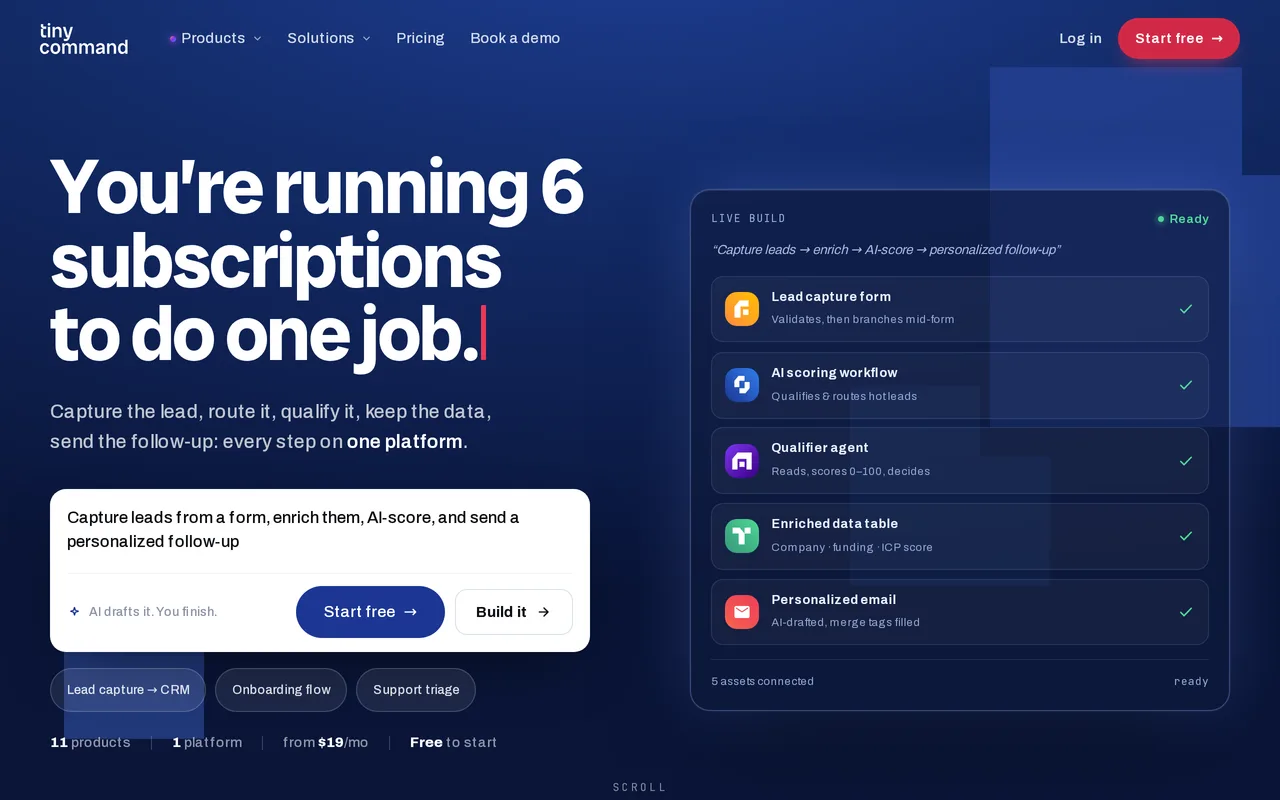
表单、工作流、AI 智能体、数据库与邮件,一个平台搞定


在整个组织内统一 LLM 评估、可观测性与红队测试标准

私密、实惠的欧盟 GPU 服务器,几分钟内配好 AI 模板
用 ChatGPT 或 Claude 管理 WordPress


Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.
Massed Compute is a cloud GPU provider offering on-demand NVIDIA instances, single-tenant bare metal servers, large InfiniBand node clusters, and a programmatic REST API and MCP server. It targets AI training, inference, machine learning, data analytics, and VFX rendering workloads.

General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
General Compute is an inference cloud built around alternative AI silicon rather than standard GPU fleets. The company buys racks of accelerators, racks them in colocation data centres, and handles the cooling, power, and networking itself. On top of that hardware it runs a disaggregated inference stack that splits each request: prompt processing runs on NVIDIA GPUs for prefill, while token generation runs on faster decode chips such as Cerebras, SambaNova, Positron AI, and d-Matrix. Customers get bare metal access or a tokens-per-second SLA.
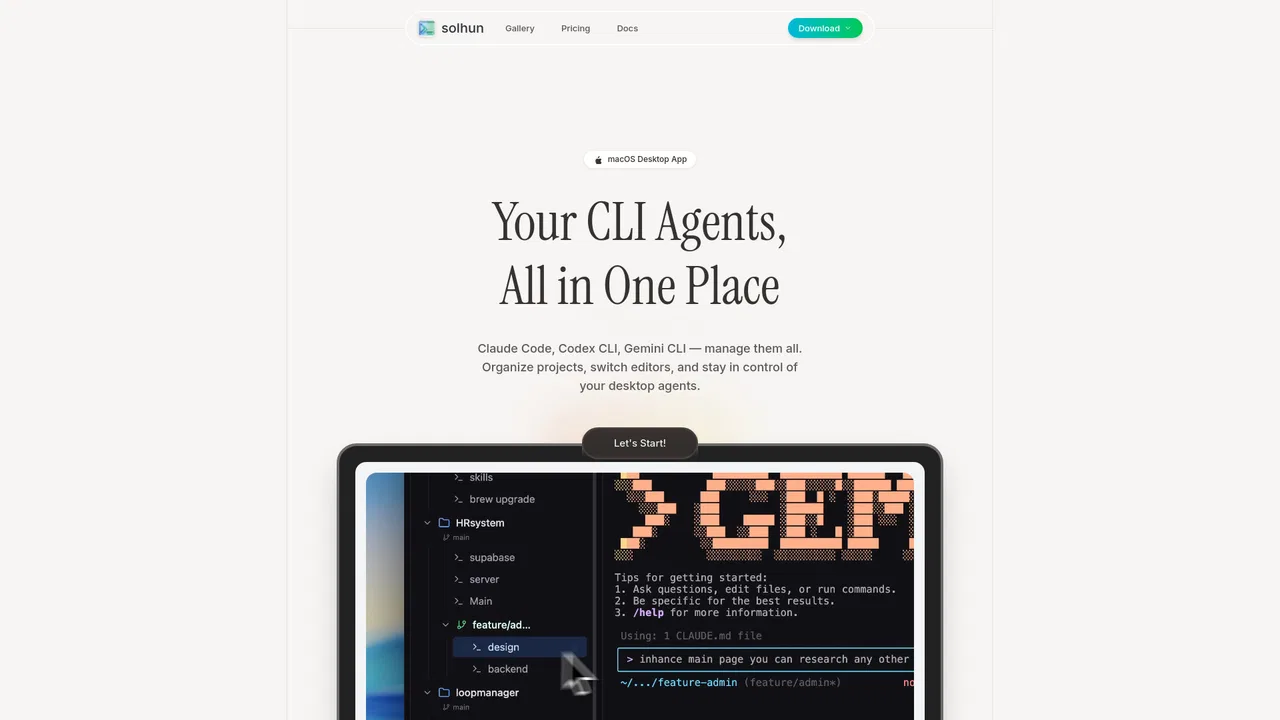
统一管理所有 AI 命令行智能体的单一控制台
NotchIA turns the MacBook notch into a functional control center for macOS. It adds an AI assistant, a now-playing panel with media controls, a calendar, clipboard and file-shelf utilities, plus a digest view — all docked in the notch area of the display.
NotchIA turns the MacBook notch into a functional control center for macOS. It adds an AI assistant, a now-playing panel with media controls, a calendar, clipboard and file-shelf utilities, plus a digest view — all docked in the notch area of the display.